Web Dashboard - ptweezy/cronstable GitHub Wiki
The web dashboard lets you monitor jobs, tail live output, review run history, and preview schedules from a browser. It supports keyboard shortcuts and is served by the optional HTTP control API, with no external assets or build step.
The dashboard is part of the HTTP interface, so it appears as soon as you add a
web section with at least one http:// or https:// listener (see the
HTTP control API for the full configuration reference):
web:
  listen:
    - http://127.0.0.1:8080
Open the listener's root path in a browser, http://127.0.0.1:8080/ for the
preceding example. The page is served at / on every http:// or https:// listener and is
self-contained, so nothing else needs to be installed or hosted.
The HTML document is returned with defense-in-depth security headers, including
a strict Content-Security-Policy (default-src 'self', connect-src 'self',
frame-ancestors 'none', anti-clickjacking X-Frame-Options: DENY, and
X-Content-Type-Options: nosniff). The daemon merges any header you set under
web.headers on top of these defaults, in any letter case, so you can relax
or extend them deliberately. A web.headers entry can't set the page's
Content-Type, Content-Encoding, ETag, Cache-Control, or Vary; the
page sets those itself.
To expose only the REST API and not the dashboard, set ui: false:
web:
  listen:
    - http://127.0.0.1:8080
  ui: false
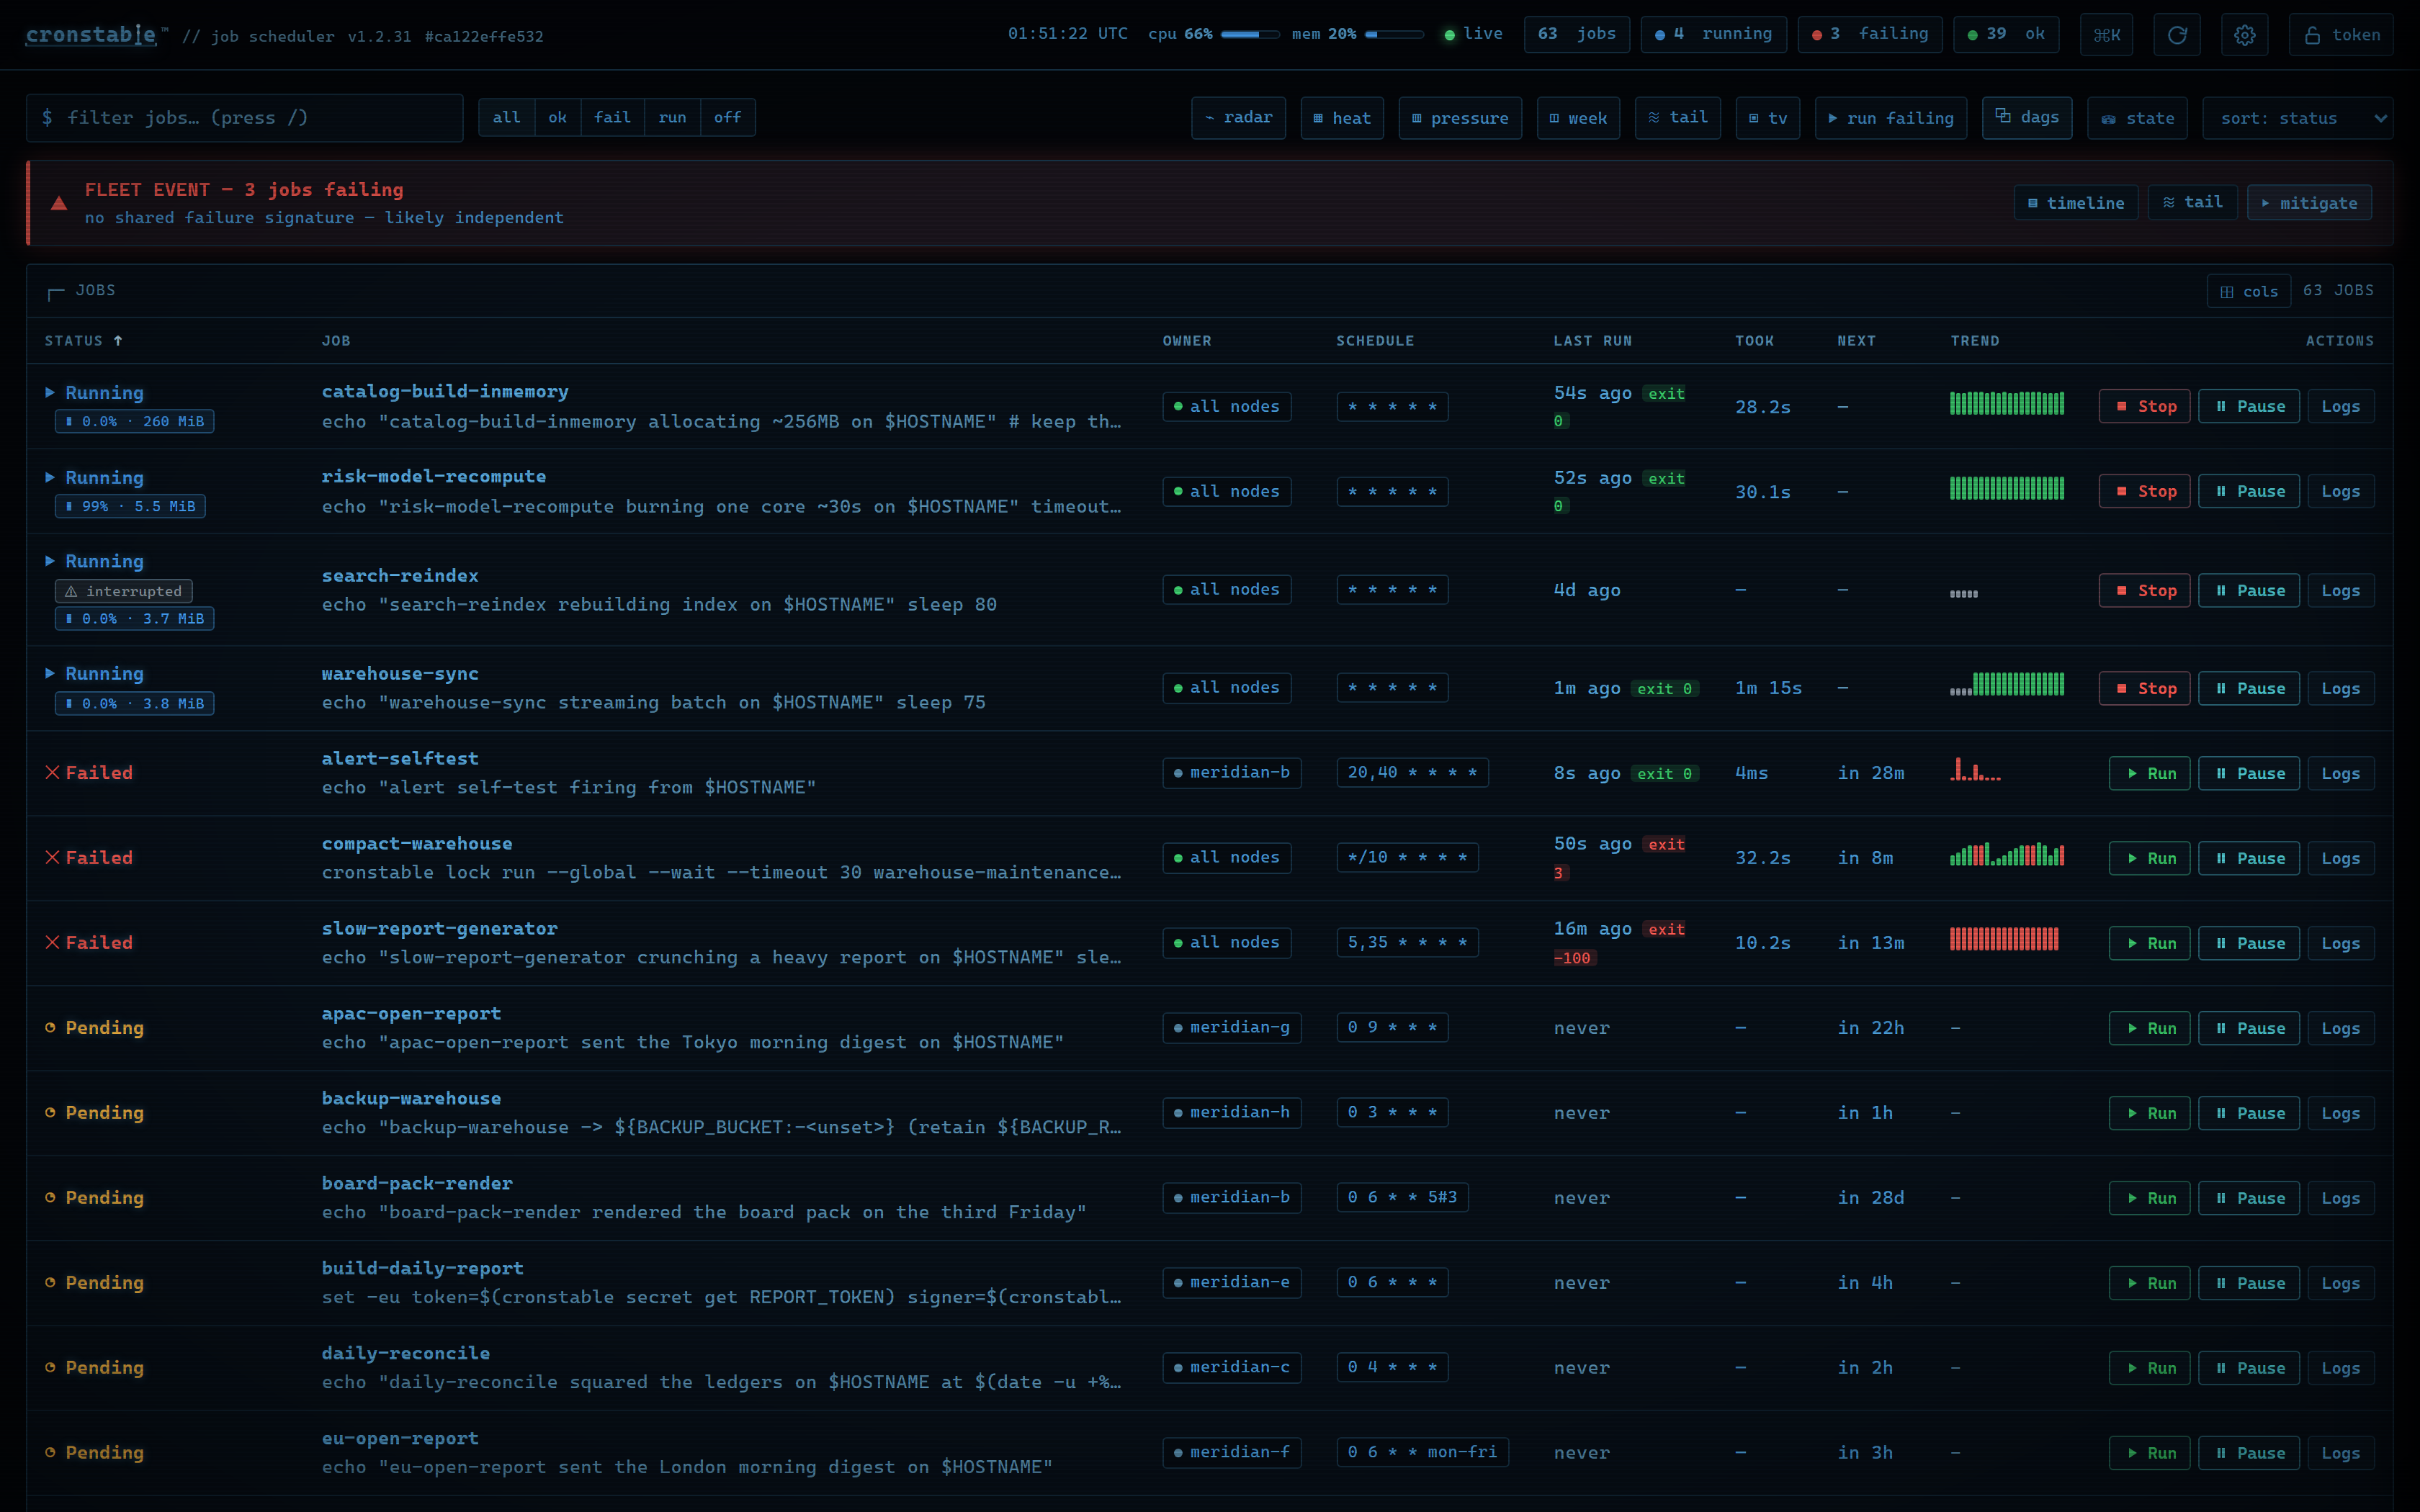
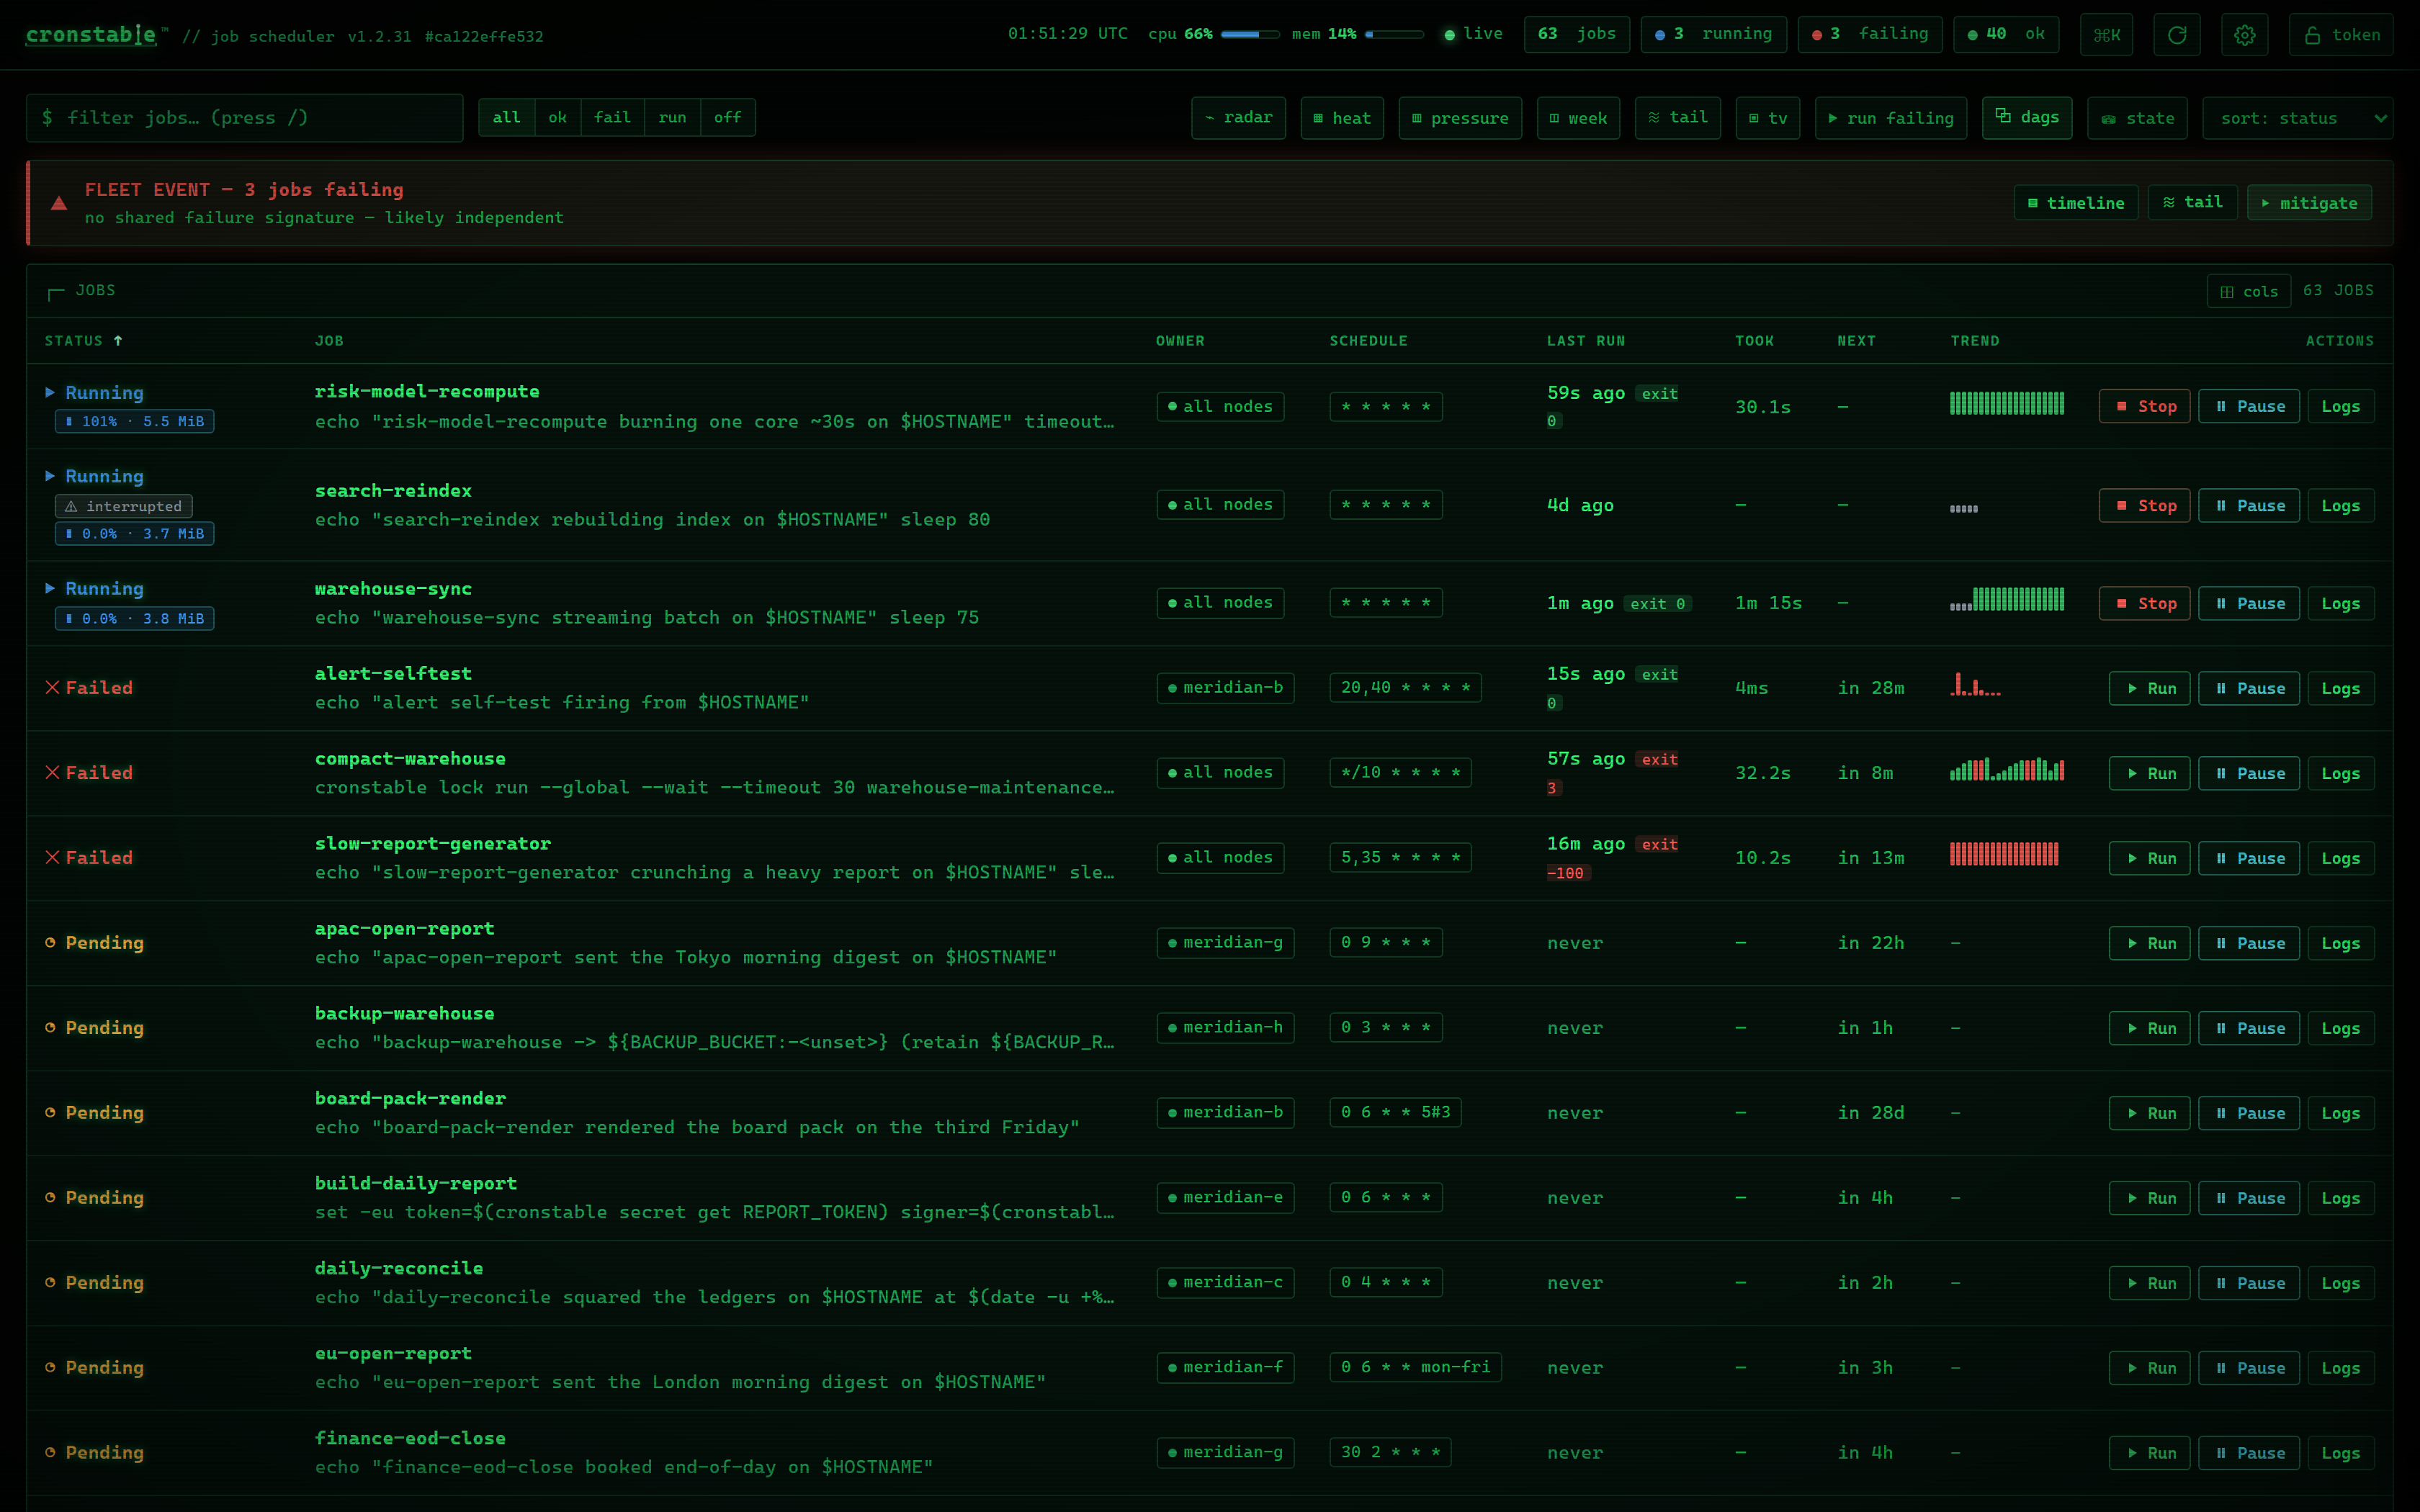
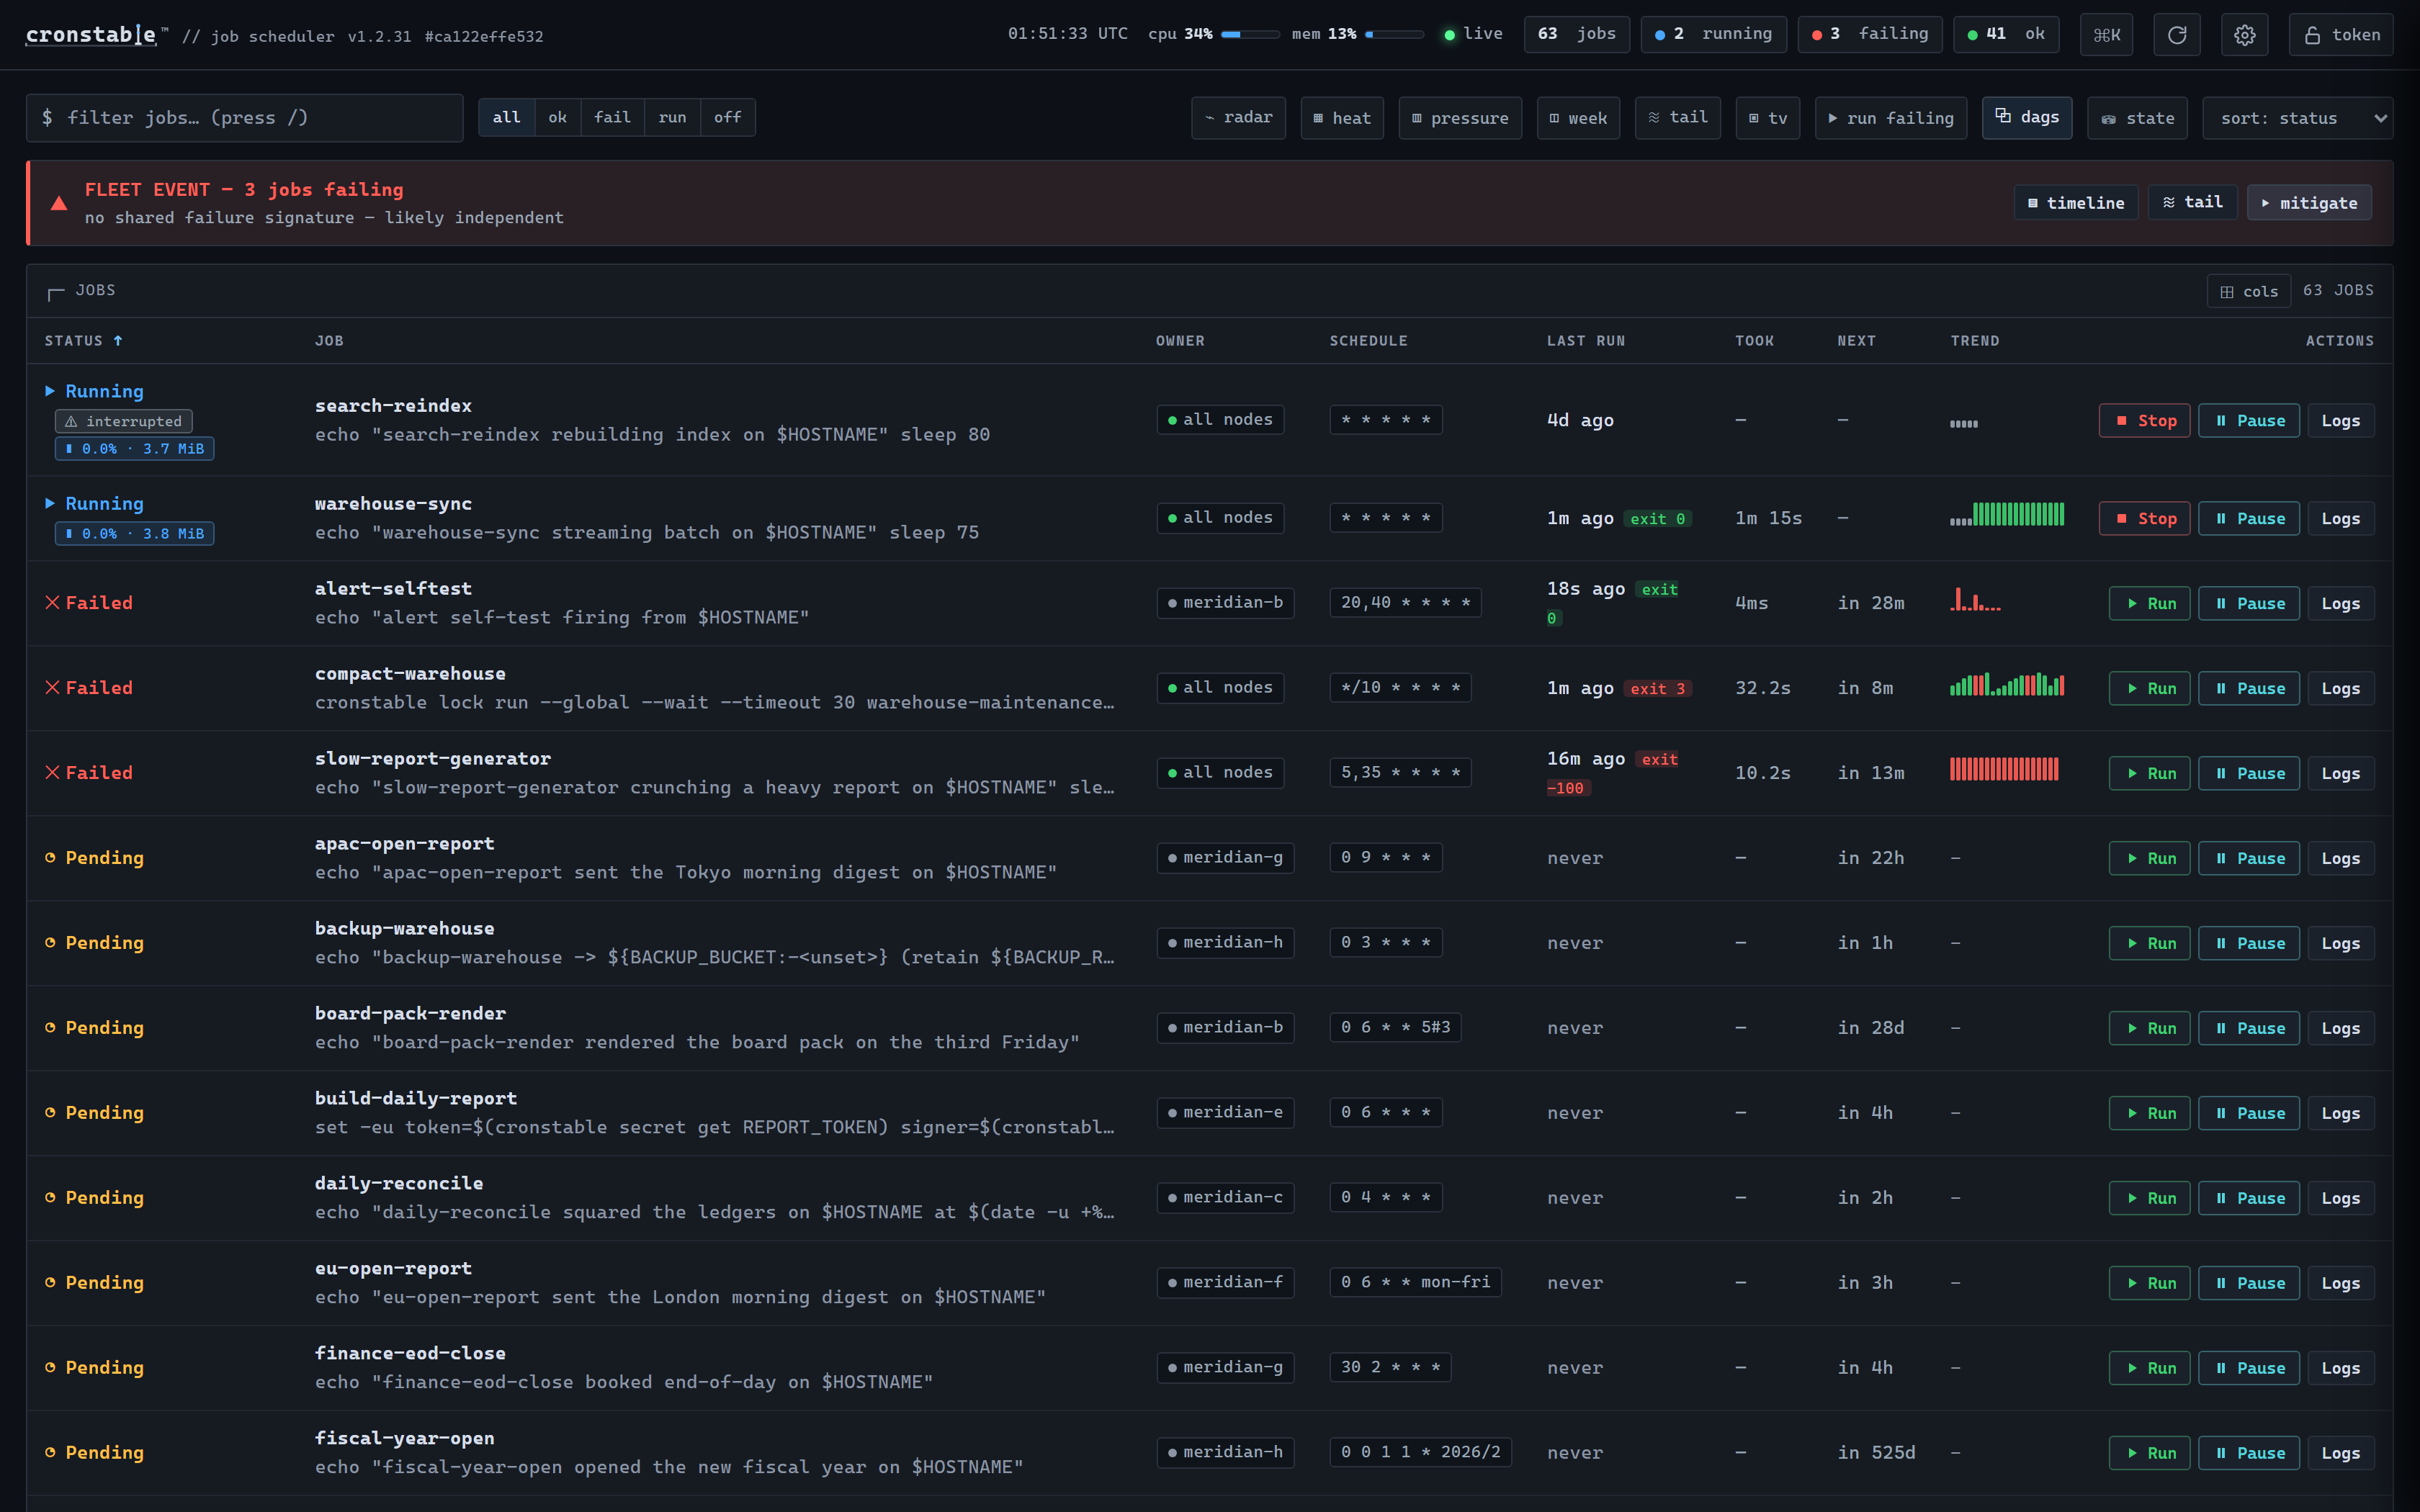
The landing page is a single sortable, filterable table of every configured job.
The header carries the wordmark (whose l is a live
pendulum simulation), the daemon's version, the
job-set ID as a short #… chip, a live UTC clock, a node
meter, a connection indicator, and summary pills counting the total
jobs and how many are running, failing, paused, and OK. Hover the #… chip for
the full id; click either chip to copy the value. The connection indicator reads
live when the server is responding and no signal when polls are failing;
hover it to see how long ago the last successful response arrived.
In a narrow window, the header hides readouts so that its buttons stay in view.
It hides the least essential ones first: the job-set ID chip, the node meter's
bars, the clock, the version and the node meter, and then the summary pills. On
a phone-width screen, the token button shows only its lock icon. In a window
about 375px wide or narrower, the connection indicator shows only its dot while
it reads live. It always shows no signal in words. Raising the
UI scale has the same effect as narrowing
the window.
The node meter shows this node's live CPU and memory bars, polled from
GET /node. It stays hidden when the host can't be read.
Clicking it toggles a node resources card charting the node's retained CPU
and memory history from GET /node/history, sampled
and bounded per web.nodeHistory. To open or
close the card from the keyboard, or when the header hides the node meter,
select Toggle node resources in the command palette. For
the sampling model, see resource monitoring.
Each row shows:
| Column | What it shows |
|---|---|
| Status | The job's current health: one of Running, Verifying (running, with its result verification in progress), Queued (waiting for a resource pool slot), Paused (a runtime pause, glyph ⏸), Failed, OK, Unknown (the last run was interrupted before it recorded an outcome), Skipped (the last scheduled slot was skipped, such as during a pause), Pending (enabled but never run yet), Cancelled, or Disabled (enabled: false), each with a color and glyph. A job late on an SLA check additionally carries an OVERDUE badge, independent of its status. |
| Job | The job name and its command. |
| Owner |
(cluster only, under distribution: spread) the node that currently owns the job. The dashboard highlights, in the accent color, the jobs owned by the node you're viewing, so you can see which work lands here. EveryNode jobs read all nodes, and a Leader job with no quorum reads no quorum. The column is hidden entirely outside spread mode. Sortable, so you can group jobs by node. |
| Schedule | The raw schedule string; hover it for a plain-English reading. |
| Last run | How long ago the last run finished (kept fresh every second) and an exit-code badge. |
| Took | The last run's duration. |
| Next | A live countdown to the next scheduled run (— while running, paused, or disabled). |
| Trend | A sparkline of recent runs: one bar per run, height by duration, colored by outcome (pause-skipped slots paint neutral, not green). |
| Actions | One-click Run (or Stop, for a running job), Pause (or Resume, for a paused job), and Logs. |
Use ⊞ cols in the table header to show or hide columns. The choice is saved per browser. The table widens as needed and scrolls horizontally if it exceeds the window. Optional columns:
| Column | What it shows |
|---|---|
| Policy |
(cluster only) the job's clusterPolicy: Leader, PreferLeader, or EveryNode; hover for what the policy means. Standalone daemons show —. Sortable, to group jobs by policy. |
| TZ | The schedule's reference frame: UTC (the default), the job's IANA timezone (such as America/Los_Angeles), or local (utc: false). Useful when a fleet mixes frames. |
| Next at | The next run as a wall-clock time in your browser's time zone (04:00, tom 04:00, Jul 12 04:00), the absolute complement to Next's countdown. The day word follows the browser's local date: the first poll after local midnight, or after the browser's UTC offset changes, rewrites every label. With polling paused, the labels update at the next refresh, filter, or sort. |
| Rate | The success percentage over the recent runs the sparkline draws, colored green / amber / red, a numeric complement to Trend. |
The toolbar above the table lets you:
-
filter by typing in the search box (matches name or command; press
/to focus it); - narrow by status with the all / ok / fail / run / queued / verifying / off segmented control;
- sort by name, status, last run, next run, or duration (from the dropdown, or by clicking a column header, including the optional Policy, Next at, and Rate columns but not TZ; clicking again reverses);
- run every failing job at once with the run failing button.
A paused job shows the Paused status with a ⏸ chip
counting down to expiry (hover for the note), counts into its own summary pill and
wallboard tile, and shows — in the Next column while its slots are
being skipped. Pausing from the dashboard is one click: the row or drawer
button, the palette, or the p key, which toggles pause/resume on the selected
job. A dashboard pause takes the default one-hour window, and the drawer's meta
line shows "paused until ... by ...". For longer or annotated pauses, use the
pause endpoint.
A job whose SLA check is breached carries an OVERDUE badge on its row, drawer, and wallboard tile, independent of its status: a job can be OK by its last run and still overdue for its next one. The row badge names the breached checks in its tooltip; the drawer header spells them out beside the badge.
Clicking a job (or pressing Enter on the selected row) opens a detail drawer
with four tabs: Logs, History, Resources, and Schedule. The
drawer header repeats the job's status, its schedule (with the plain-English
reading), the running PID(s), and a one-click button to copy the command. For a
running job with resource monitoring on, the header adds
the job's live CPU and memory. A job with resource limits
gets a chip that lists the caps it sets, such as
caps 1.5 CPU · 512 MiB · 64 procs: CPU as a number of CPUs, to as many as
six decimals (cpu: 0.0125 reads 0.0125 CPU), memory in binary units, and
processes as N procs (1 proc). Its tooltip says what happens when
the host cannot enforce the caps: a run fails under
resourceLimits.required, and otherwise goes ahead uncapped.
When leader election is
enabled, the header also shows the job's active clusterPolicy (Leader,
PreferLeader, or EveryNode), and under
distribution: spread
the node that currently owns the job (such as
cluster: Leader → cronstable-c). Jobs are deep-linkable: opening a job
updates the URL to #job/<name>, so you can bookmark or share a direct link to
it.
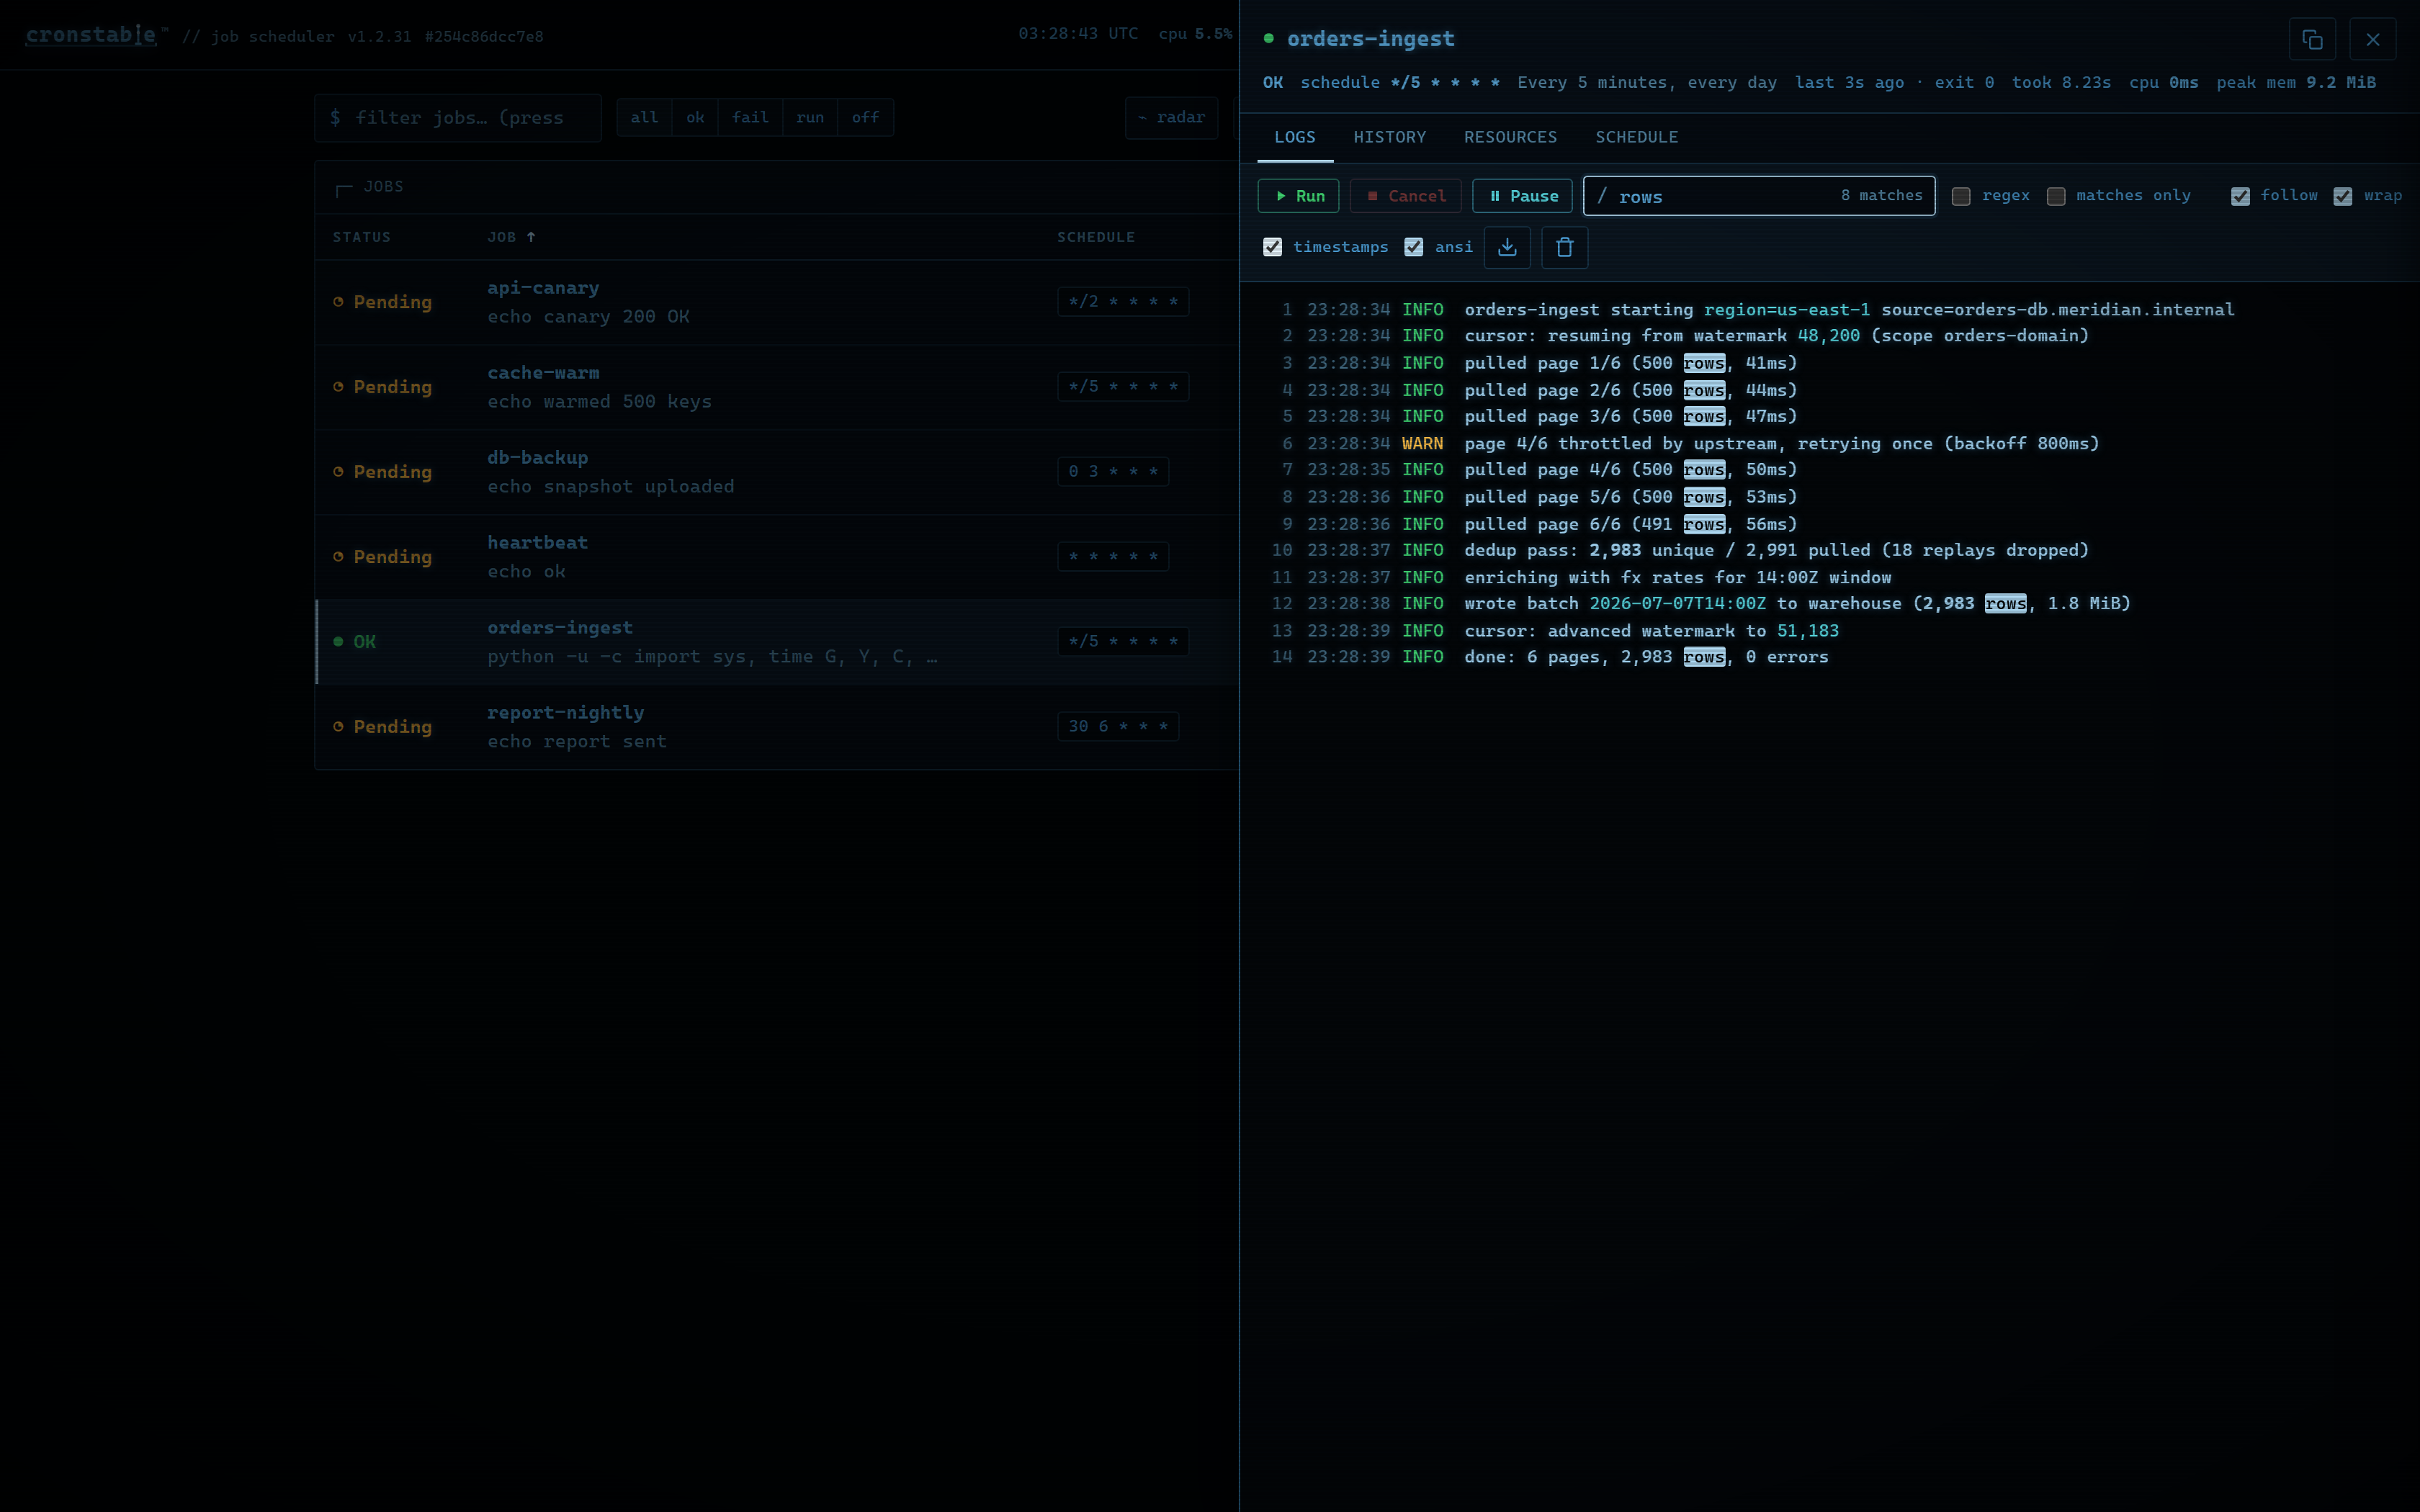
The Logs tab streams a job's captured output over Server-Sent Events: it replays the most recent buffered lines first, then appends new lines live as a running job produces them. Features:
-
ANSI color rendering (uncheck ansi to strip color codes), with
stderrlines distinguished fromstdout; - absolute line numbers and optional per-line timestamps;
- in-log search / grep, plain-text or regex, with a live match count,
Enterto jump between matches, and a matches-only mode that hides non-matching lines; - follow (auto-scroll) and line-wrap toggles;
- one-click download of the buffered log, and a clear button;
- Run, Cancel, and Pause (or Resume) buttons right above the output.
Output is only available for the streams a job captures, so enable
captureStdout / captureStderr on jobs whose output you
want to watch here. If neither is enabled, the pane says so rather than staying
empty. The view is bounded to the most recent lines, so a job with heavy output
can't grow the tab without limit.
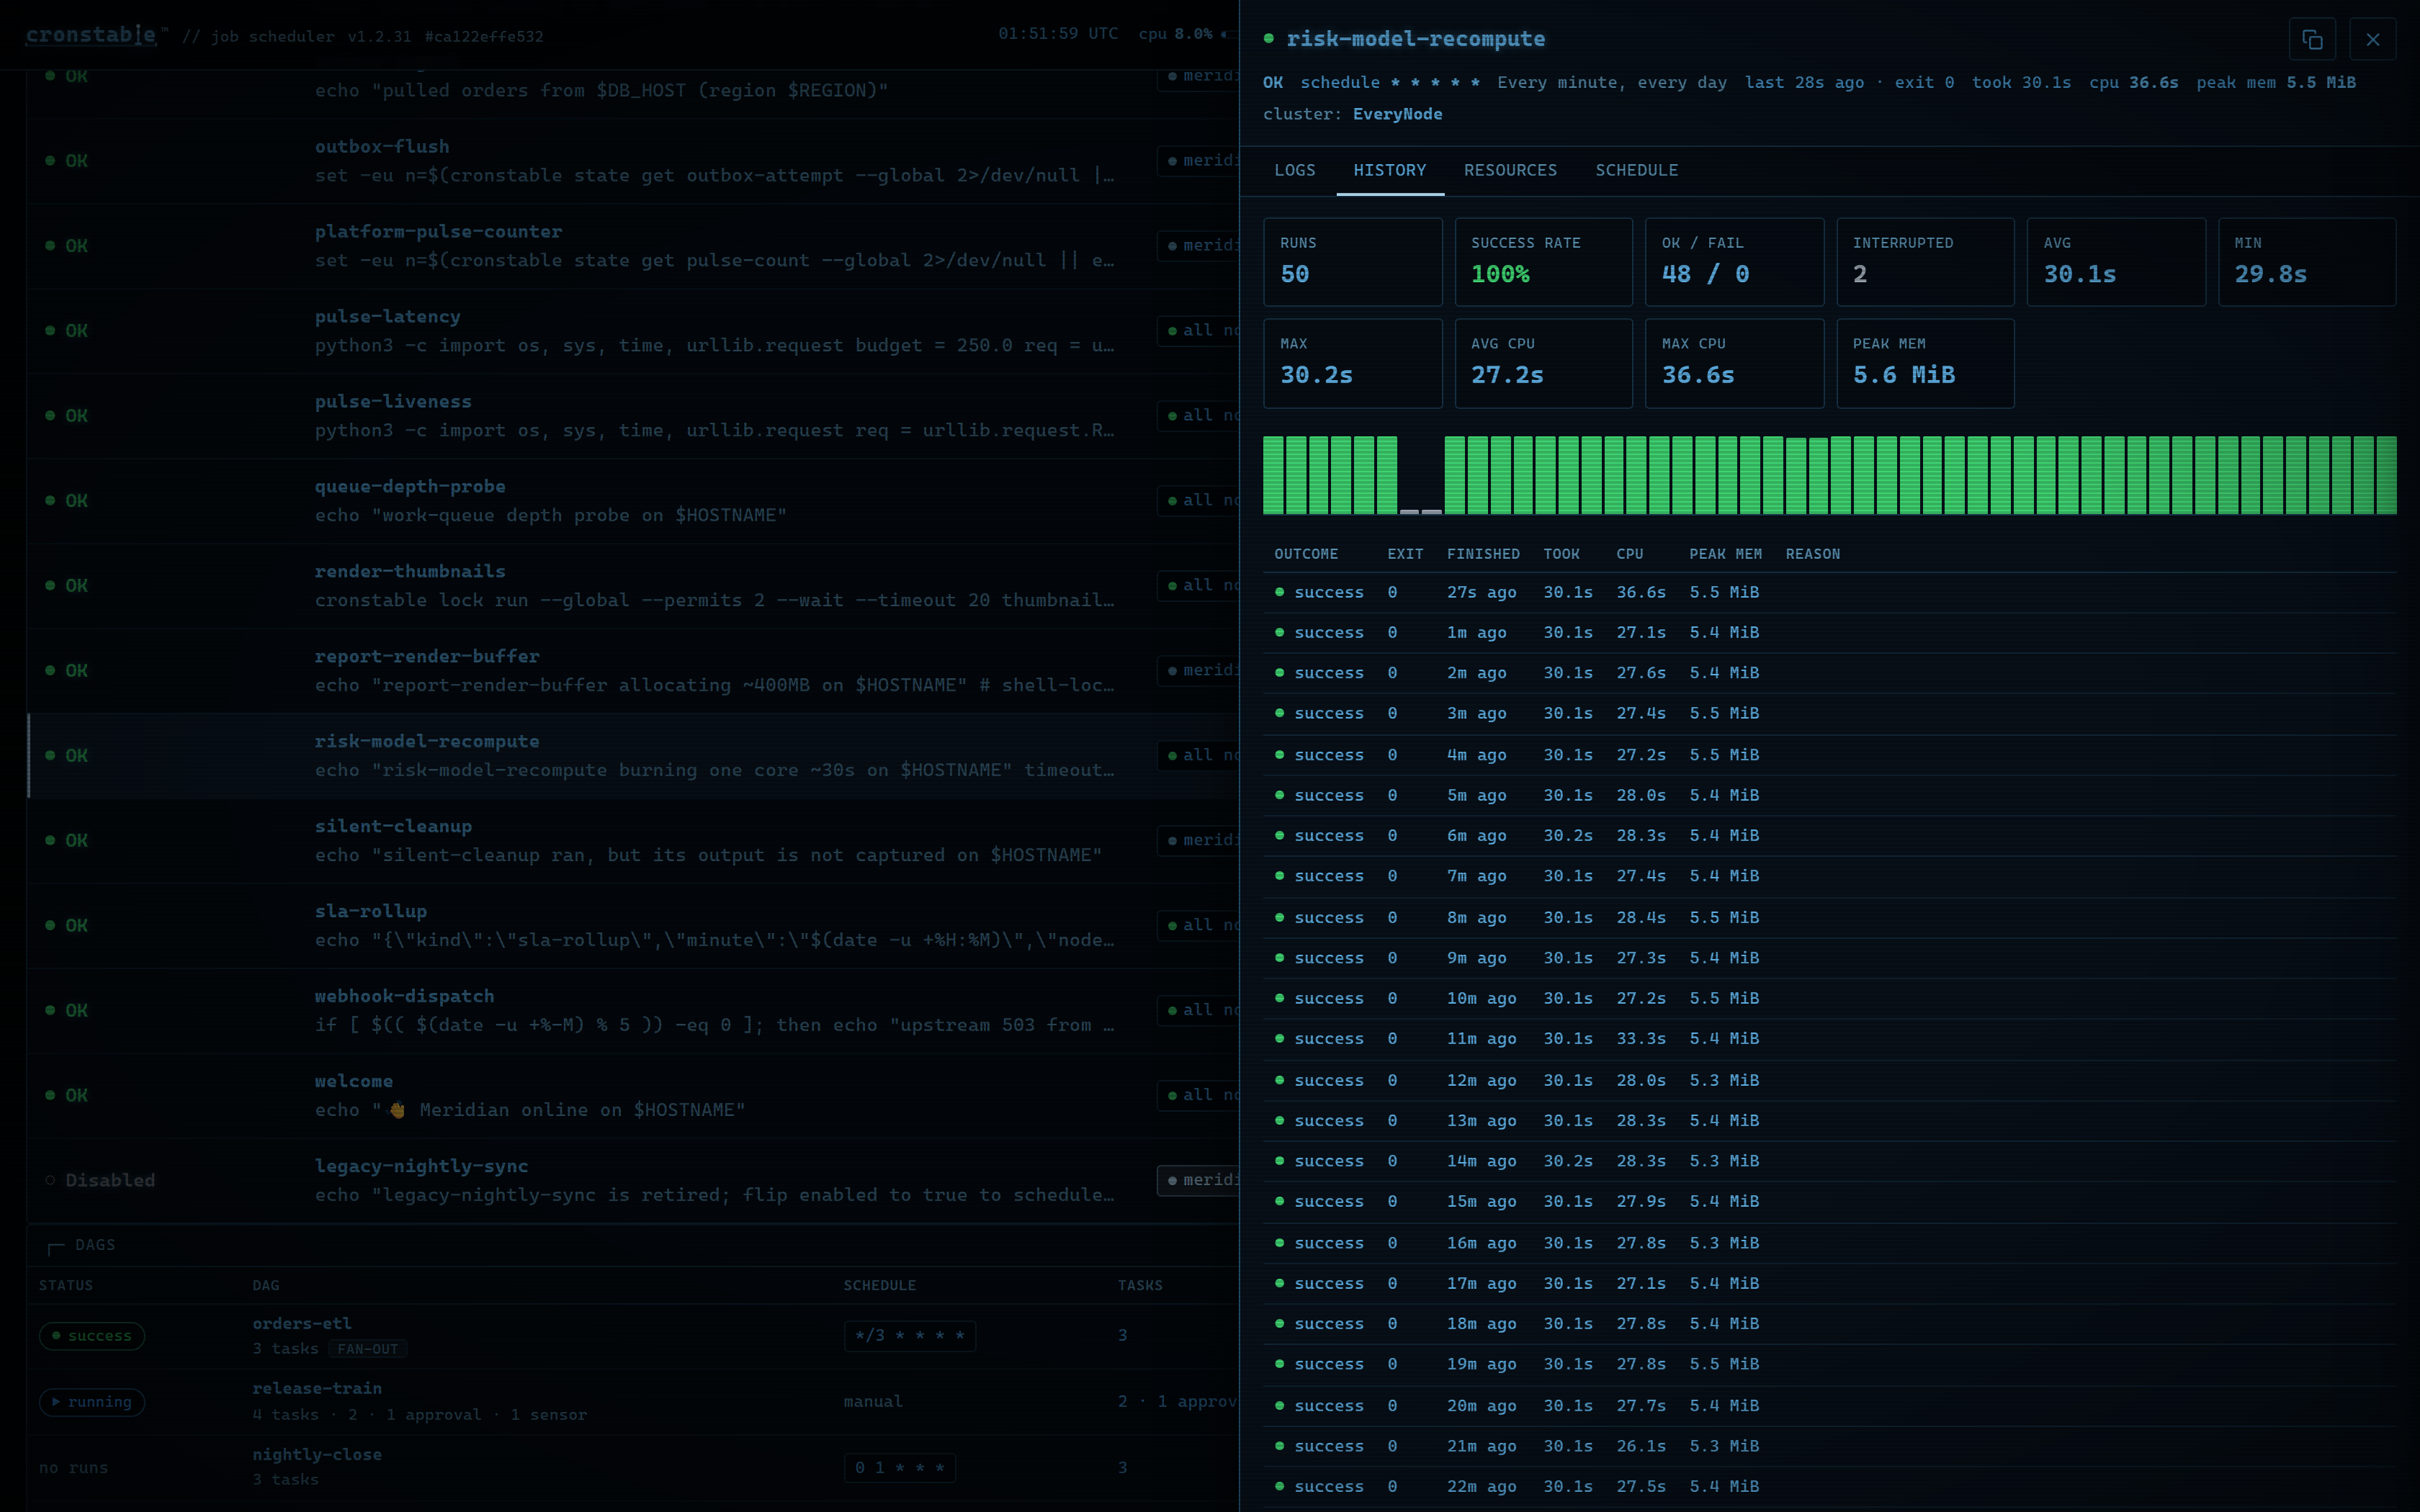
The History tab summarizes the job's retained run history:
- a stats grid: total runs, success rate, OK / fail counts, and average / min / max duration. The success rate is computed over runs that ran to completion, so deliberate cancellations are excluded;
- a duration bar chart, one bar per run (newest on the right), colored by outcome;
- a run table: outcome, exit code, when it finished, how long it took, and a reason for any run that carries one (failed runs, and runs cancelled from the dashboard). For a job with resource limits, the Reason cell adds a red memory cap chip when the run was killed at its memory cap (tooltip:
killed at its memory cap (512 MiB)), a red check memory cap chip when the cap killed the run's verify check (tooltip:verify check killed at its memory cap (512 MiB)), and an amber caps not enforced chip when a configured cap did not apply, refused runs included (tooltip:caps not enforced (<resources>): <reason>). A run whose caps all applied shows no chip.
History is held in memory, up to the most recent 50 runs per job, and normally resets when cronstable restarts. With a durable state store configured, it is rehydrated from the durable run ledger on startup, so pre-restart runs appear immediately. Rehydrated runs carry outcomes, timings, and exit codes, not captured output: the Logs tab never replays output from before a restart.
The Resources tab charts the CPU and memory of jobs that opted into
resource monitoring (monitorResources). The dashboard
fetches the data lazily from
GET /jobs/{name}/resources when you open the
tab, never on the poll loop:
- selector chips switch between each currently-running live instance (with its PID) and the recent recorded runs (each with its outcome glyph and age);
- two charts plot CPU % and memory (RSS) over the selected run, from the sampled series the daemon records (downsampled server-side, so a run of any length stays chart-sized);
- a summary line gives a recorded run's outcome, duration, total CPU time, peak memory, and sample count, or, for a live instance, the sampling interval and the CPU used so far;
- with more than one sampled run, trend strips chart CPU time and peak
memory for each sampled run (newest on the right, colored by outcome);
clicking a bar opens that run. A recorded run with no samples, such as a
refused run or a start failure, has a selector chip but no bar, and opens
to
no samples yetwith its summary line, limits included; - a monitored job with no recorded or sampled run shows its caps line, when
it sets caps, and
No resource samples yet. A run is charted here once it has been sampled.The tab keeps refetching and charts the first run once it has been sampled; - the live view keeps refetching while the tab stays open, at a selectable 1s / 2s / 5s / 10s pace.
For a job with resource limits, the charts also draw its caps:
- a dashed cap line on the CPU chart at the CPU cap times 100%, labeled
like
cap 150%, and on the memory chart at the memory cap, labeled likecap 512 MiB. The y axis always extends past the cap, so the line stays in view; - after a memory kill, the memory cap line turns red and reads
cap 512 MiB · hit. A cap that the host did not apply reads likecap 150% (not enforced); - each cap line belongs to the run it is drawn for: a recorded run shows the caps it ran under, and a live run shows the configured caps;
- the hover tooltip lists each cap under its series,
cap 150%andcap 512 MiB (kernel-counted, not RSS). The memory chart plots sampled RSS, while the cap counts the kernel's figure (cgroup memory on Linux, commit charge on Windows), so the two can differ; - the summary line of a recorded capped run can add
memory cap hit,caps not enforced (<resources>): <reason>,kernel peak <size>(the most memory the kernel counted for the run, in the cap's size format),cpu throttled <duration>(Linux only), andprocess cap hit N×. A run's selector chip tooltip ends in· memory cap hitafter a memory kill.
For an uncapped job that never opted in, the pane reads
Resource monitoring is off for this job. and shows the monitorResources
line to add. A capped job without monitoring shows its
caps instead (caps <caps>, followed by · required under
resourceLimits.required) above a table of its recent capped runs, with
the columns Started, Outcome, Enforced (yes, no, or refused, with
the reason in a tooltip), Kernel peak, CPU throttled, and Cap hits
(memory, processes ×N, or —). With no capped run recorded yet, the
pane reads No capped runs recorded yet. in place of the table. The hint
below reads Opt in with monitorResources: true to chart CPU and memory per run against these caps. Monitored jobs also surface outside the
drawer: a running job's row carries a live CPU%/memory chip in its status
cell, and the drawer header repeats the live readings while the job runs.
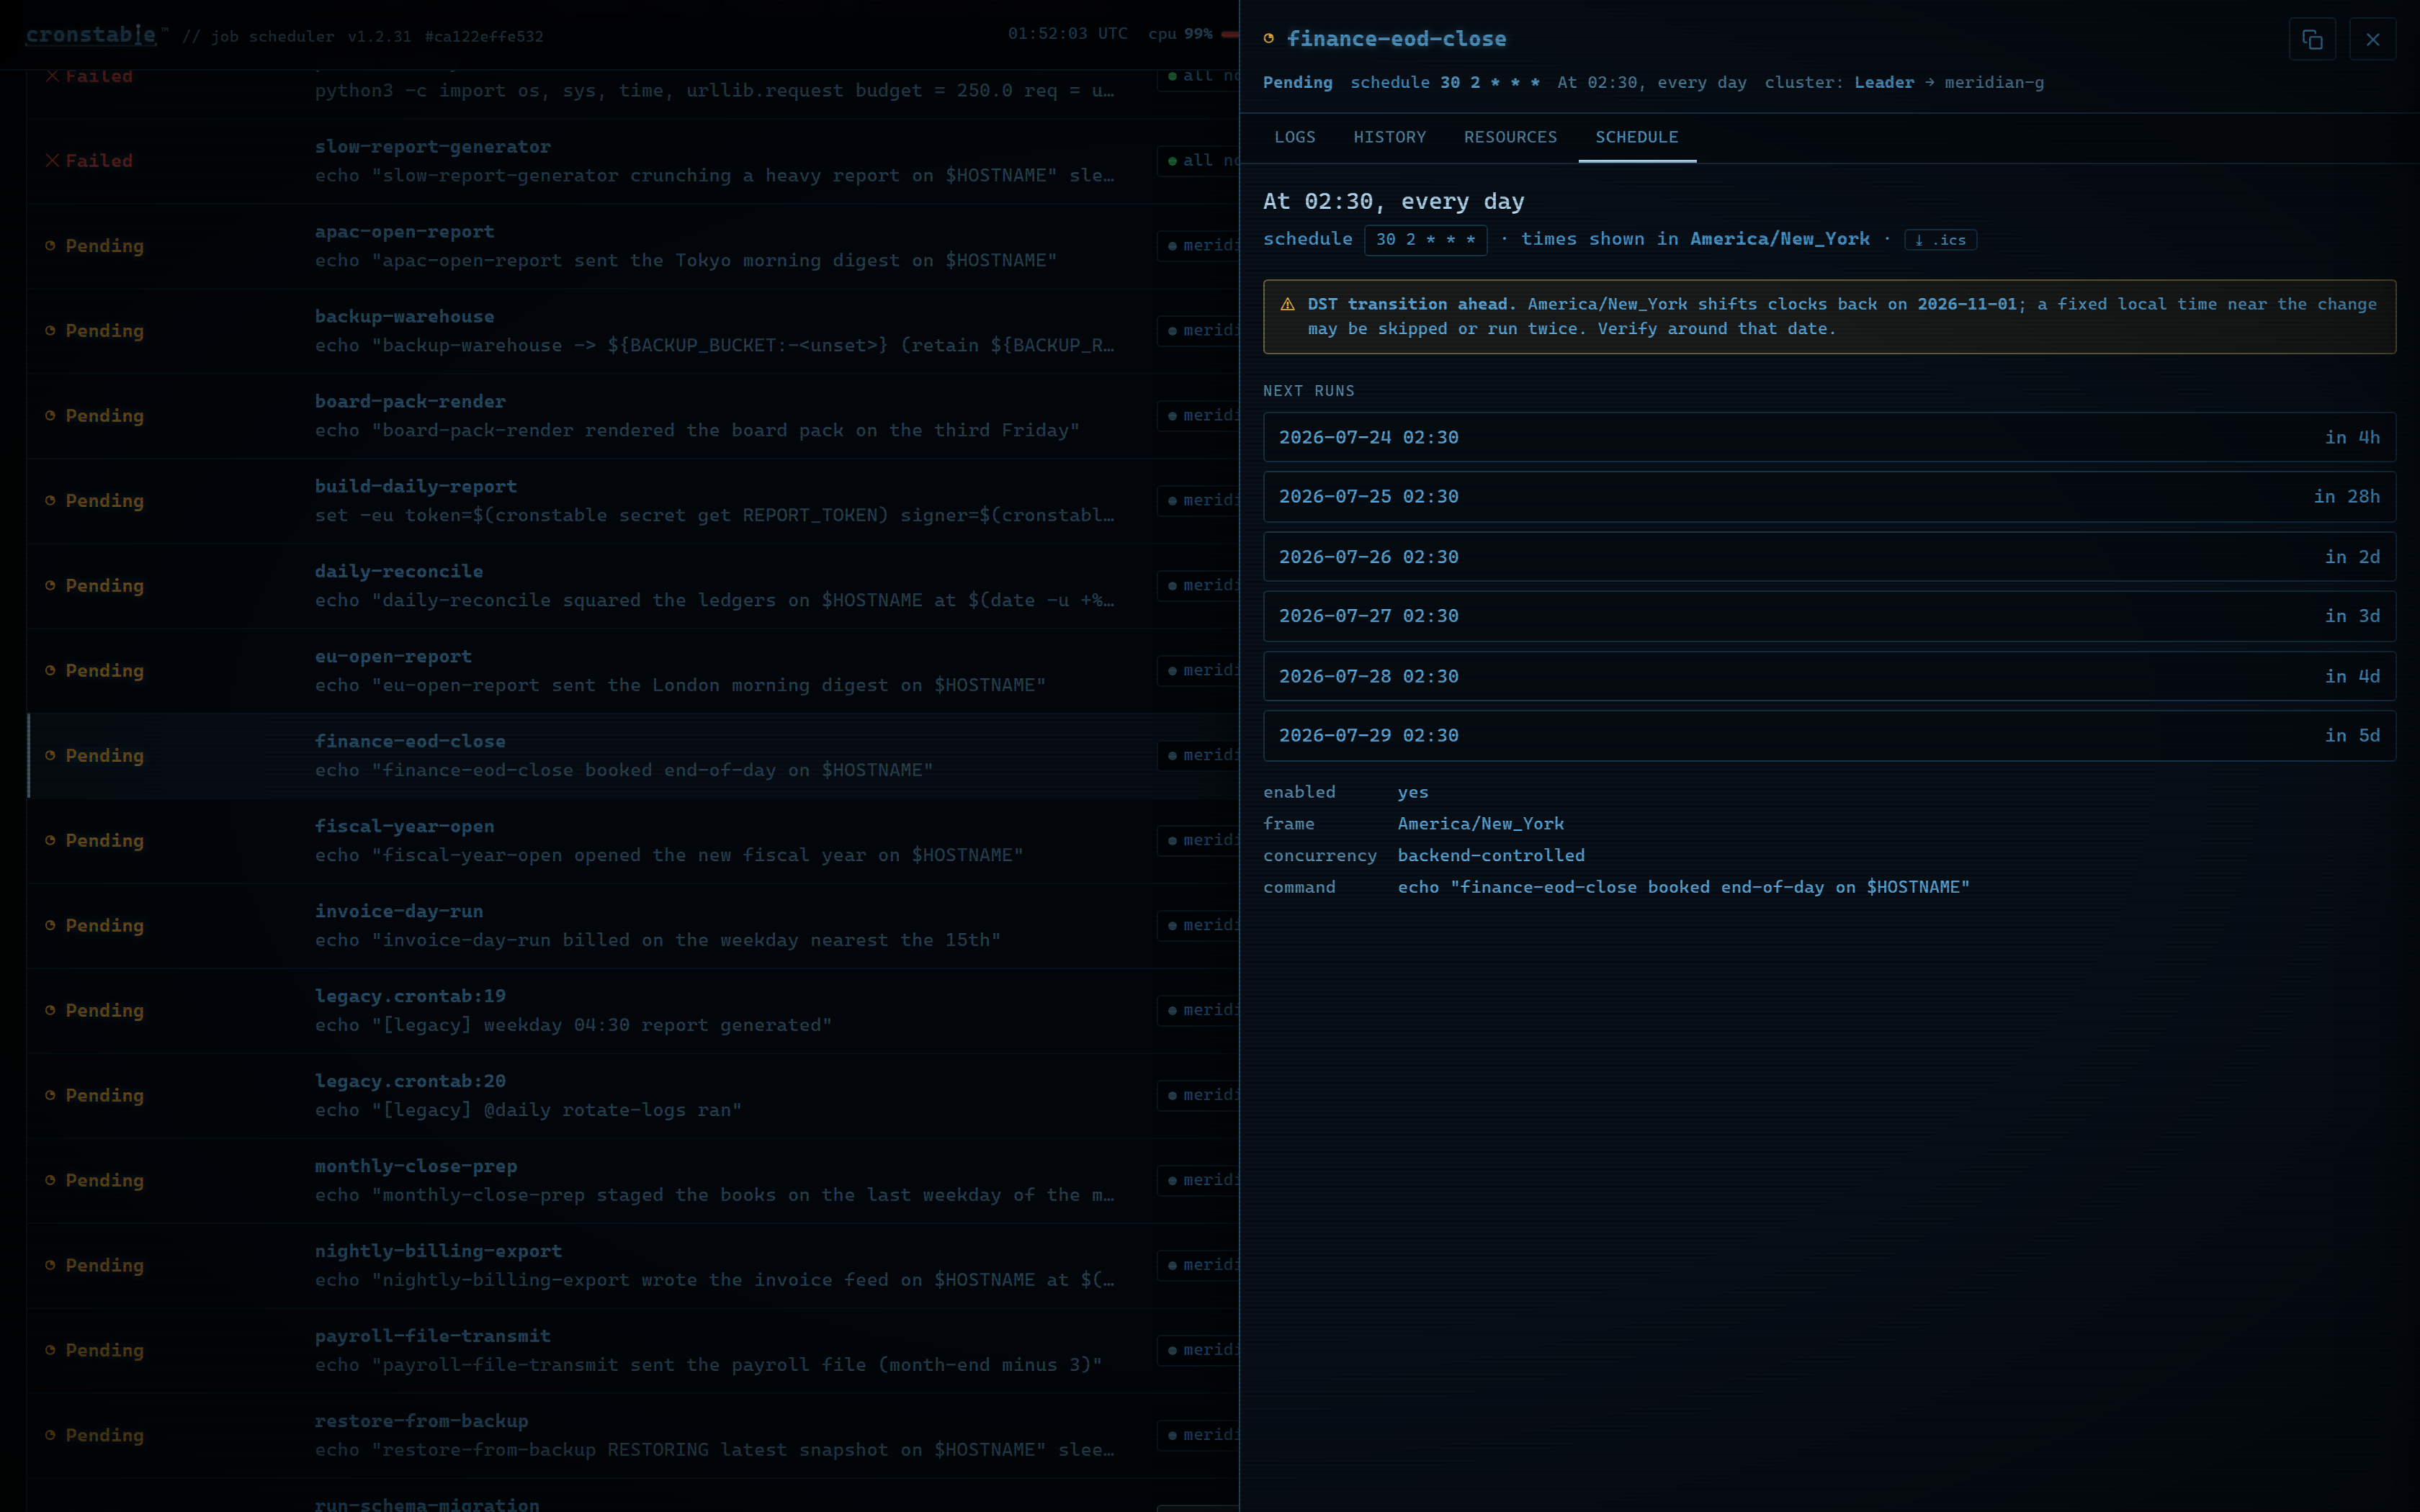
The Schedule tab turns the cron expression into a plain-English reading:
- a plain-English description (for example, "At 19:27, on Monday and Friday"), understanding ranges, steps, lists, names, and the
@daily/@hourly/@rebootmacros; - a preview of the next run times, computed live in the browser and shown in the job's own time zone (UTC or an arbitrary IANA zone such as
America/Los_Angeles; autc: falsejob is shown in the browser's local zone, labeled "server local — approximate"), each with a relative countdown; - impossible schedules (such as the 31st of February) are detected and called out rather than described as if they will fire;
- a key/value summary of whether the job is enabled, its time zone frame, a concurrency note, and its command.
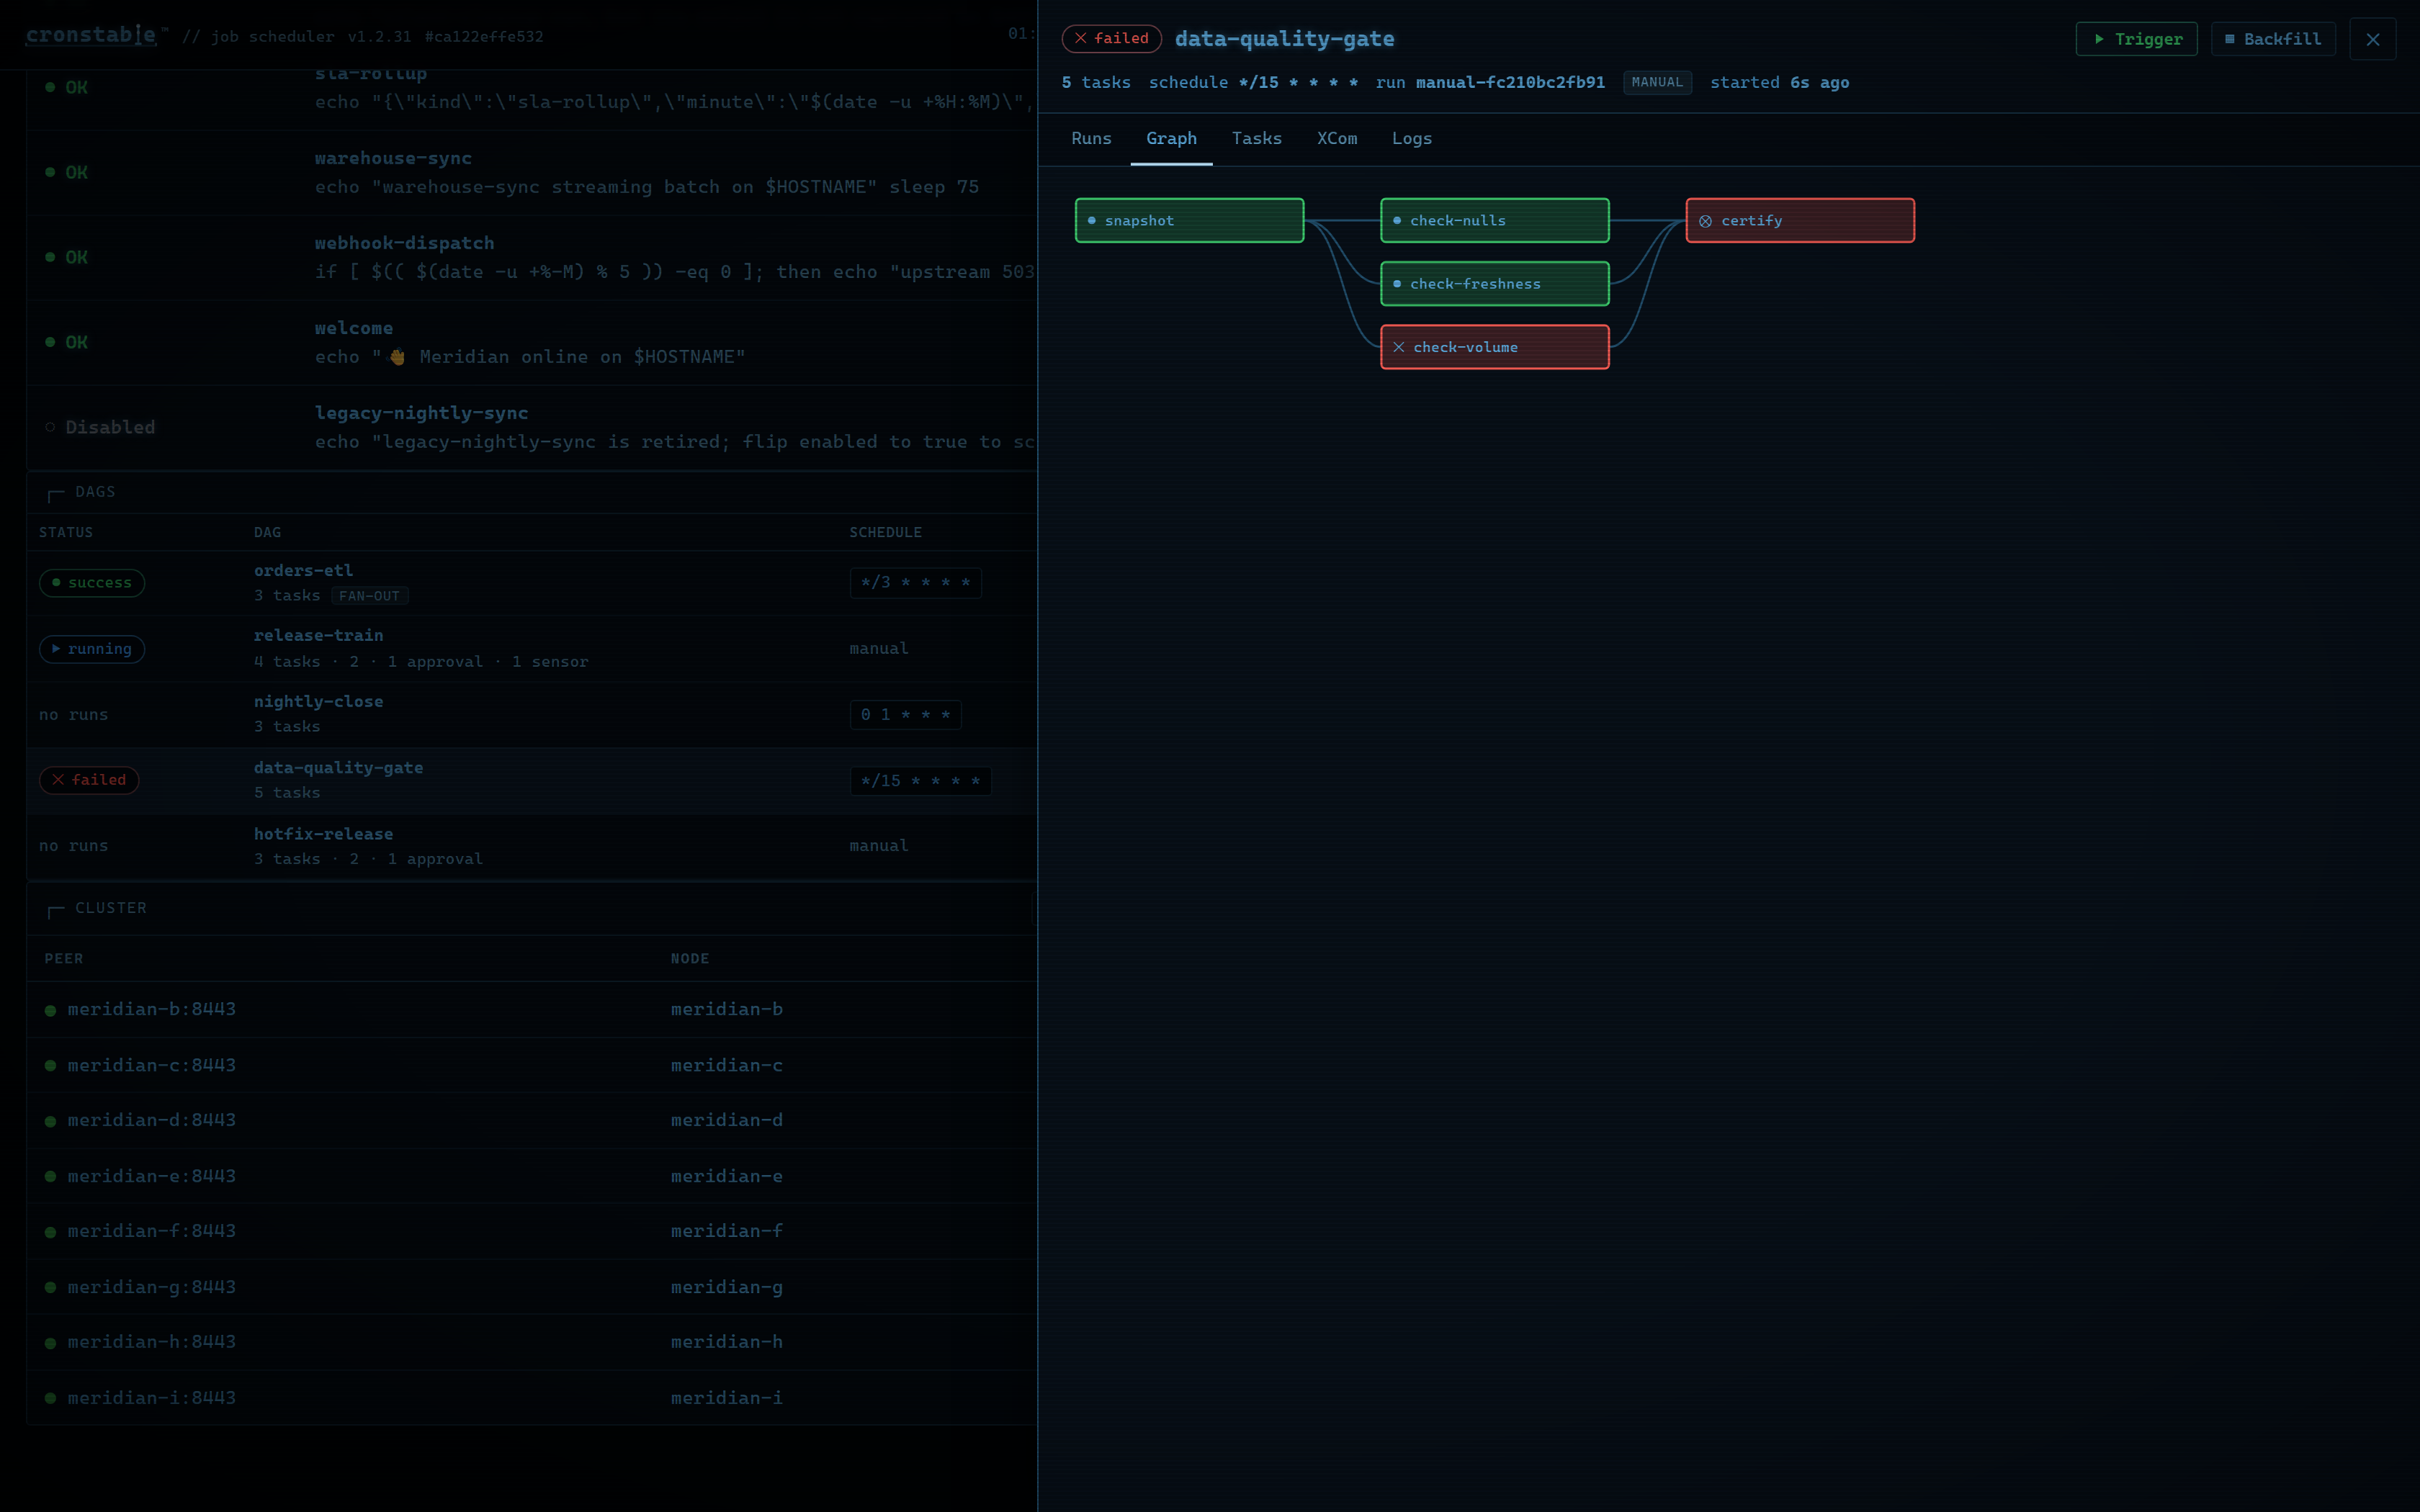
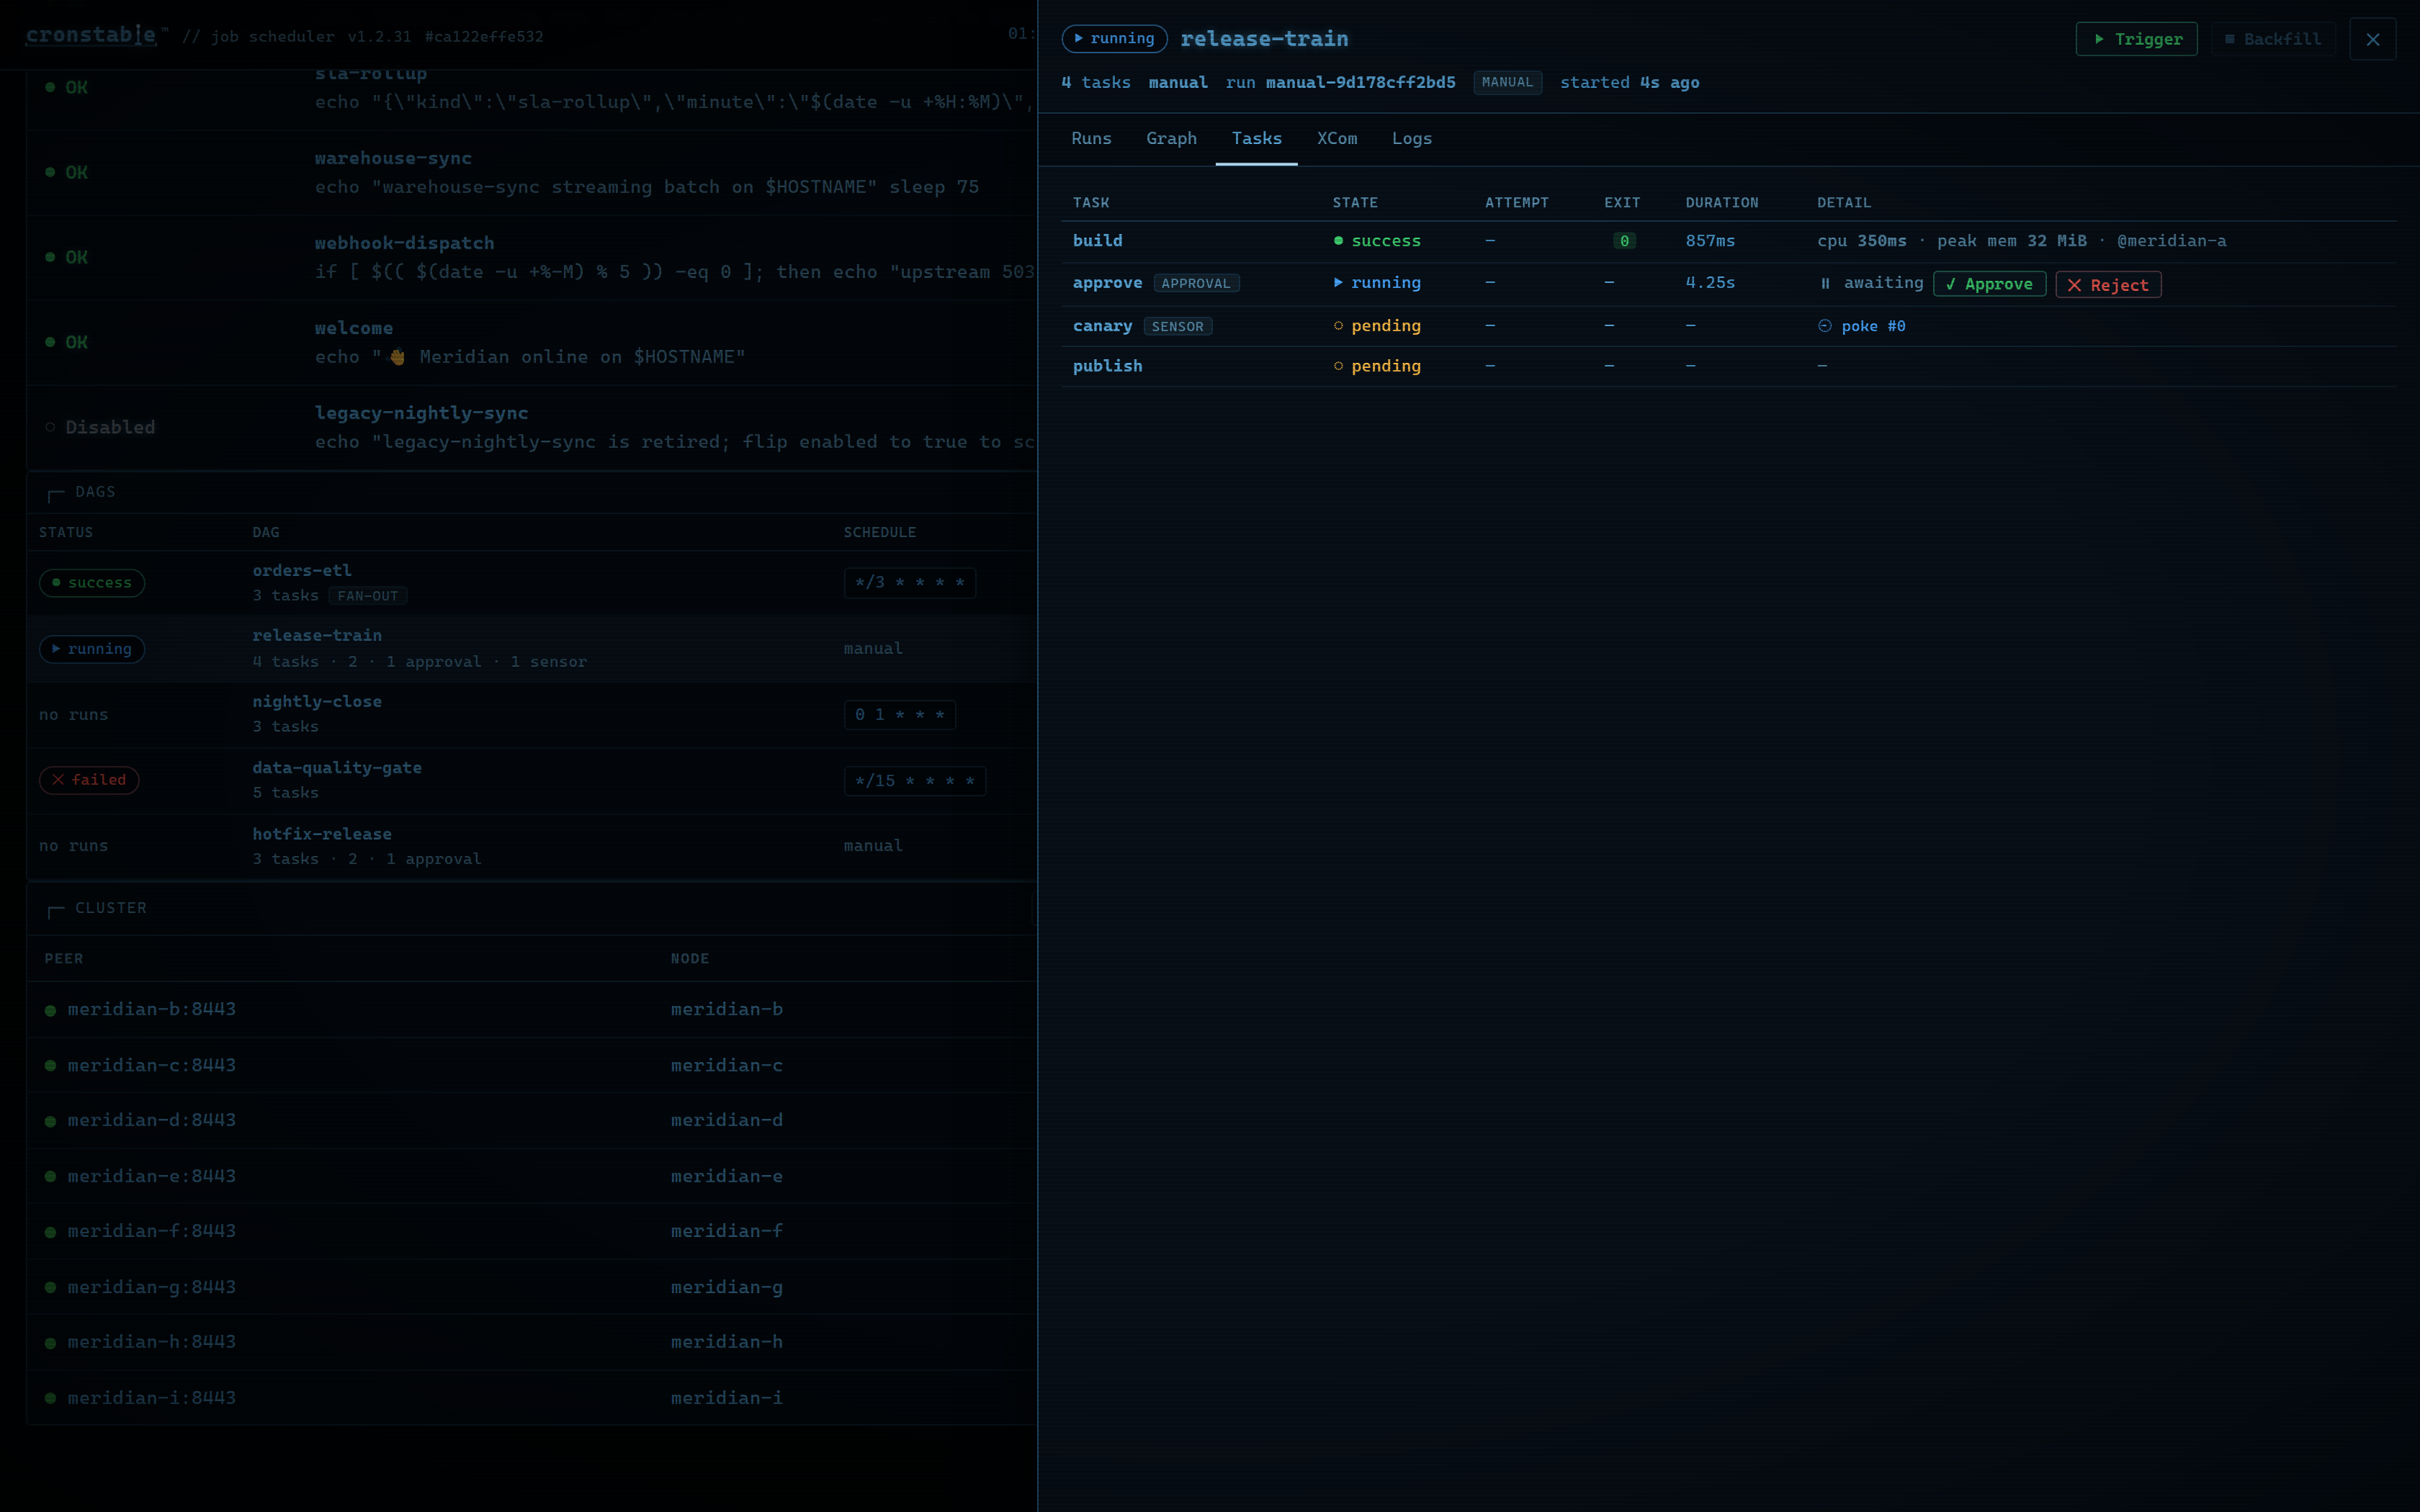
| The task graph | A human approval gate |
|---|---|
 |
 |
When a dags: section is configured, a ⧉ workflows
toolbar button appears; it stays hidden otherwise, like the cluster panel. The
button toggles the workflows card (also Toggle workflows in the command
palette): one row per DAG with its latest run's state, its name and task count
(a fan-out badge marks a DAG with mapped tasks), its schedule (hover for the
plain-English reading; manual for an unscheduled DAG), a stacked bar of recent
run outcomes, the total run count, and one-click Run / Open actions.
Open (or clicking a row) opens the DAG drawer, with Trigger, ▦ Backfill, and Retry failed tasks buttons in its header and five tabs:
- Runs: recent runs, newest first, each with its state and a per-state task tally; selecting a run drives the other tabs.
- Graph: the task graph, each node colored by its task's state as the run advances.
-
Tasks: per-task state, attempts, and timings. An
approval gate that is awaiting a
decision shows ✓ Approve / ✕ Reject buttons, and the decision is
recorded as made by
dashboard; a gate decided elsewhere in the meantime answers "This task is no longer waiting for approval. Refreshing its status." A sensor shows its poke count and next poke, and a task awaiting retry shows when the next attempt is due. - XCom: the values the run's tasks published.
- Logs: pick a task and tail a running instance's live output (an SSE stream like the job drawer's Logs tab, from the task-log endpoint).
Trigger (and the card's Run button) starts a manual run now with
POST /dags/{name}/trigger. In the drawer, the
new run is selected as soon as it is created. ▦ Backfill opens a from/to ISO
date-range form wired to
POST /dags/{name}/backfill. It is disabled
only without the control scope. For a manual-only DAG the form forces
Failed dates only, which posts to /dags/{name}/recover instead.
Retry failed tasks previews recovery of the selected failed run's failed
tasks (see workflow recovery). DAG
runs are deep-linkable like jobs: the URL tracks #dag/<name> (and
#dag/<name>/<run_key> with a run selected), so you can bookmark a run or paste
it into an incident channel.
See orchestration and DAGs for task types, retries, approval gates, and configuration, or the HTTP control API for endpoint details.
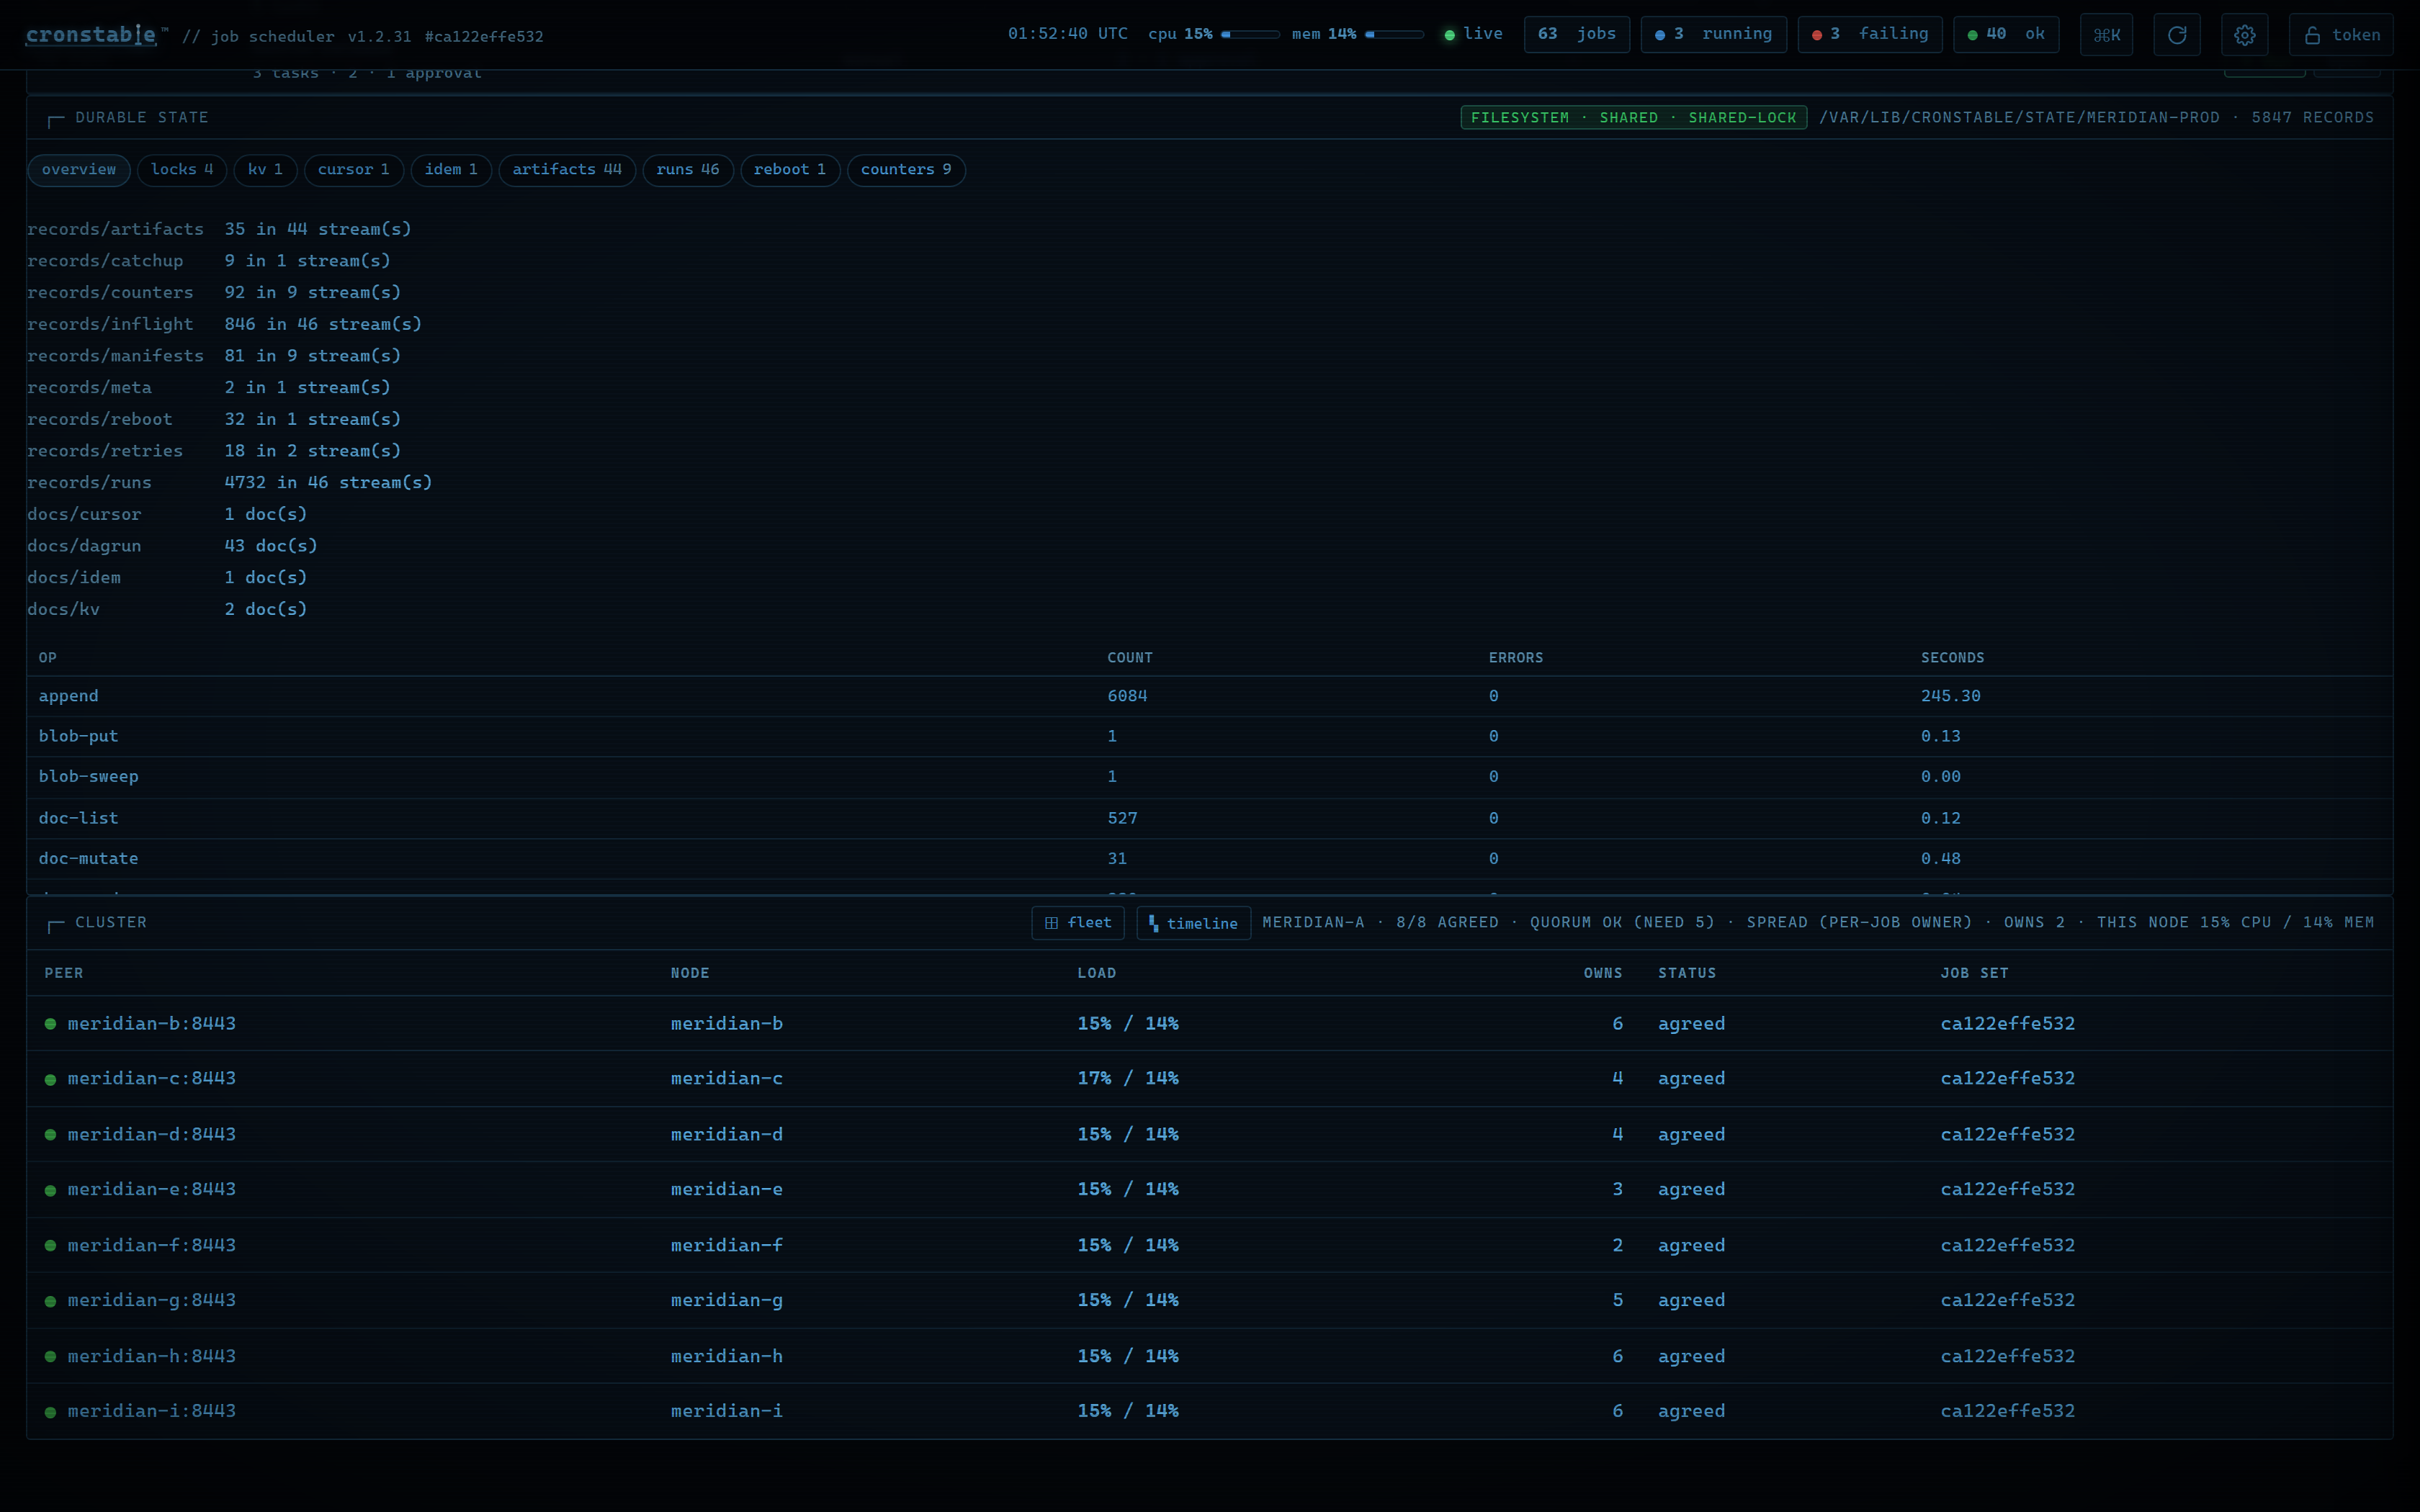
When a durable state backend is enabled, a ⛁ state
toolbar button appears and toggles the saved state card (also Toggle
state inspector in the command palette). The page probes GET /state once at
load to decide; without a backend the button never shows. The card headlines the
backend and topology (with a shared-lock chip where that applies), the store
path, the total record count, and a quarantine count when present. It then
splits into sub-tabs built from what the store holds:
- overview: per-kind record and document counts, plus a per-operation table of counts, errors, and time spent;
- retries and slots: this node's armed retries (attempt, next retry, backoff) and held concurrency slots;
- locks: active leases with holder, fencing token, and expiry;
-
kv, cursor, idem, artifacts, runs, reboot,
counters: one tab per primitive present in the store, listing its
scopes with entry counts; inspect drills into a scope's entries with the
state inspector endpoints
(
GET /state/documents/GET /state/records).
The inspector shows metadata only, including value types and sizes. It does not fetch record payloads, KV values, or archived output. After the startup probe, it polls only while open.
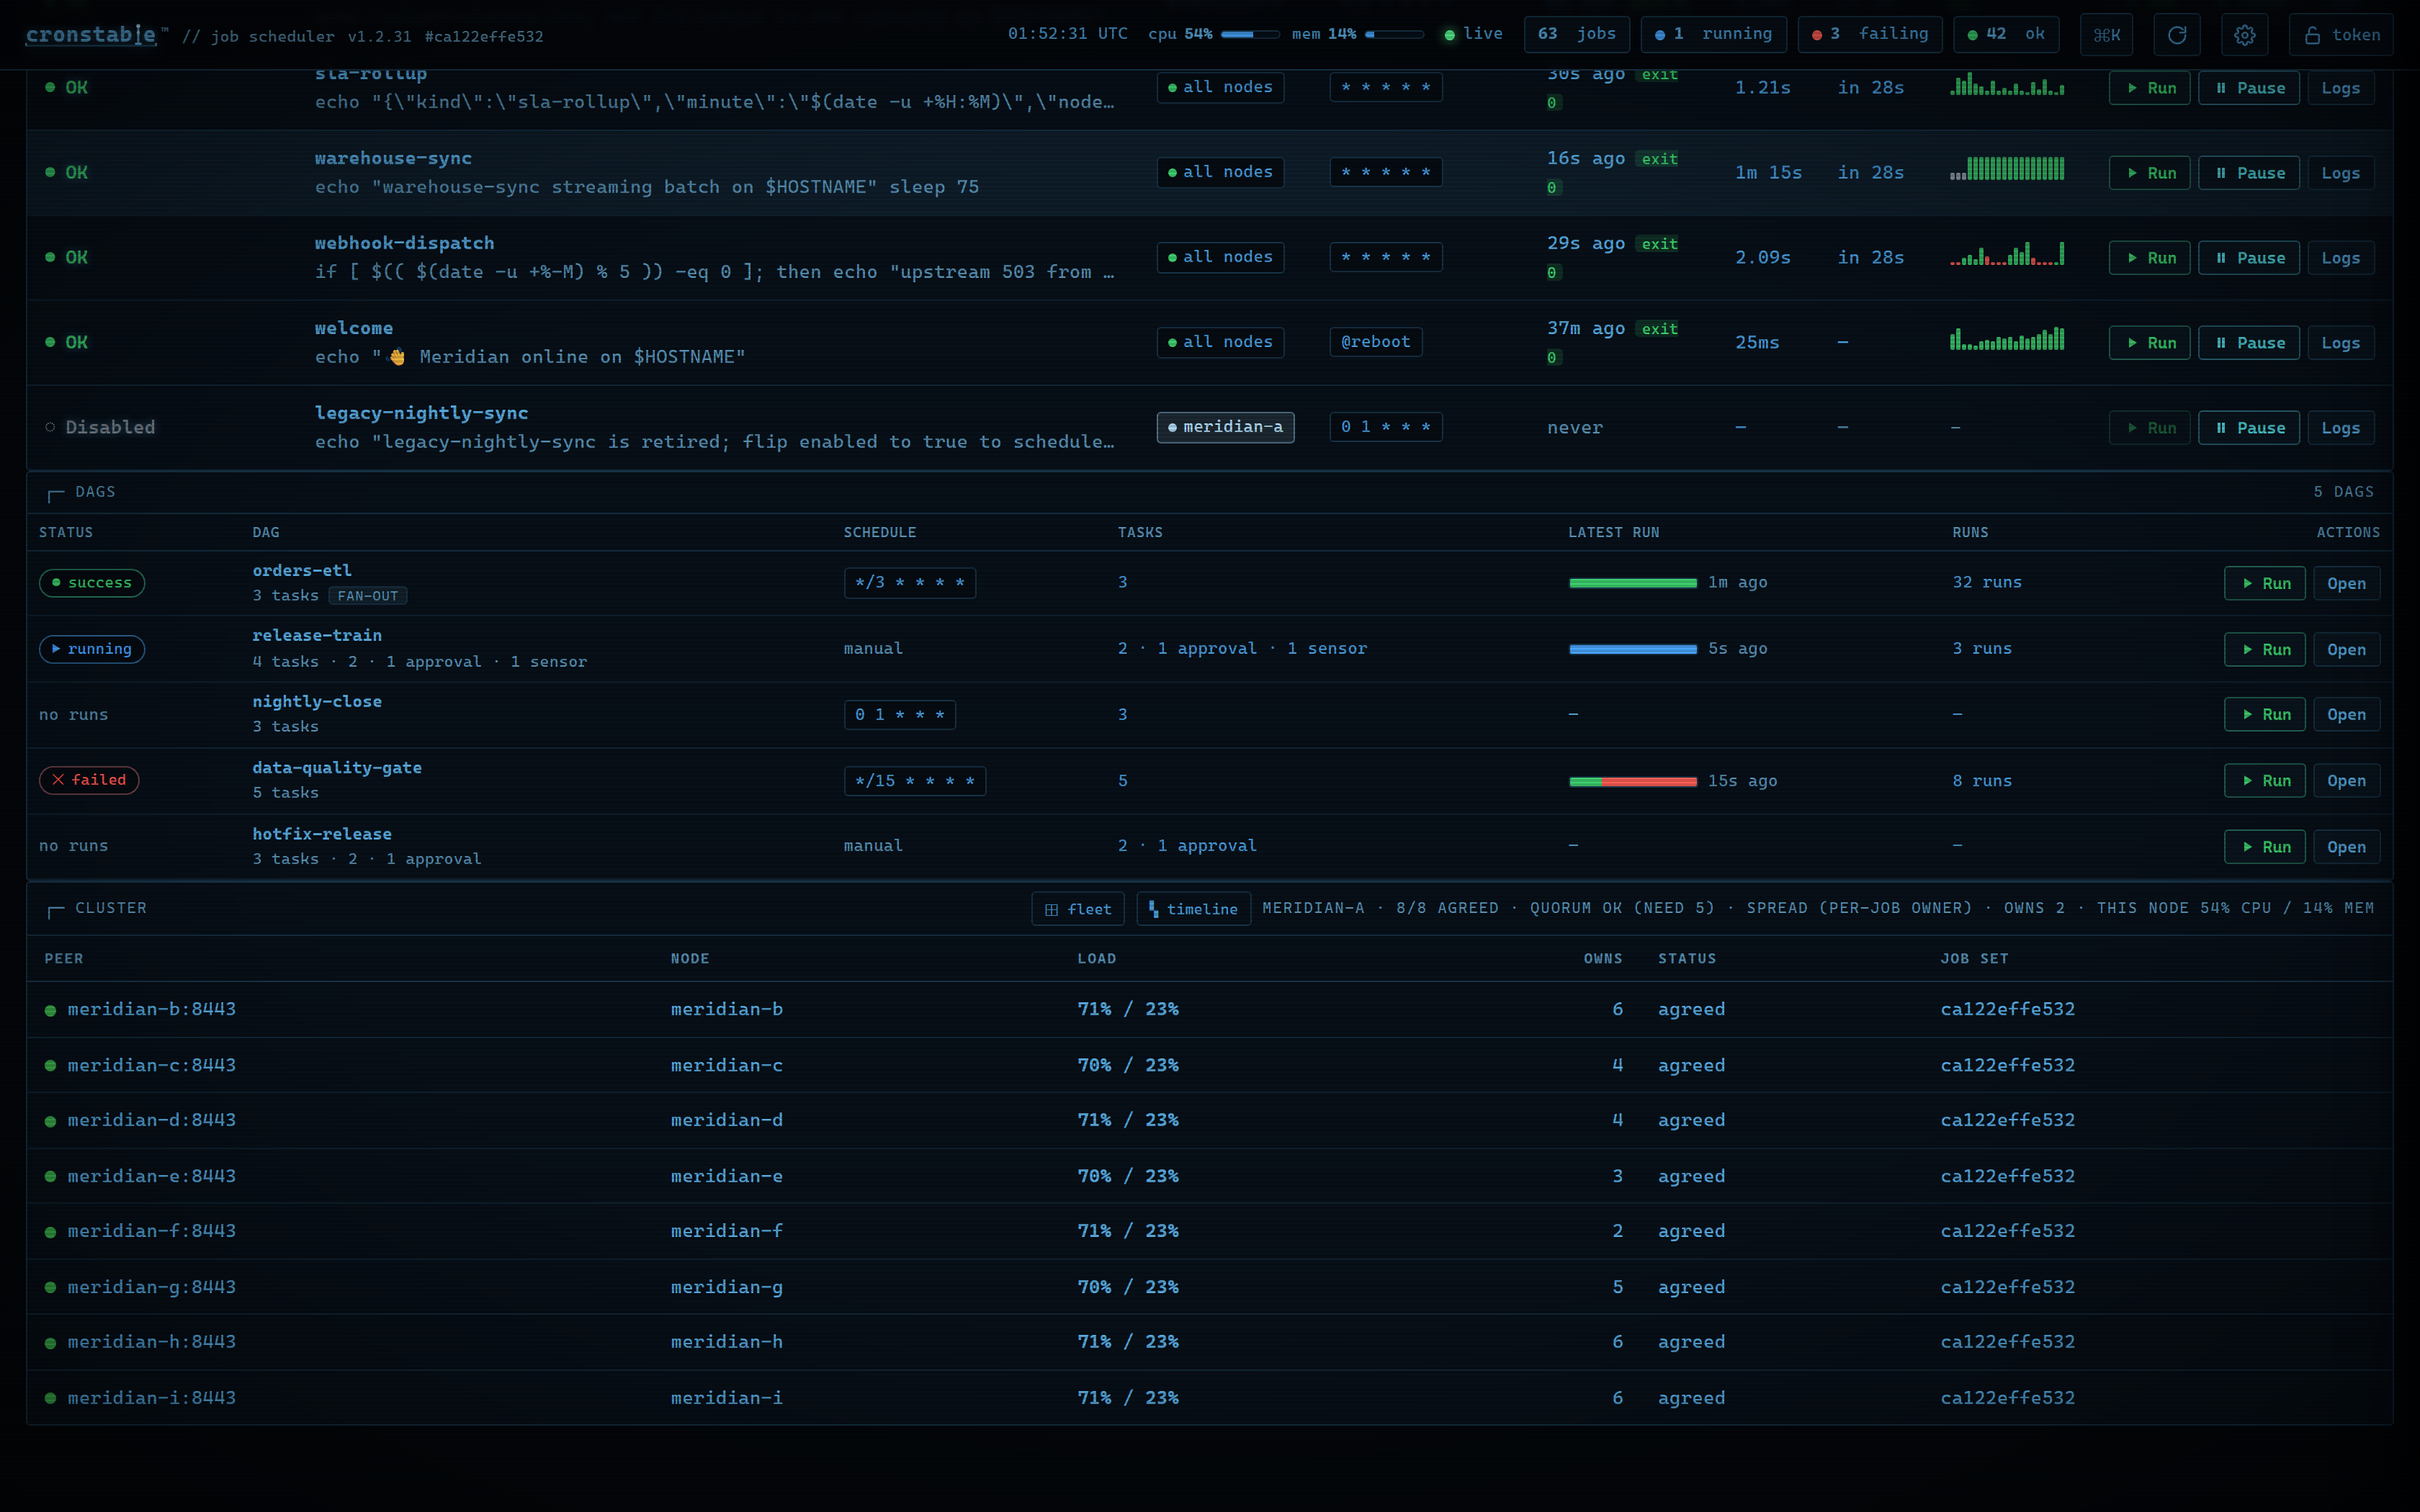
When a cluster
section is configured, the dashboard shows a cluster panel below the job
table (it stays hidden otherwise). The panel polls GET /cluster alongside the
job list and renders:
Try it: the bundled Compose demos bring the dashboard up with one command.
example/cluster/docker-compose.ymlstarts the three-node gossip cluster (cronstable-a/cronstable-b/cronstable-c) so you can watch the peer table, roles, and leadership move live; stop a node to see the summary and dots react. For the ambient wallboard view (including the "zen" all-clear screensaver),example/zen-demo/docker-compose.ymlruns a single deliberately calm node.
- a summary line with this node's name and the agreement tally, such as
cronstable-aandcronstable-a · 2/2 agreed. When leader election is on, it also shows whether quorum holds and how many nodes it needs, and this node's role:- leader, follower (with the current leader's name), or no quorum when the node has stood down.
- under
distribution: spreadthere is no single leader, so the role reads spread (per-job owner) while quorate, or spread (no quorum) otherwise. Under spread the summary also reports how many jobs this node owns (such as… · owns 3). - when the cluster is in conflict the role instead reads standing down
(conflict), because the conflict fails
Leaderjobs closed regardless of who holds the lead. The summary appends a loud⚠ … — Leader jobs pausednote naming the cause, one of three; see clustering and leader election for what each one means and how to clear it:- a duplicate
nodeName: two peers advertising the same name. - a cluster size mismatch: peers declaring different cluster sizes, such as mid-resize.
- a coordination policy mismatch: a peer running a different
distribution/elect_leader.
- a duplicate
- a per-peer table with the on-screen headers Peer | Node | Load
| Owns | Status | Job set. It lists each peer's address, reported node name,
status, and the short form of its job-set ID. The Load column appears
when peers share node stats through
cluster.observability. The Owns column, counting how many jobs each node owns, is present only underdistribution: spread, so the whole job-to-node distribution is visible; it pairs with the per-job Owner column in the job table earlier. Each peer also carries a colored status dot:- green for
agreed. - amber for
syncing. - red for
drifted/untrusted/conflict. - gray for
unreachable. - blue for
self. - faint gray for a peer that is
unknown: configured but not yet contacted, so no status has come back.
- green for
Peers the node has listed as its own address (self) are excluded from the
agreement tally. Use the peer statuses to monitor a rolling deployment
(syncing → agreed), detect drift, or track leadership changes when a
node becomes unavailable.
A ▚ timeline button in the panel header toggles a per-peer swimlane:
one lane per peer, colored by status over time, that accumulates in the browser
while the tab is open. You can read a syncing → agreed convergence or a
flapping peer as a stripe rather than as a single instant. It charts the gossip
peer set only, so it is hidden entirely for the lease backends.
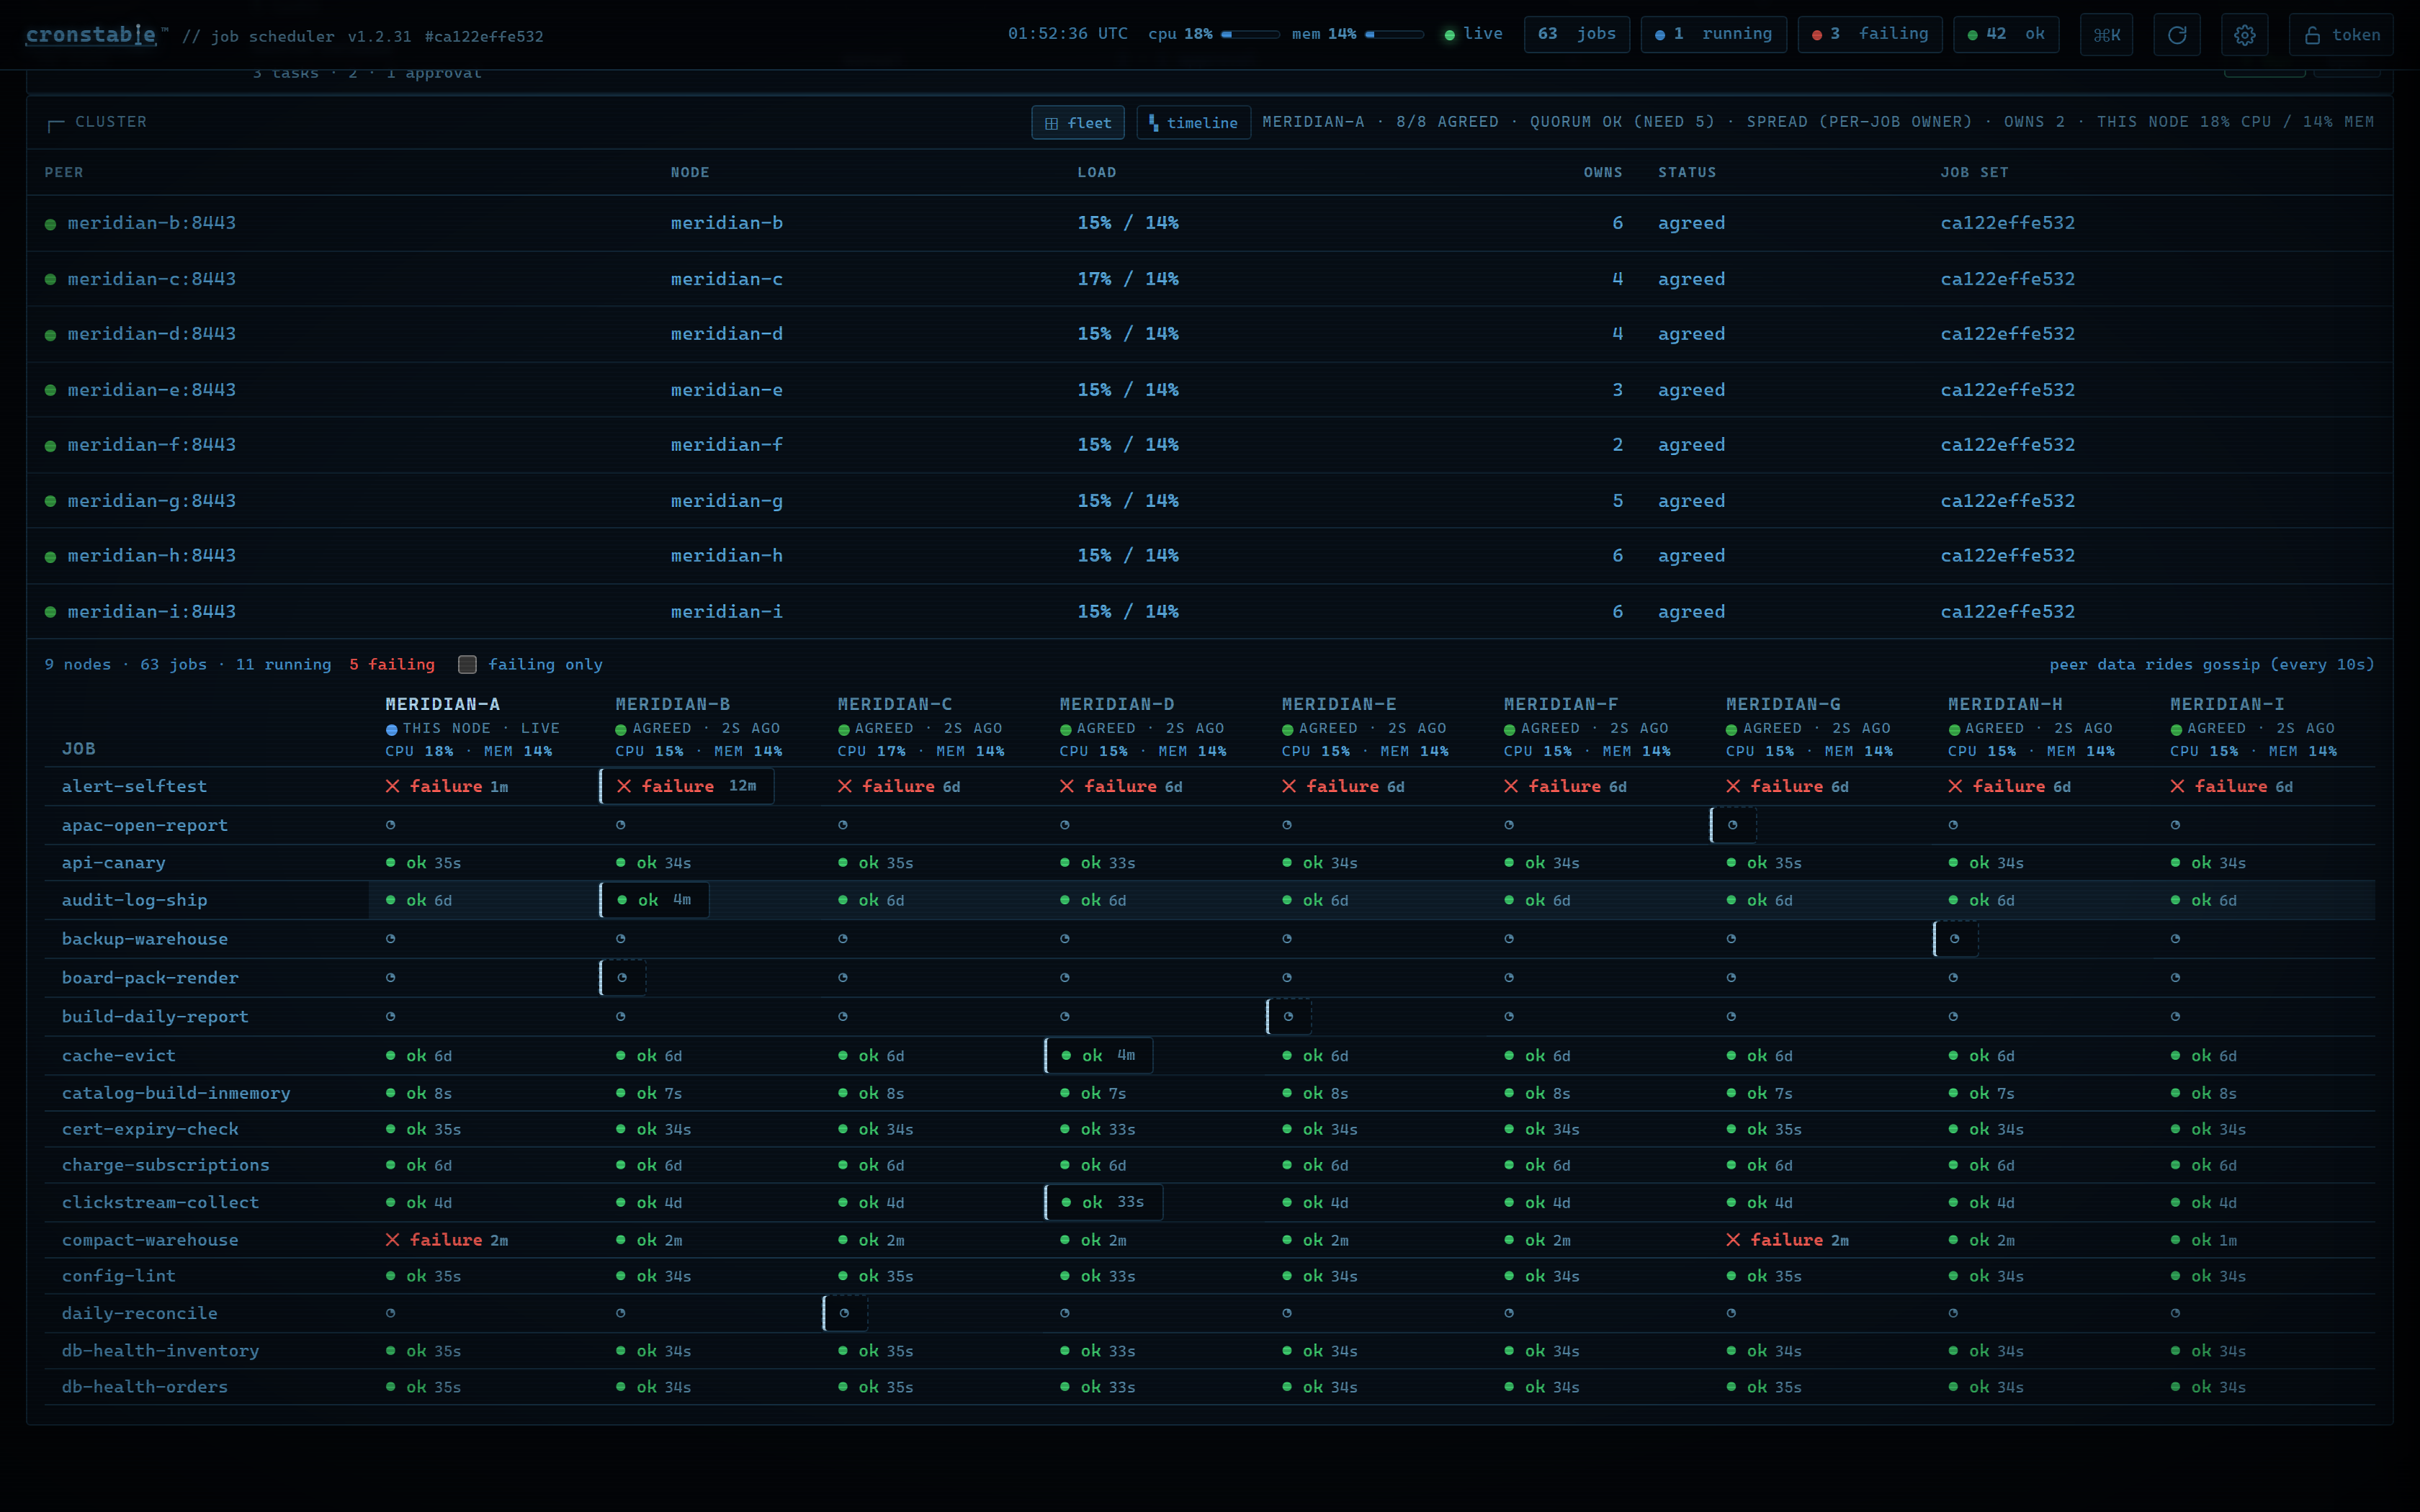
The dashboard normally shows runs from the node you are viewing. Under
distribution: spread
a job's runs on a peer do not appear in that history. Use ⊞ fleet in
the cluster panel header to open a matrix with one row per job and one column
per node. The rows include
every node's advertised jobs, so a mid-deploy peer's new job shows up too. Each
cell carries that node's state for the job: ▶ running, the last outcome with
its age (● ok 3m, ✕ failure 12s), ◌ off for disabled-there, ◔ for never
ran there, — for not configured there, and · when the node has reported no
data at all.
Hovering a cell reveals the exit code, finish time, duration, and next fire; clicking a job name opens its drawer. A failing only filter collapses the matrix to the rows that are red anywhere in the fleet. Under spread, the cell belonging to each job's current owner carries an accent marker, so "who should run this next" and "who ran it last" sit side by side.
Nodes exchange per-job summaries (running, enabled, next fire, and last run)
through their existing mutual-TLS
/peer responses.
The dashboard polls GET /fleet for the merged result,
which any node can serve.
The cost of that design is freshness. A peer column is up to one gossip
interval stale (30 s by default), so every column header shows its node's
status dot and data age (live for the serving node, 41s ago for a peer). A
briefly unreachable peer keeps its last-known cells with a growing age instead
of going blank, and a node whose job set exceeds the gossip payload cap (512
jobs) is flagged partial. Summaries are observability data only: they never
influence election or run decisions. On a lease backend the view needs
cluster.observability;
without it the button is hidden.
Separately from the in-panel summary, a cluster incident also raises the
page-level CLUSTER ALERT bar at the top of the dashboard. This red incident
banner appears whenever this node reports a cluster conflict (duplicate
nodeName, size mismatch, or coordination policy mismatch) or has lost
quorum, so the alert is visible without scrolling down to the panel. It names
the cause and, under a lease backend, phrases quorum loss as the lease store
being unreachable.
The preceding bullets describe the gossip backend. The
lease backends
(kubernetes / etcd) have no peer set, so the panel renders a different shape:
a role summary (node-name · backend · role, where the role is leader,
follower (leader: …), follower, or no quorum (store unreachable))
followed by a key/value lease-detail table, with no status dots, no
agreement tally, and no quorum count.
The table renders every non-null key the backend reports, so beyond the
lease/election name, the holder, the identity, and the expiry it also surfaces
the kubernetes namespace or the etcd leaseId when present. There, no quorum means the lease store is unreachable from this node, not "no
majority". For the full GET /cluster field semantics, see
clustering and leader election.
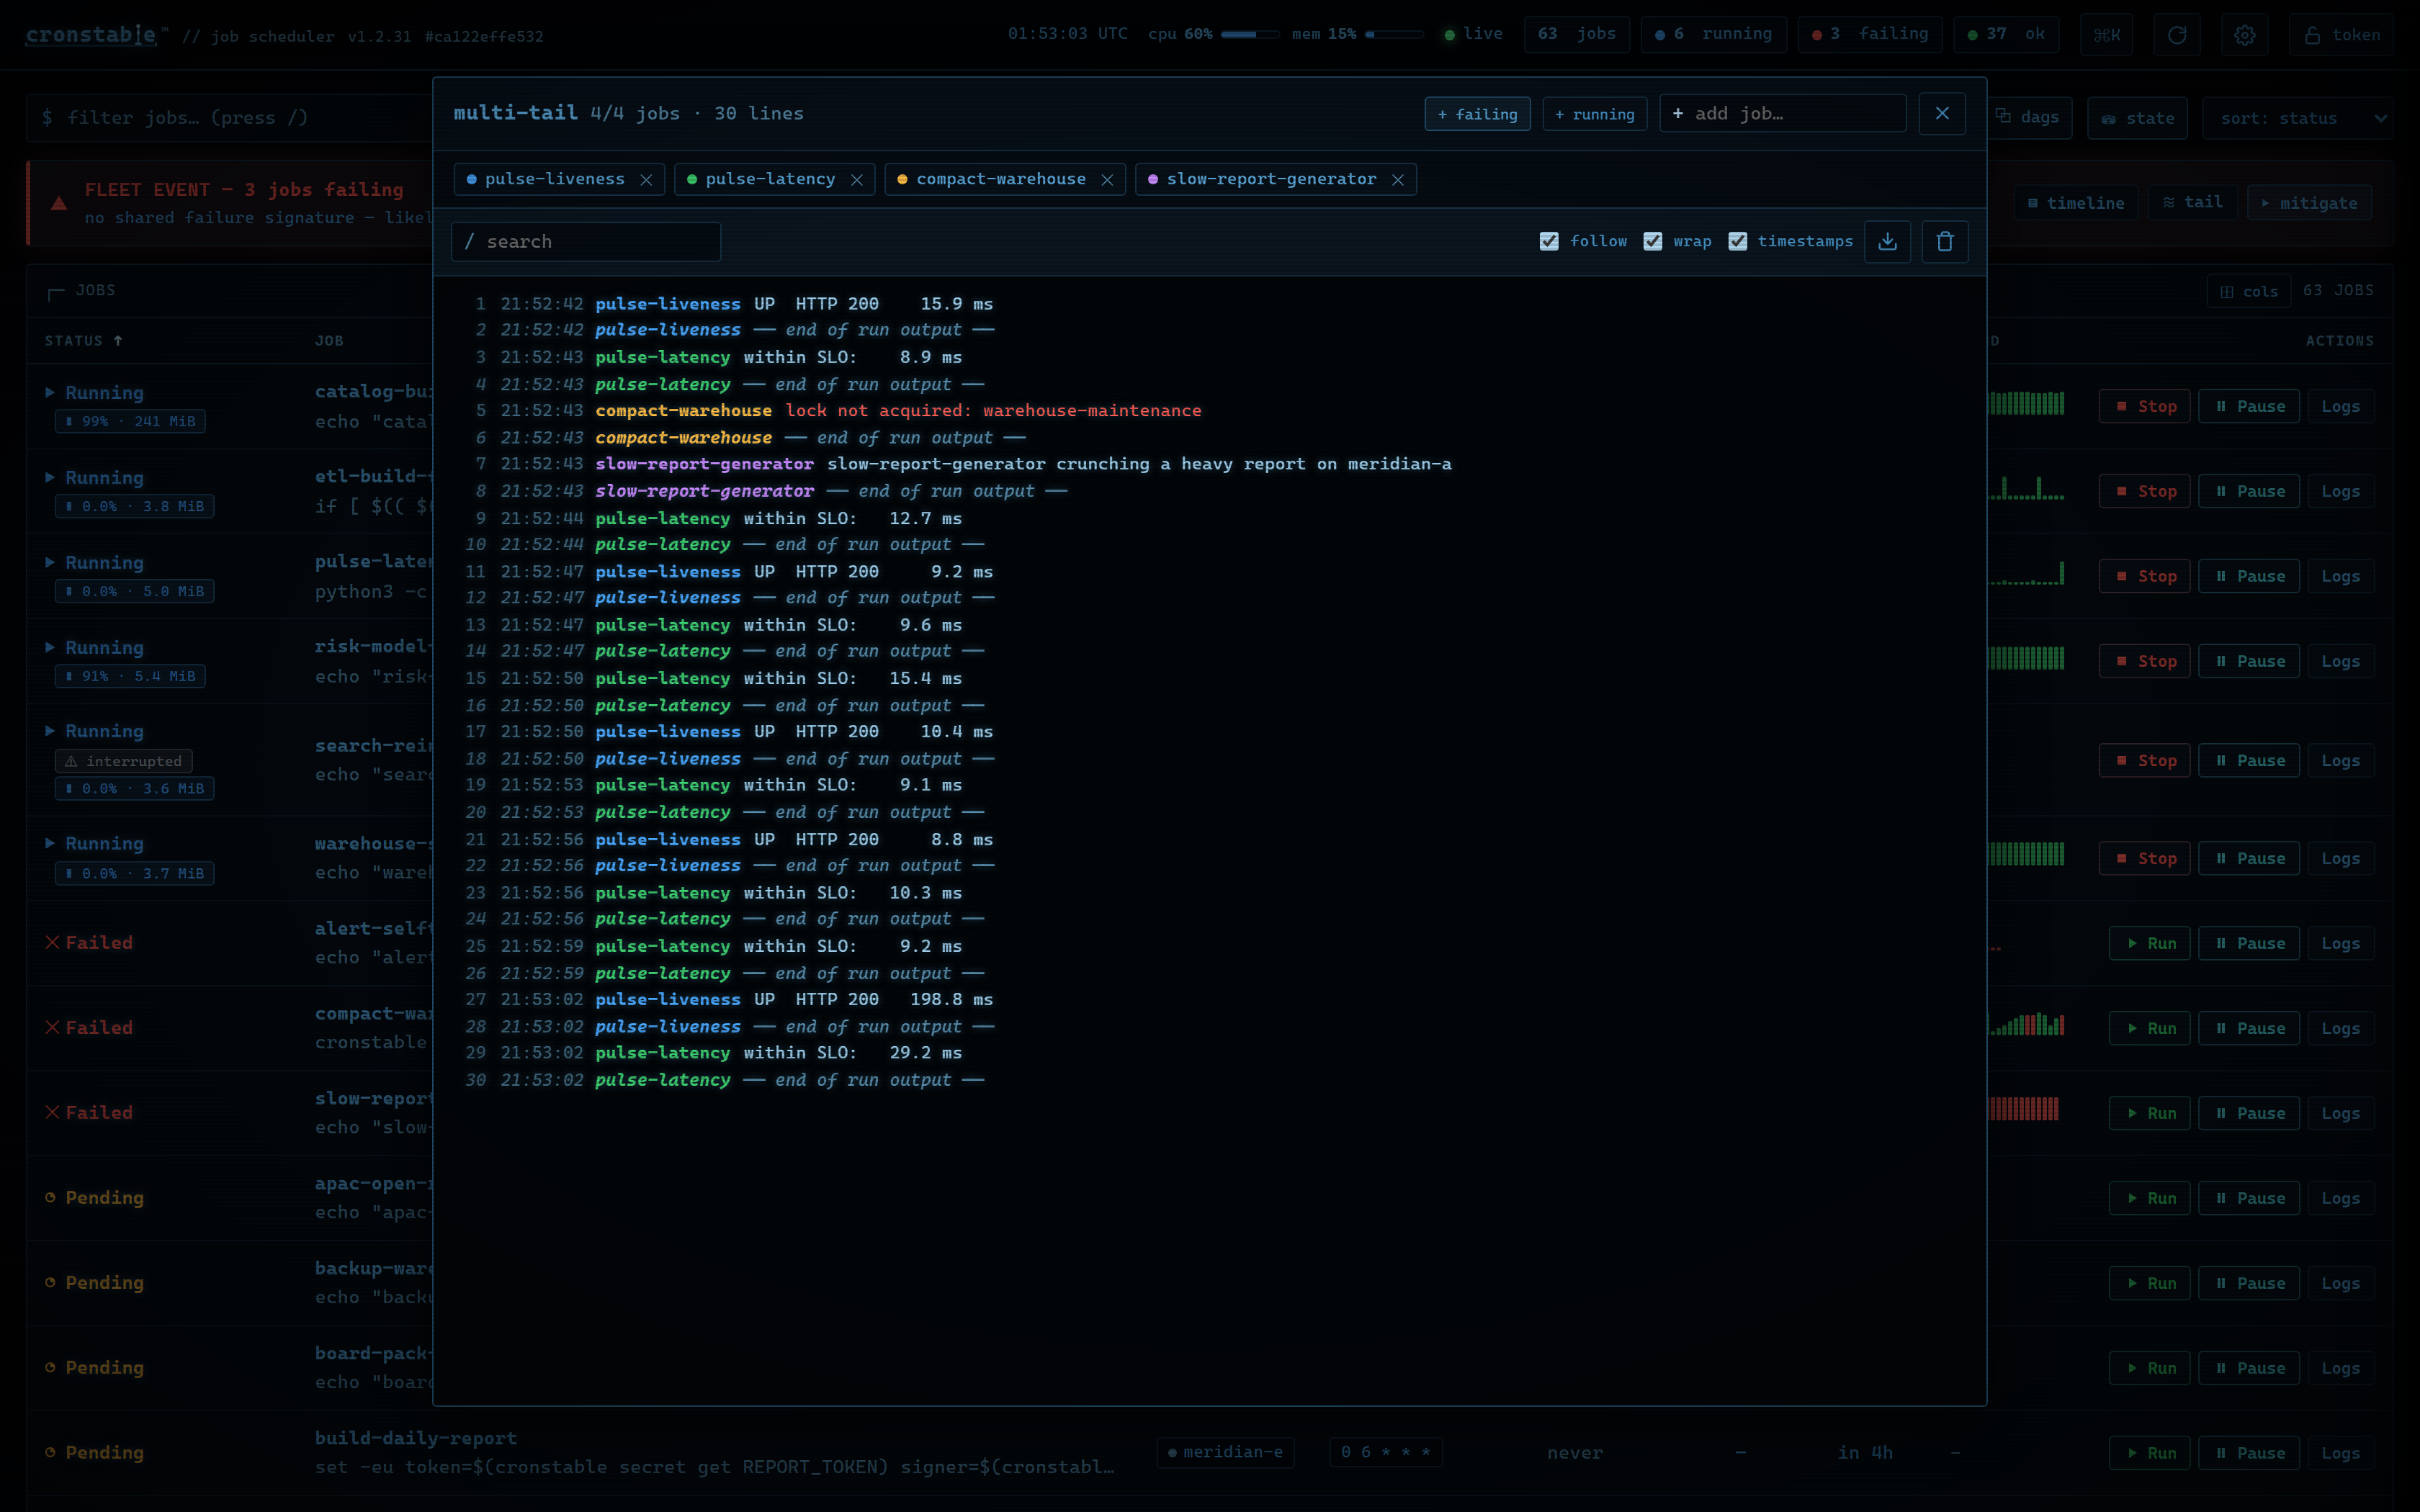
The ≋ live logs toolbar button opens the live logs panel: several jobs'
log streams merged into one live pane, each line prefixed with its job name in
a stable identity color, like tailing a set of pods. It is built for correlated
incidents. The incident verdict bar and the job actions panel each carry a
≋ live logs button that opens it pre-loaded with the failing set, and the command
palette offers a per-job Tail: … action plus failing / running
presets.
- Add jobs with the + failing / + running presets or the add box (which autocompletes to the configured jobs); remove one from its chip. Clicking a chip or a line's job prefix jumps to that job's drawer.
- The console holds at most 4 concurrent streams. Browsers allow only ~6 HTTP/1.1 connections per origin and every tailed job keeps one open, so the cap leaves room for the dashboard's own polling.
- The daemon closes a job's log stream when the tailed run's output ends, so
the console re-attaches automatically for the job's next run, paced by the
refresh interval. Attaching replays the run's buffered output from the start,
so a re-attach that lands mid-run still shows the whole run. Runs are
delimited with an
── end of run output ──marker. - The view offers follow, wrap, and timestamps toggles (shared
with the drawer's Logs tab), a plain-text search with a live match
count, one-click download of the merged view (lines prefixed
[job]), and a clear button. - As with the drawer's Logs tab, output
appears only for the streams a job captures
(
captureStdout/captureStderr).
None of these need a cluster; they all work on a single node.
When something is failing, a verdict bar appears at the top of the page and
distills the situation into one line. A single failure reads
JOB FAILING — <name> · exit <code> · <reason>. When several jobs are failing,
the dashboard groups matching exit codes and failure reasons. It reports
MULTIPLE FAILURES — N jobs failing and highlights jobs that may share a
cause, or says that no matching failure details were found. A cluster quorum, leadership, or conflict problem escalates
the bar to the red CLUSTER ALERT severity described earlier under
cluster panel. The bar carries ▤ timeline, ▸ review actions, and
≋ live logs buttons scoped to the incident set.
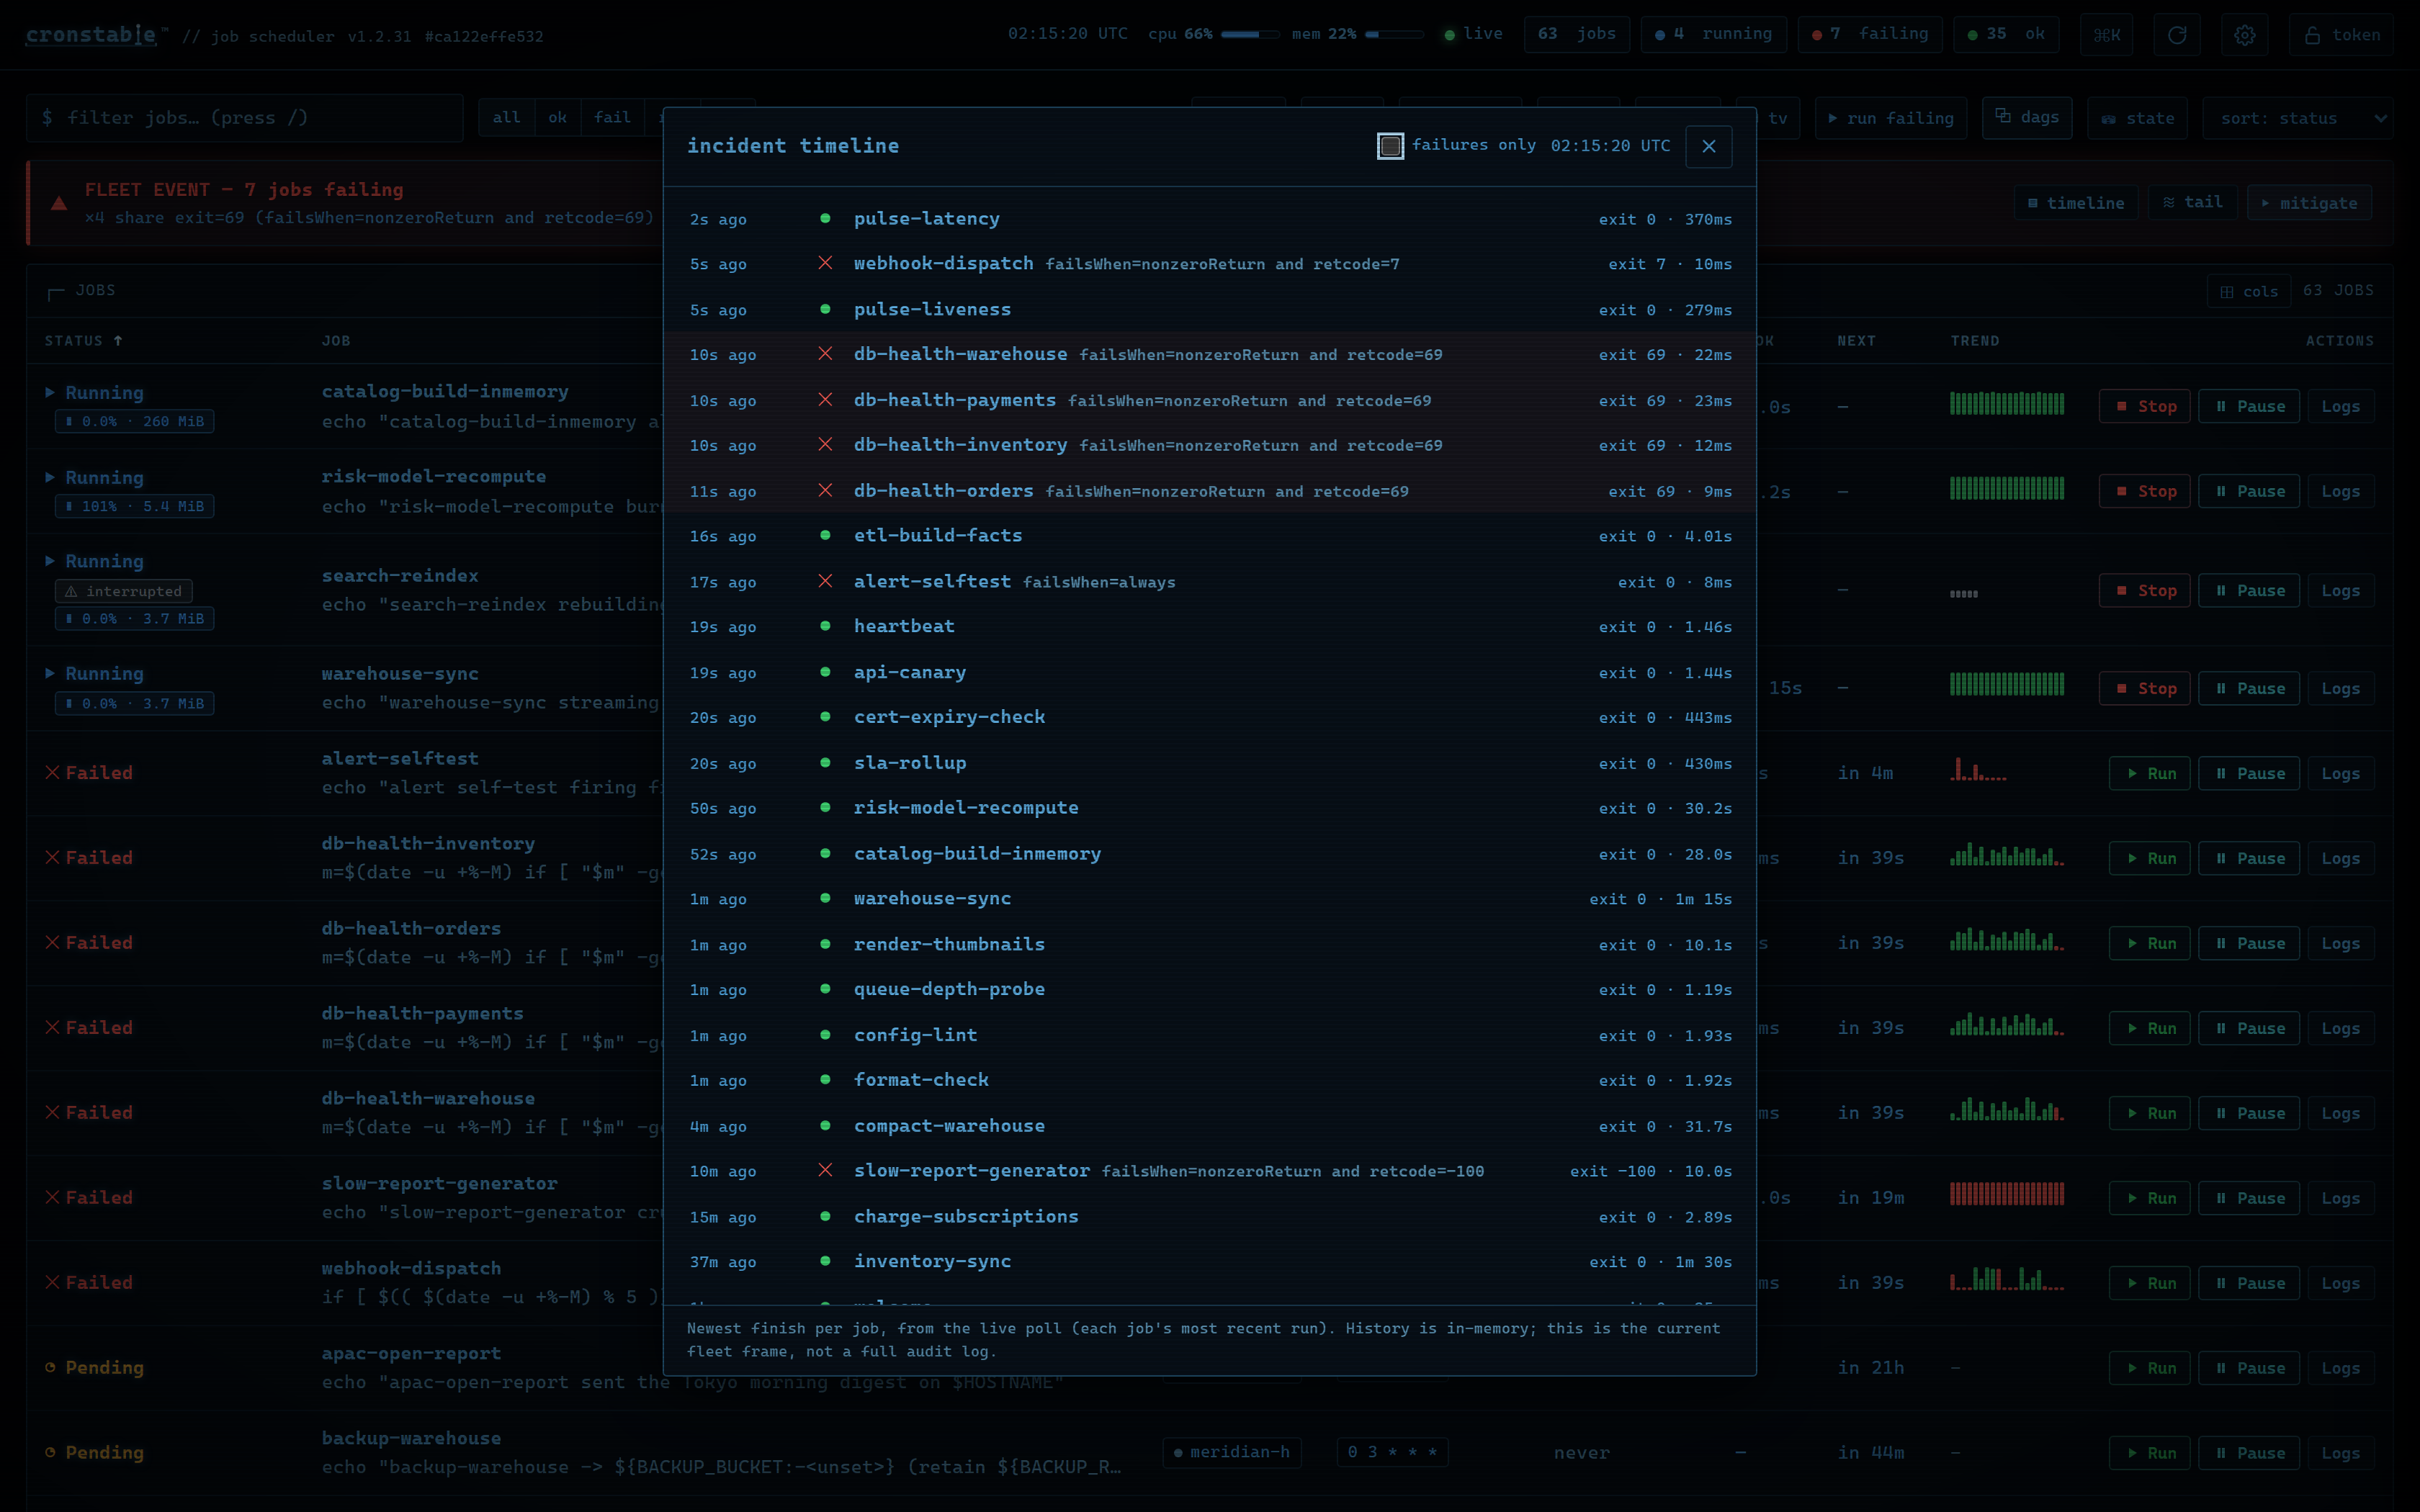
The incident timeline (press i, or Incident timeline in the command
palette) lists each job's most recent finished run, newest first, with its
relative time, outcome, failure reason, exit code, and duration. Use
failures only to filter the list. Jobs grouped by the verdict bar are
highlighted.
The job actions panel (Review actions for failing jobs in the palette, or the
verdict bar's ▸ review actions button) acts on the failing set in bulk. Guarded
start all now / cancel all actions send the per-job
start/cancel endpoints staggered a few hundred
milliseconds apart (gentle on the daemon), with a live per-job ✓/✕ result log
and a final tally; you can stop the sequence while it runs. The panel can also
open live logs for the selected jobs, and copy a ready-made
Markdown incident summary (timestamp, host, version, cluster state, and a
per-job table) for your incident channel or ticket.
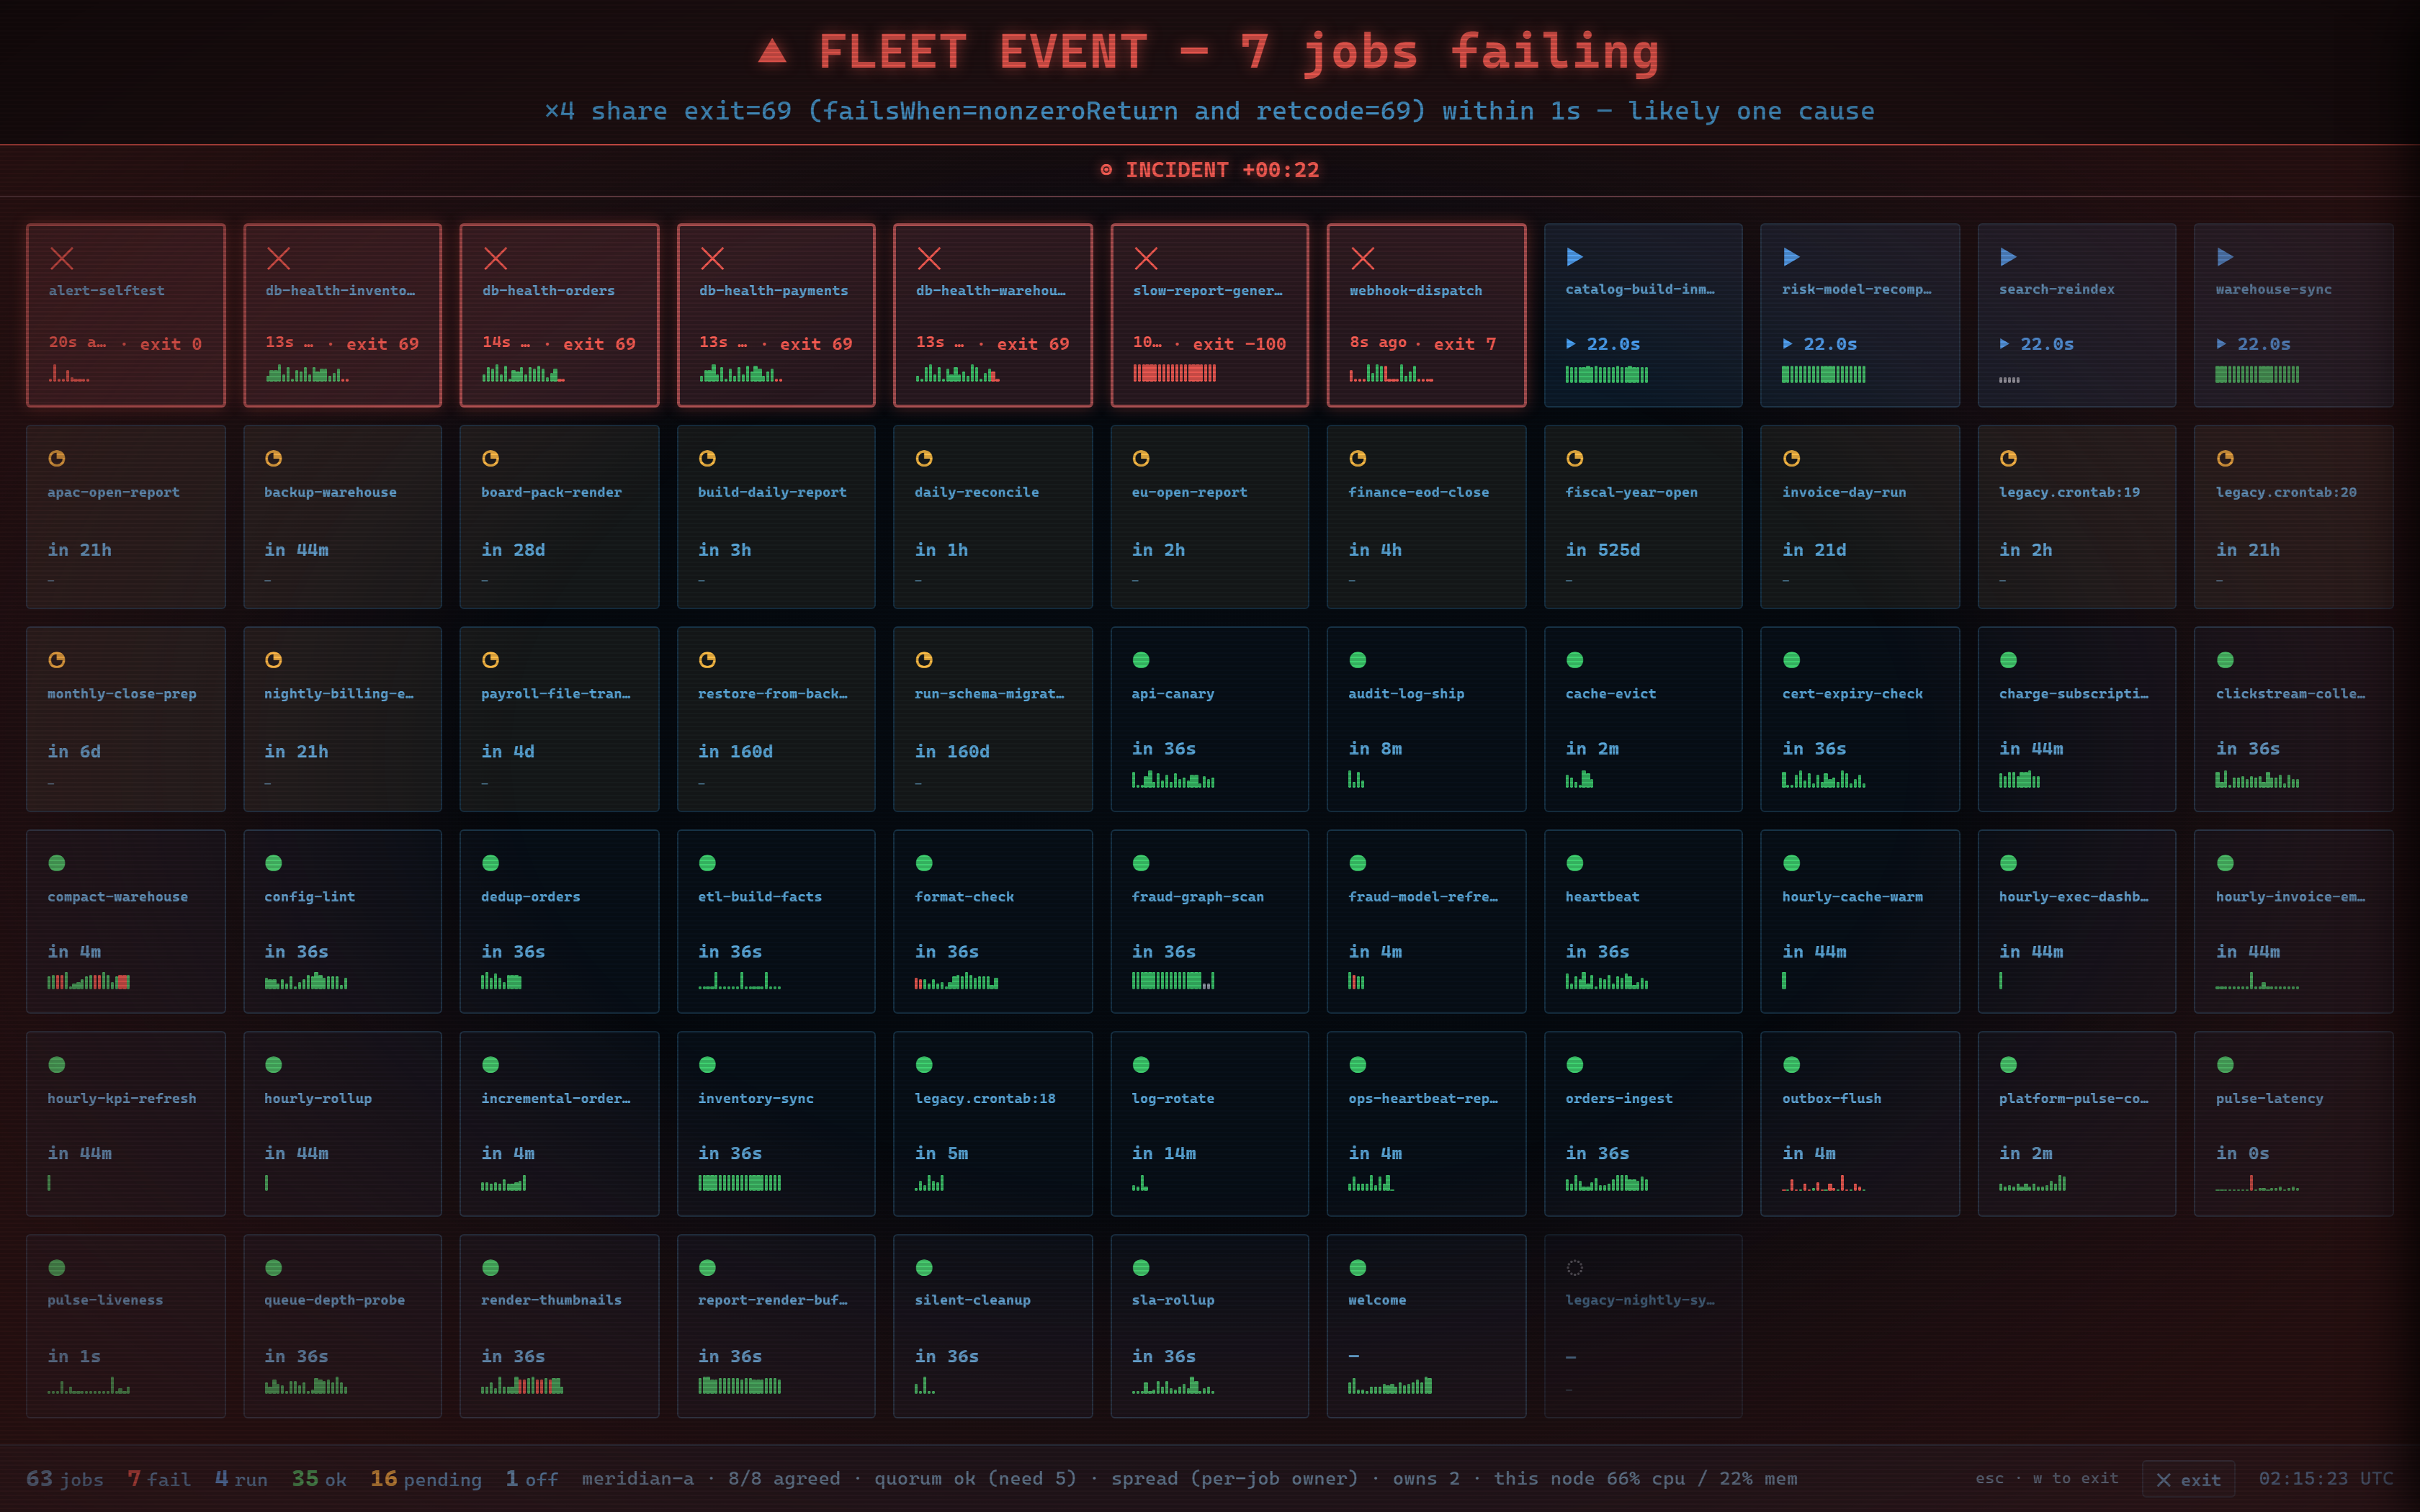
Press w (or Wallboard / TV mode in the palette, or open the page with a
#tv hash) for a full-screen kiosk view built for a wall monitor: every job as
a large tile, sorted worst-first (failing, then running, then the rest), plus a
footer tally and a live UTC clock. Each tile leads with the fact a wall viewer
glances for. A failing tile shows when it failed and its exit code (counting
up live), a running tile shows elapsed time (turning amber after it runs
well past its longest recent duration), and a healthy tile shows its next-fire
countdown, with the status hue filling the whole tile, not only the glyph.
When anything is failing, a full-width verdict headline distills scope and
likely cause at TV scale (single job + exit code, correlated fleet event, or
cluster alert), the same correlation verdict the dashboard's bar shows. Clicking
a tile exits to that job's drawer; Esc or w exits.
The grid also fits itself to the screen: a handful of jobs on a big screen get
proportionally larger tiles and type, and a crowded fleet scales full tiles down
(names, glance lines and sparklines all kept) before stepping down to compact
tiles, which keep the sparkline too whenever their rows have room for it. If
even that overflows, the healthiest tail is cut behind an explicit footer chip
(+22 offscreen · none failing), computed from what was cut, so the board never
silently clips a failure behind a scrollbar nobody can reach.
If no poll succeeds for about 15 seconds (or three refresh intervals), the
wallboard dims and shows ▚ NO SIGNAL / ▚ STALE DATA.
When everything is healthy and the wallboard has been idle for a while (30
seconds by default; configurable in Settings), the zen screensaver drifts
in: an ALL SYSTEMS NOMINAL field where every enabled job is a small dot that
pulses as its real next-fire instant arrives, with a subtitle counting the jobs
armed and naming the next one due. Any input wakes it. On stale data it does not
show the all-green field: an unverified all-clear is NO SIGNAL, not nominal.
It also respects prefers-reduced-motion. The
example/zen-demo/docker-compose.yml demo boots a single calm node to
demonstrate it.
The ⌁ upcoming toolbar button (or Toggle upcoming runs in the palette)
opens an upcoming runs panel answering "what runs next", fleet-wide: a feed of
each job's next run, with the soonest eight listed, each with a live countdown (hover one for the
wall-clock time and the schedule's plain-English reading), above a
ten-minute track on which every fire due inside the window drifts toward
now as a mark. Clicking an entry or a mark opens that job's drawer, and the
panel header counts everything upcoming. The browser computes fire times with
the same cron engine as the
Schedule tab and the
schedule preview. Disabled jobs, and schedules the engine cannot
preview (such as @reboot), are omitted.
The ◫ week toolbar button (or Toggle week calendar in the palette)
opens a seven-day grid starting today. Each chip represents a scheduled run,
colored by job and displayed in your browser's local time. A dashed line
marks the current time. Chips sharing a quarter-hour split the column;
past times today appear dimmed. Clicking a chip opens the job's
Schedule tab.
Jobs scheduled more than about eight times a day appear in a background
hum summary below the grid. Subscribe in a calendar app using the fleet's
iCal feed (⤓ calendar feed) in the card header or the per-job feed in its
Schedule tab. See calendar export.
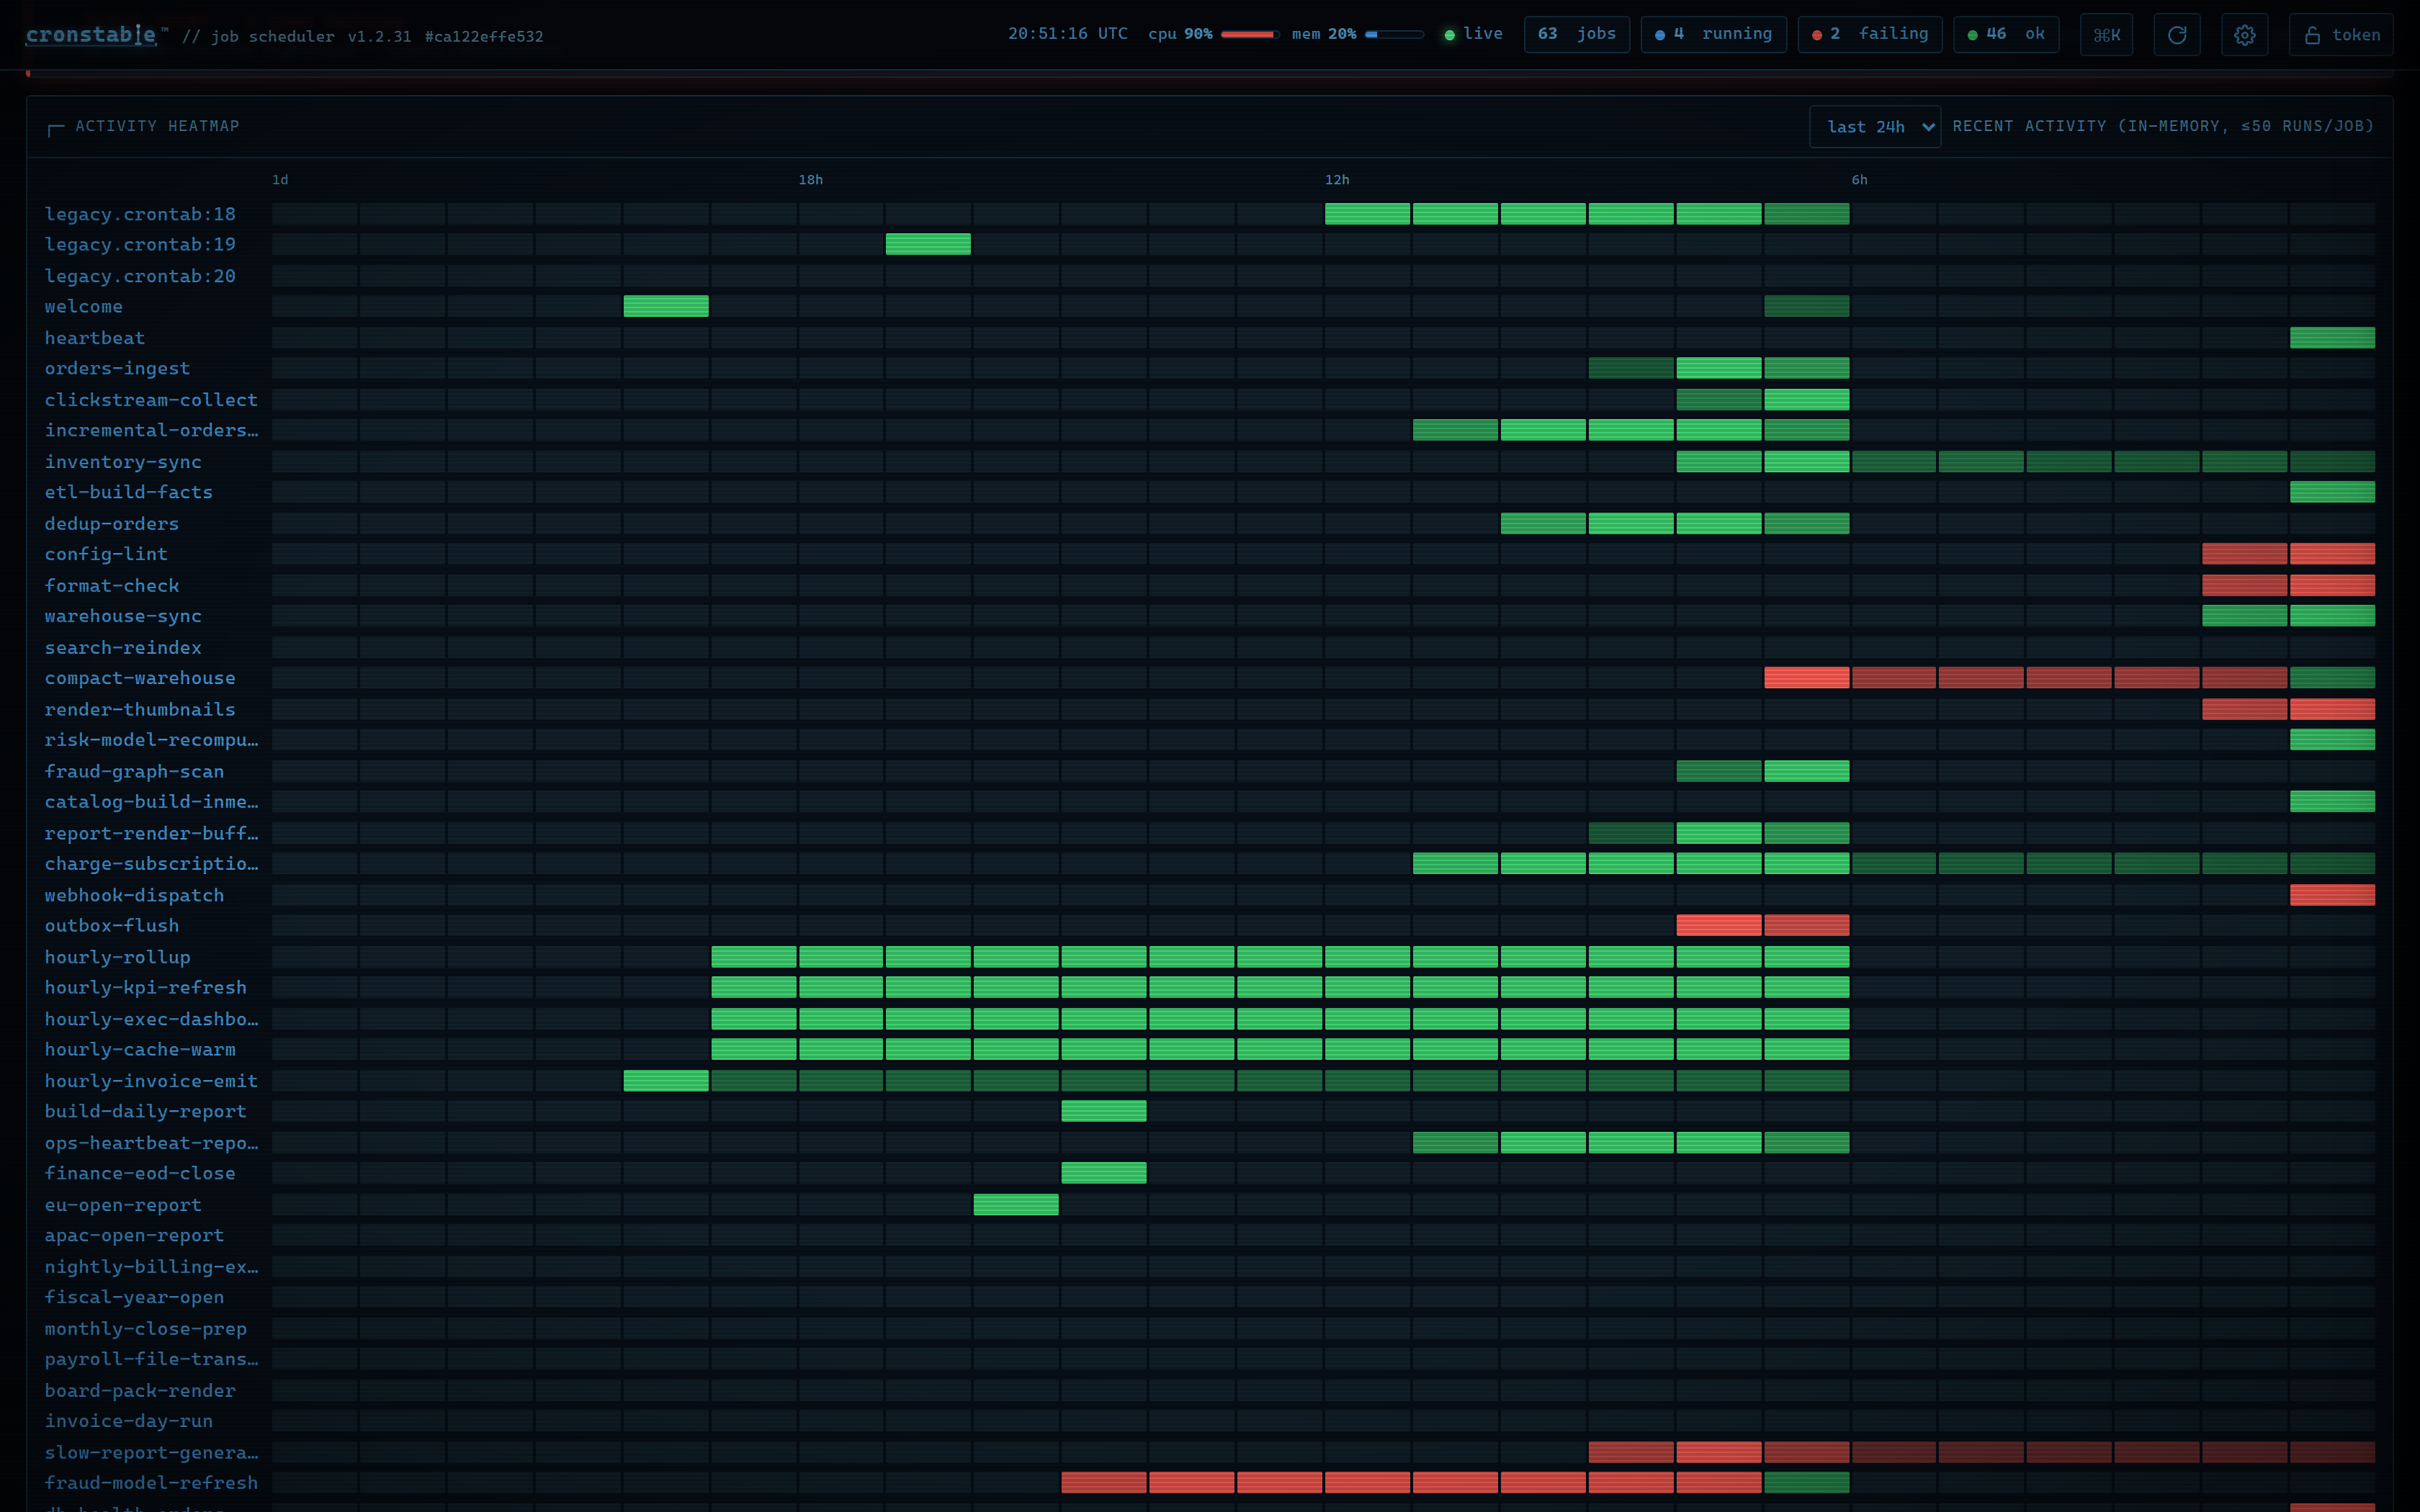
The ▦ activity toolbar button (or Toggle activity heatmap in the palette)
adds a grid: one row per job (the first 80), 24 time buckets across a 6h / 24h /
7d window, each cell colored by the worst outcome in that bucket and shaded
by run volume. Hover a cell for the bucket's tally (such as 3 ok / 1 fail);
click a cell or a job name to open that job. The dashboard fills the card with
one batched GET /activity?jobs=80 fetch, which asks
for the 80 jobs the card draws, and falls back to per-job
run history fetches against an older daemon.
Both read the daemon's in-memory history, which bounds the card's horizon.
The ▥ schedule load toolbar button (or Toggle schedule load in the
palette) shows upcoming scheduled runs over the next 24
hours, fetched from /schedule/pressure
using the server’s scheduling engine. The card shows
the hour-by-minute collision grid (hot cells highlighted), the minute-of-hour
histogram, the fleet's
duplicate-schedule groups as clickable job
chips, and suggest-a-slot buttons whose answer arrives as a
copy-to-clipboard chip alongside the H * * * * hint.
A selector switches the display zone between UTC and the browser's local zone, and the data refreshes about once a minute. With the panel enabled, the wallboard shows a compact pressure strip above the tile grid, so the room sees when many jobs are scheduled at once. See schedule load.
Schedule preview in the palette opens a scratchpad for schedule expressions: type
any 5-, 6-, or 7-field cron expression (including second-level
schedules) or @macro, pick a timezone, and it validates the expression,
describes it in plain English, breaks out the fields, and previews the
next 12 scheduled runs with wall-clock and relative labels (impossible
schedules and @reboot are called out). It cross-references your live jobs to
show which ones use the same schedule, and keeps a browser-local list of recent
expressions. The same engine powers the dashboard's schedule advisories
(overlapping runs, jobs scheduled together, and daylight saving time changes).
The daemon keeps at most the last 50 runs per job in memory. The opt-in browser run
history (a Settings toggle, or Toggle browser run history in the palette) extends
that horizon in your browser: while a tab is open it saves each job’s latest
completed run at every refresh, computes robust per-job duration baselines
(median plus deviation over successful runs), and flags runs that are
unusually slow with a ◱ slow chip on the job row. Settings shows the storage
used, with export (JSON) and clear history buttons. This history stays in the browser and only grows while a tab is open.
Runs that finish between refreshes may be missed.
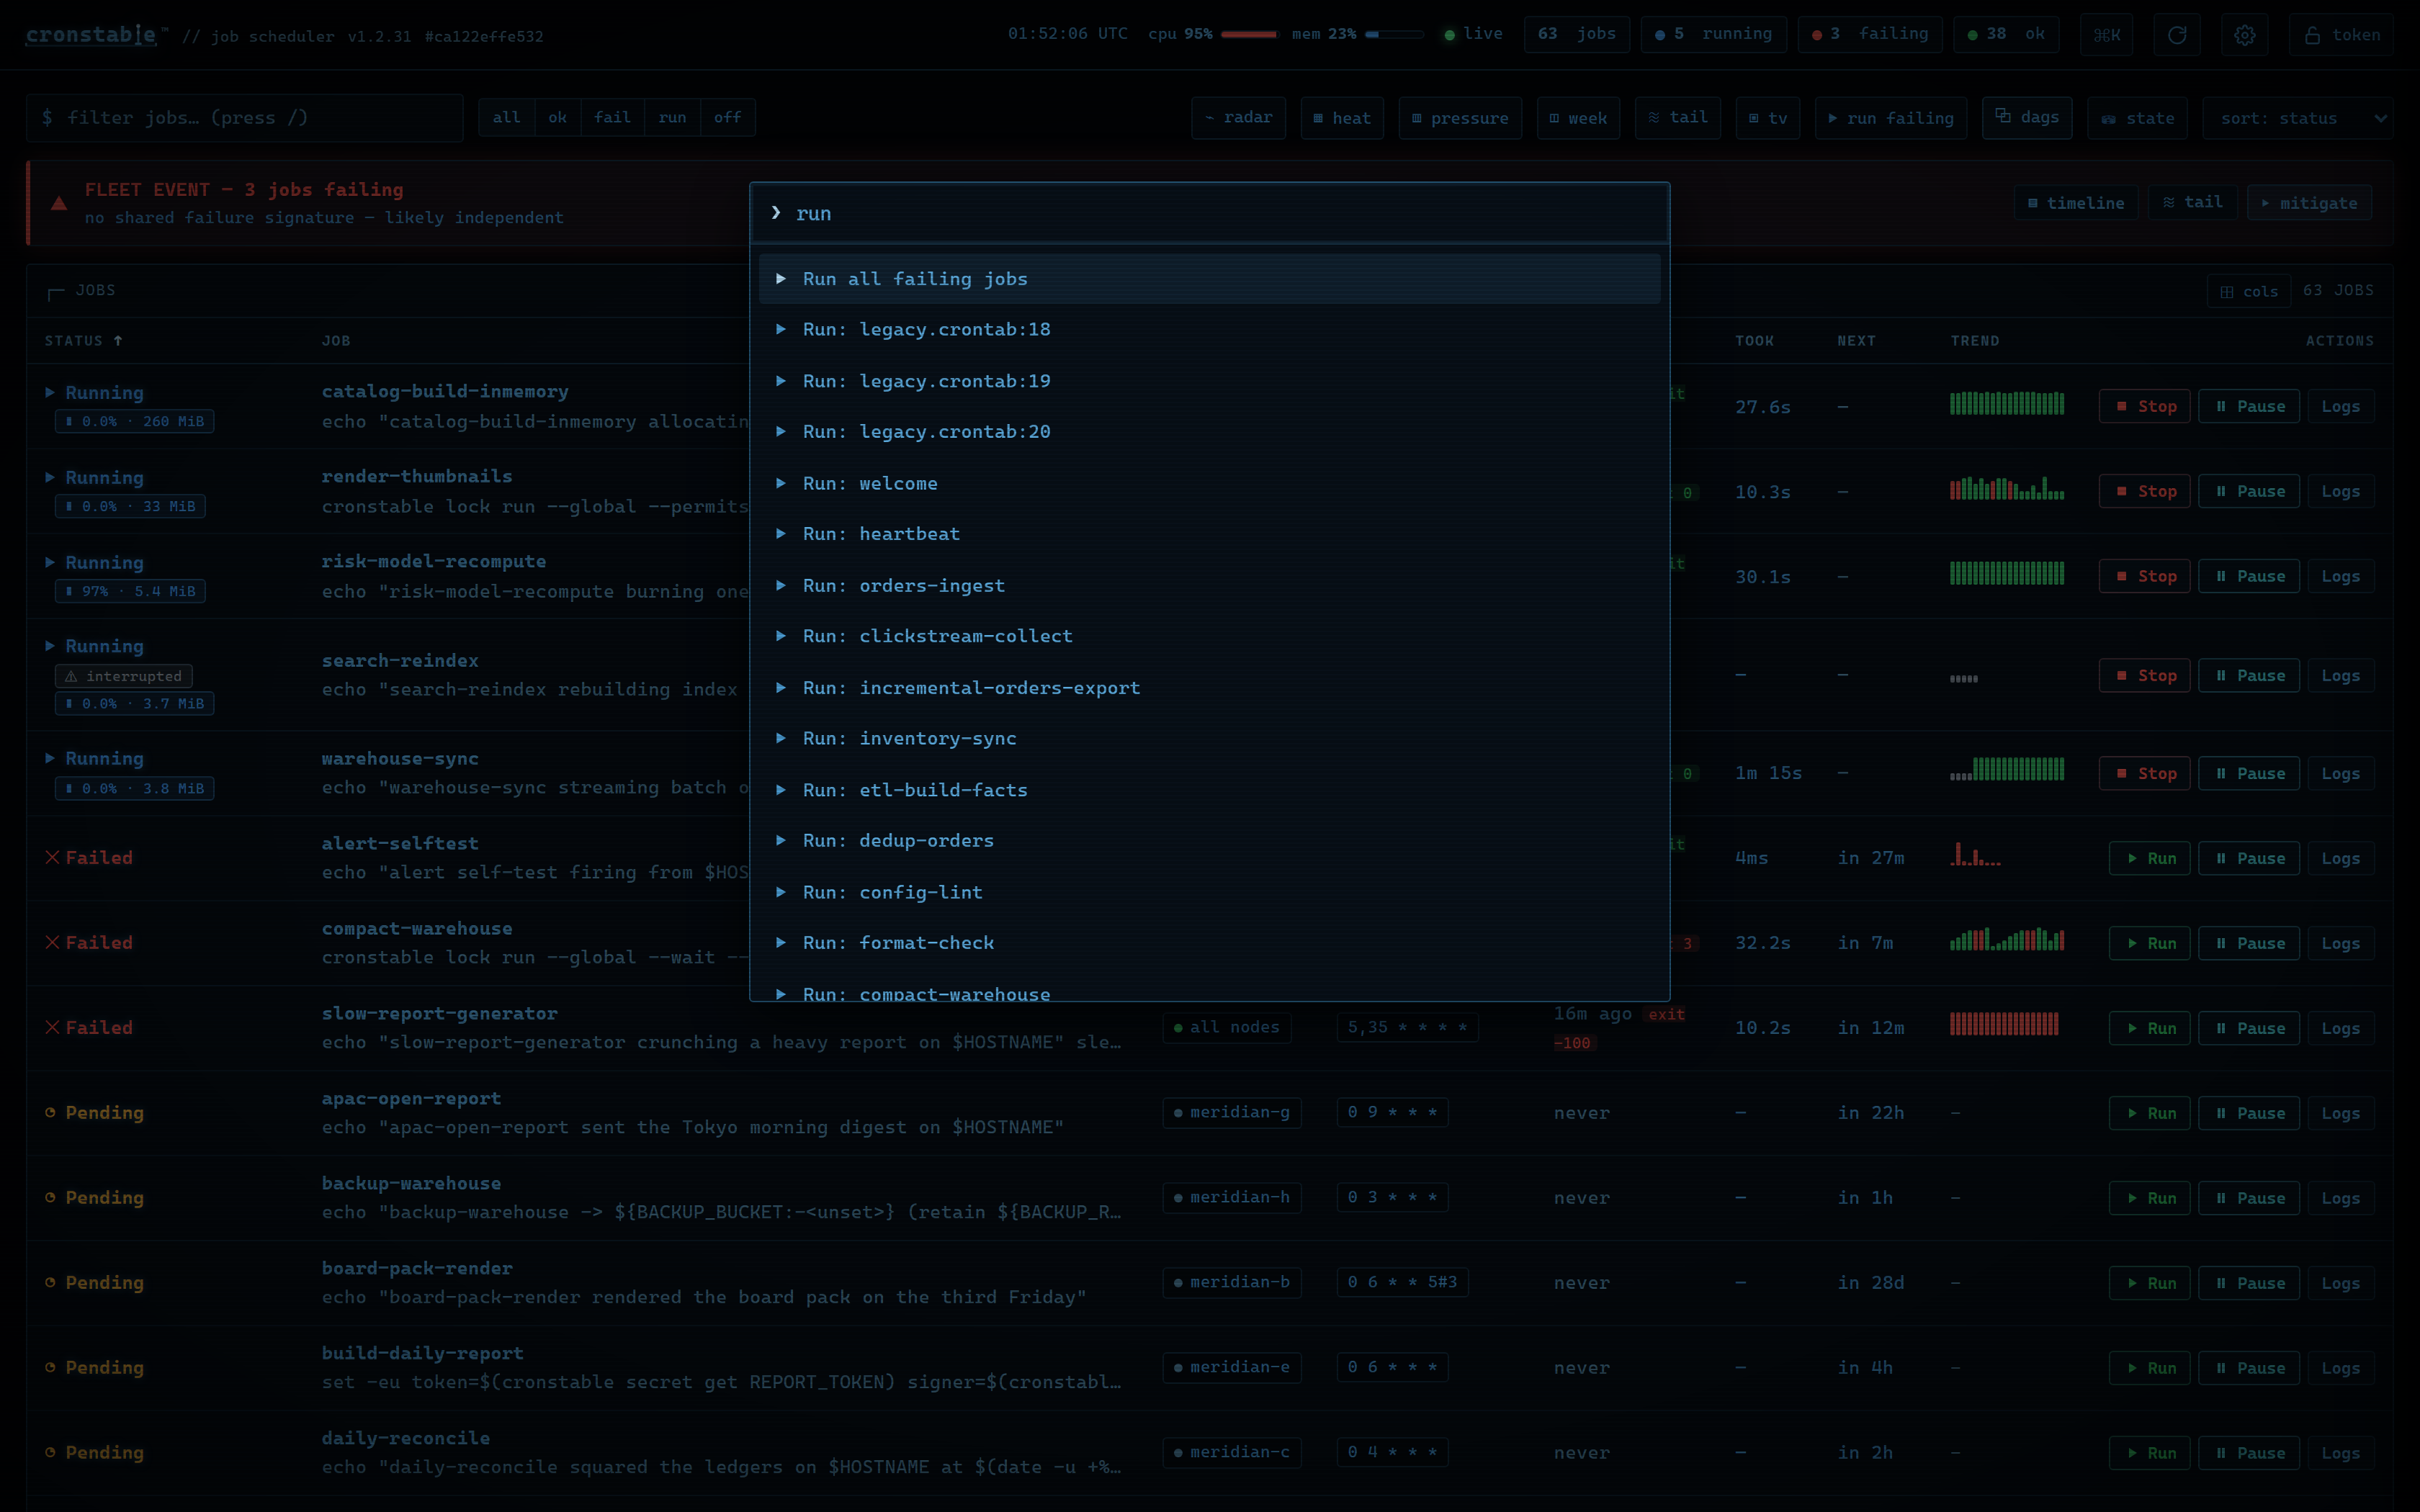
Press Ctrl-K (or ⌘K, or Ctrl-P) to open a fuzzy command palette. It
searches both global actions (refresh, run all failing jobs, cycle theme, toggle
reduce motion, open settings, set the access token…) and a per-job action for every job
(open its logs, run it, cancel it, copy its command, view its schedule). Type to
filter, arrow keys to move, Enter to run.
Copy badge Markdown (per job) and Copy fleet badge Markdown copy
Markdown that embeds a status badge and links it back to
this dashboard, ready to paste into a README or a wiki page. The palette
lists them while the daemon serves badges, and it follows a configuration
reload within about a minute (see scope-aware chrome).
It leaves out the per-job command for a job whose badge no URL reaches, such
as one named .. (see embed a badge).
The palette opens on top of a job drawer, a DAG drawer, the
live logs panel, or the wallboard, and
Esc closes the palette first. Seven panels cover the palette, so the
shortcut does nothing while one of them is open: the settings panel, the
shortcut list, the Pair a device panel, the
token prompt, the incident timeline, the job actions
panel, and the schedule preview. Press Esc to close the panel, and then
open the palette.
The palette closes when another panel or drawer opens: a 401 that opens
the token prompt closes it, and so does a #job/<name> or #dag/<name>
link that opens a drawer.
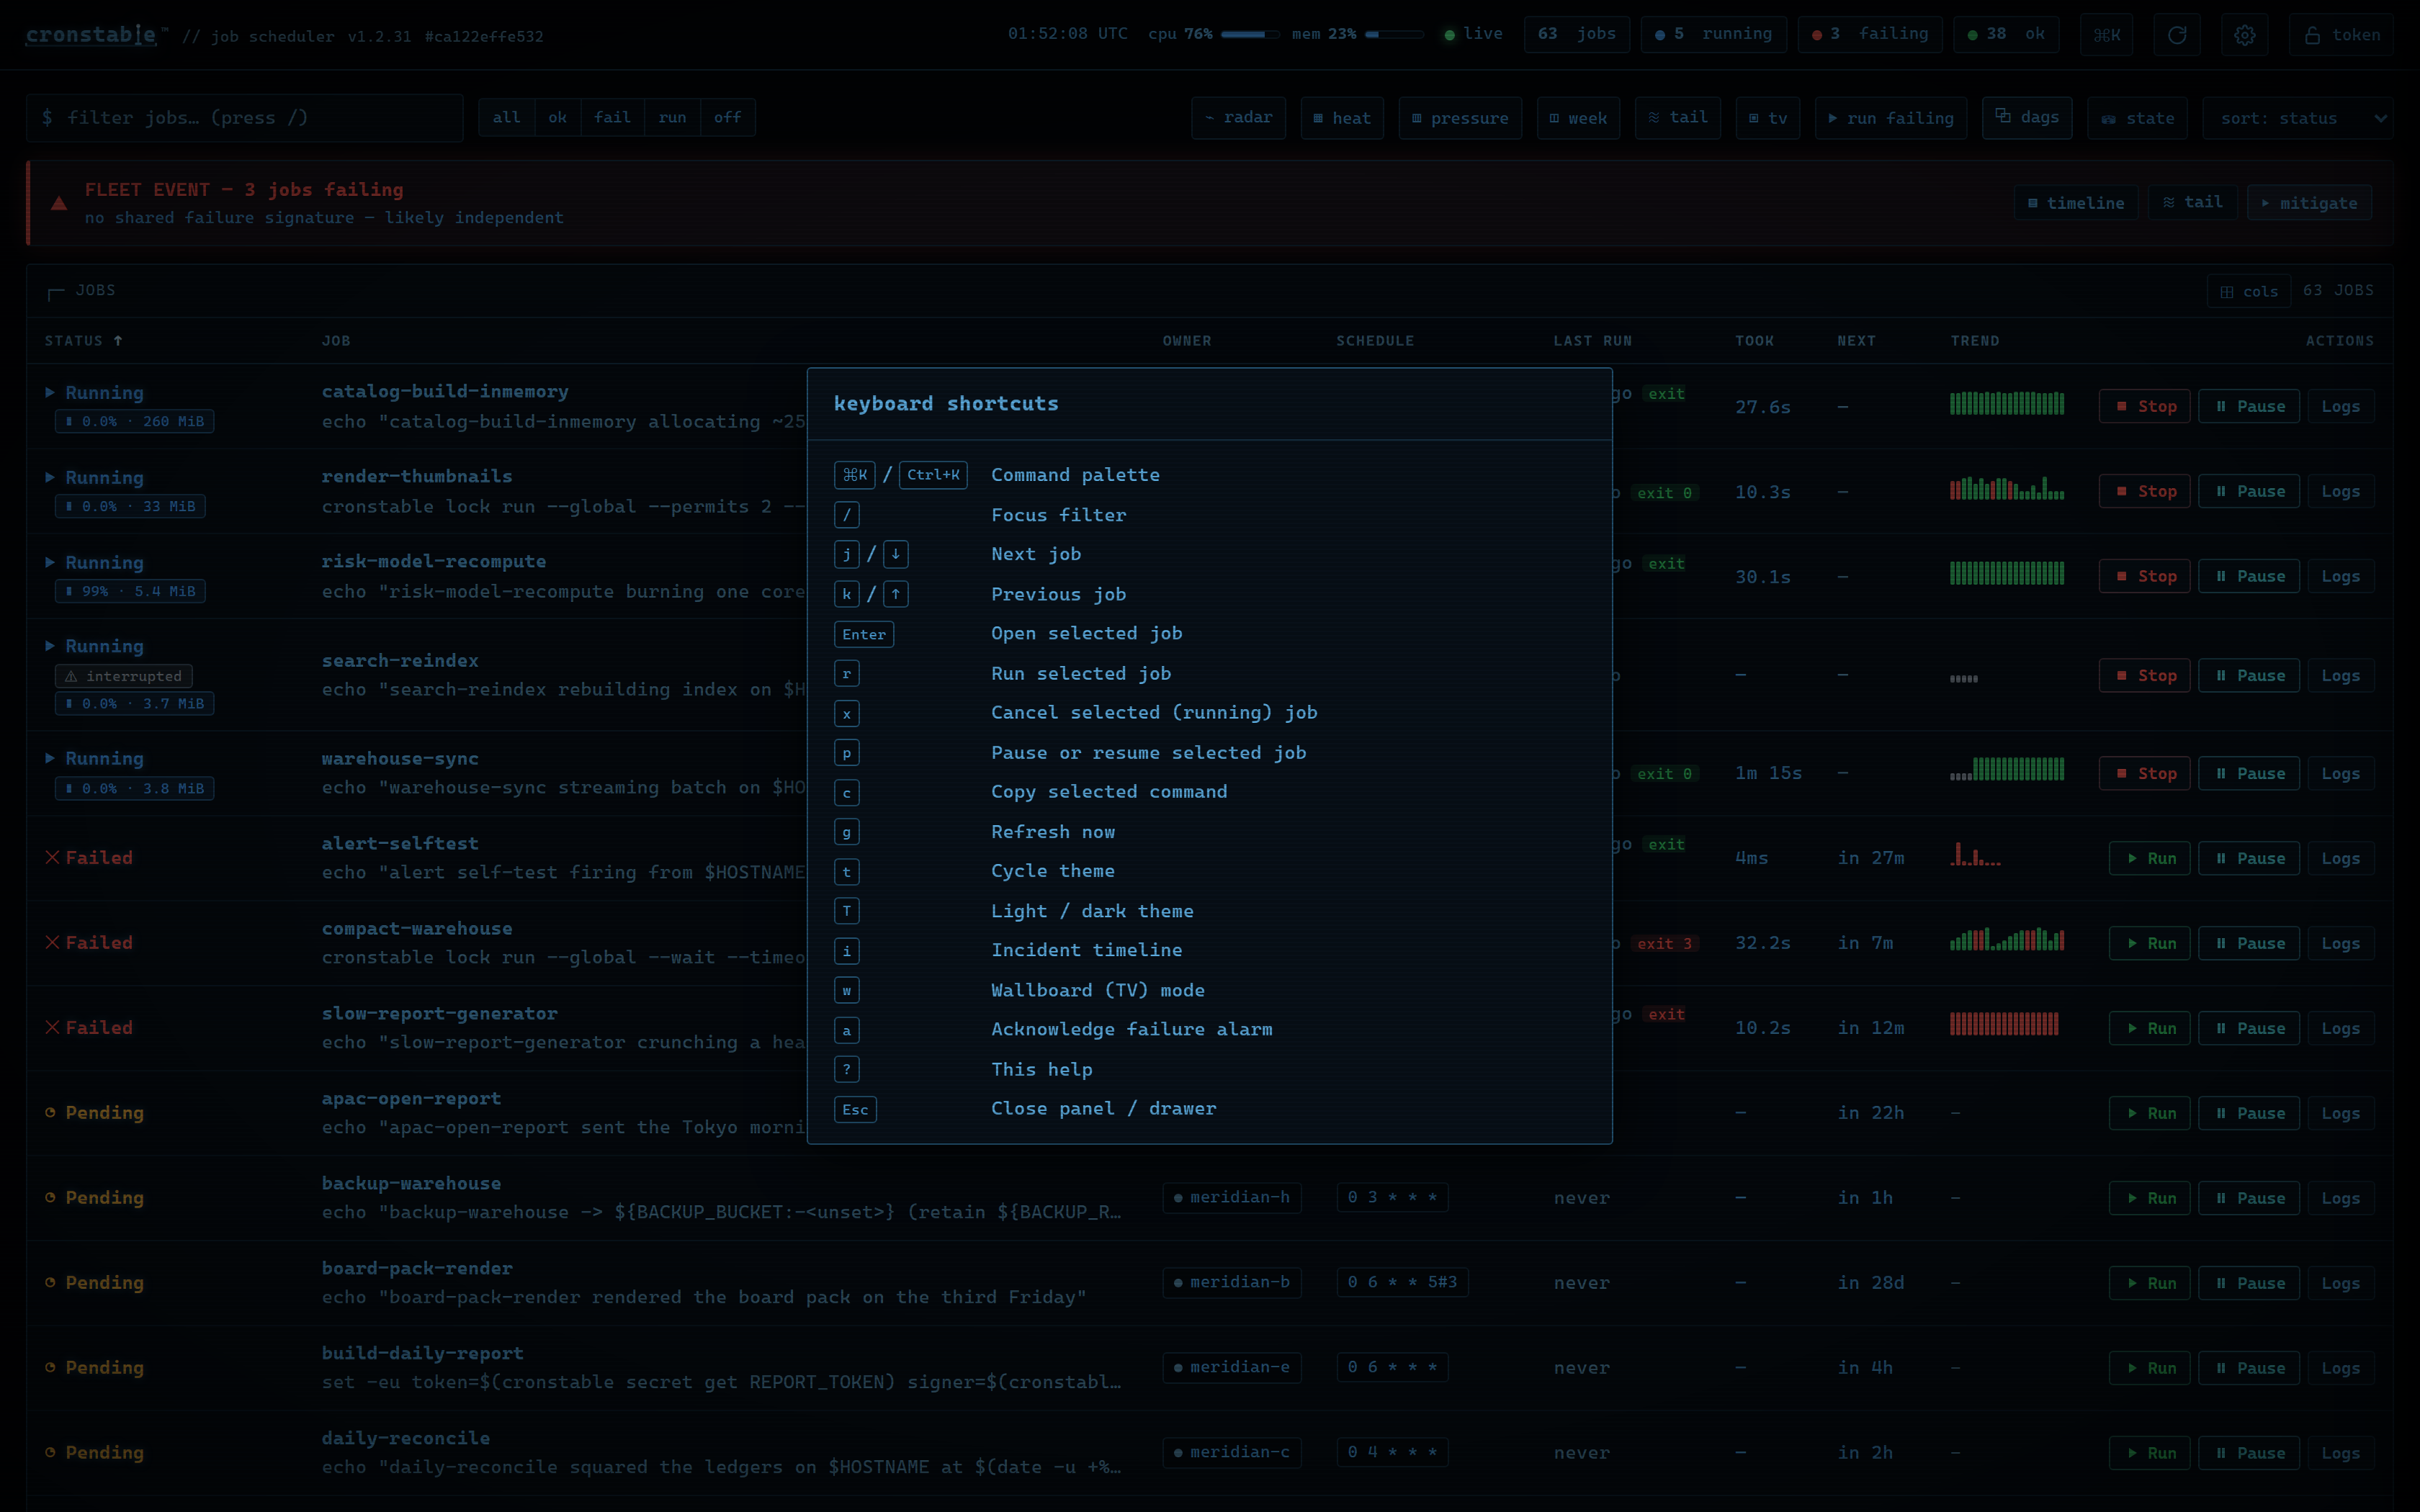
The dashboard is keyboard-first. Press ? at any time for this overlay.
| Key | Action |
|---|---|
Ctrl-K / ⌘K
|
Open the command palette |
/ |
Focus the filter box |
j / ↓
|
Select the next job |
k / ↑
|
Select the previous job |
Enter |
Open the selected job |
r |
Run the selected job |
x |
Cancel the selected (running) job |
p |
Pause or resume the selected job |
c |
Copy the selected job's command |
g |
Refresh now |
t |
Cycle the theme |
T |
Flip light / dark (dark ↔ paper) |
i |
Open the incident timeline |
w |
Toggle the wallboard / TV mode |
a |
Acknowledge the failure alarm |
? |
Show the shortcut list |
Esc |
Close the open panel or drawer |
Ten themes and two interface fonts. GIF version.
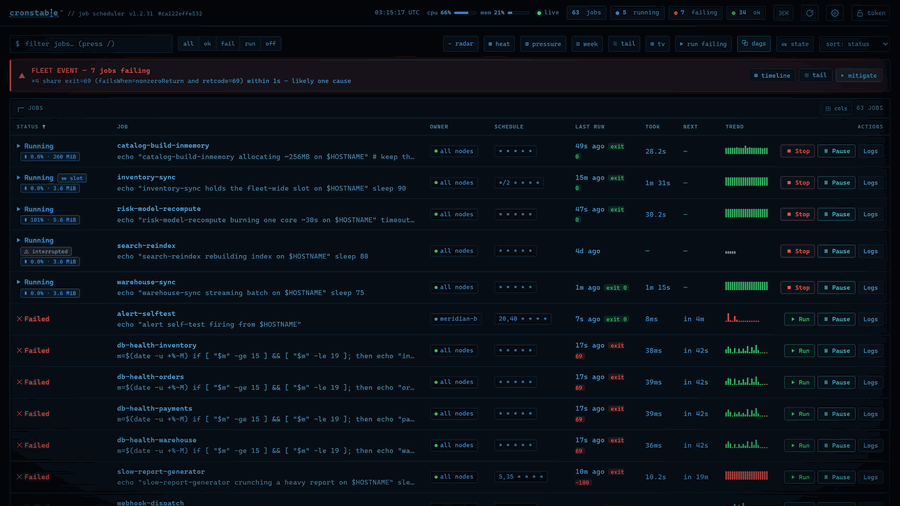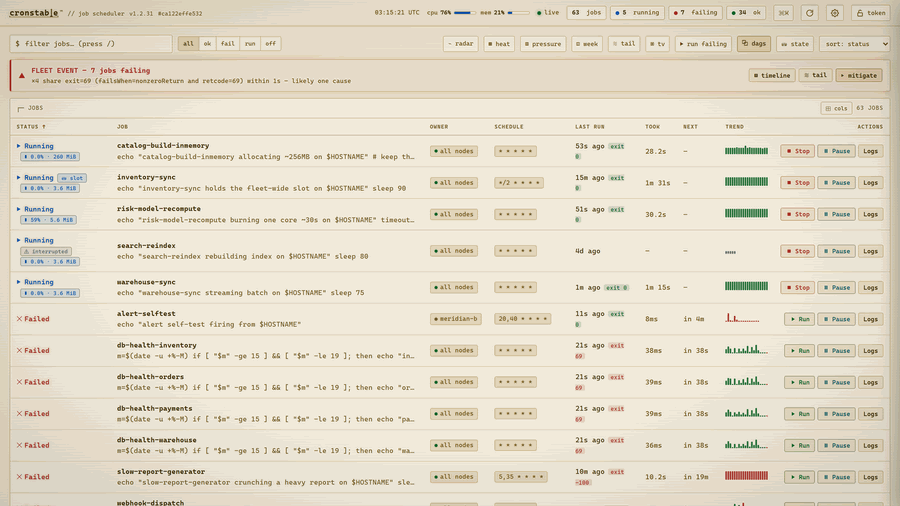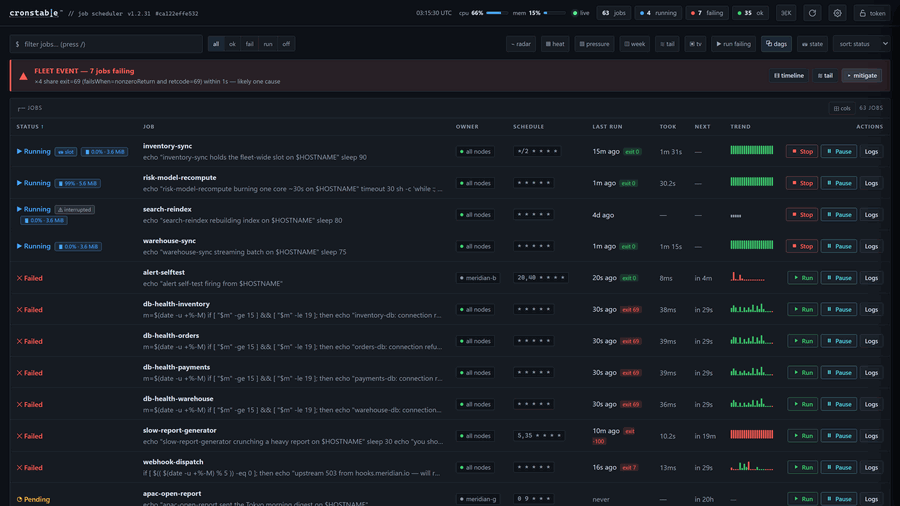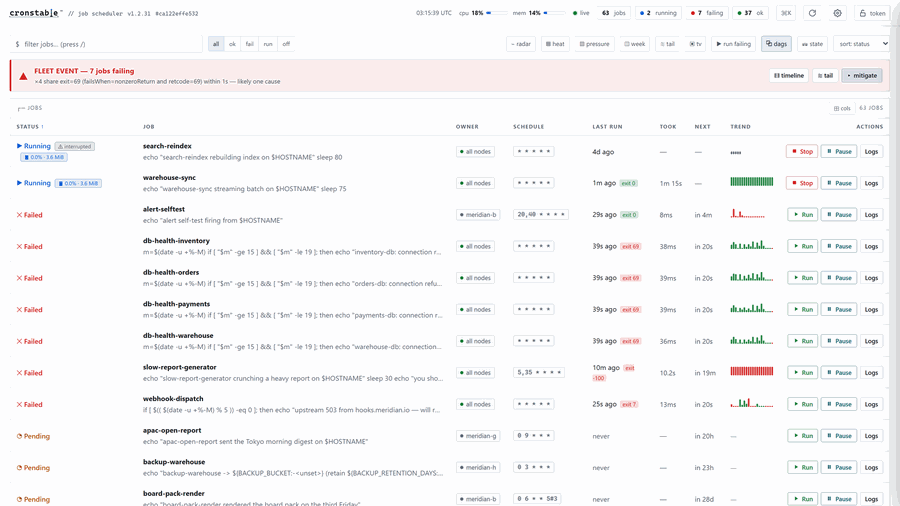
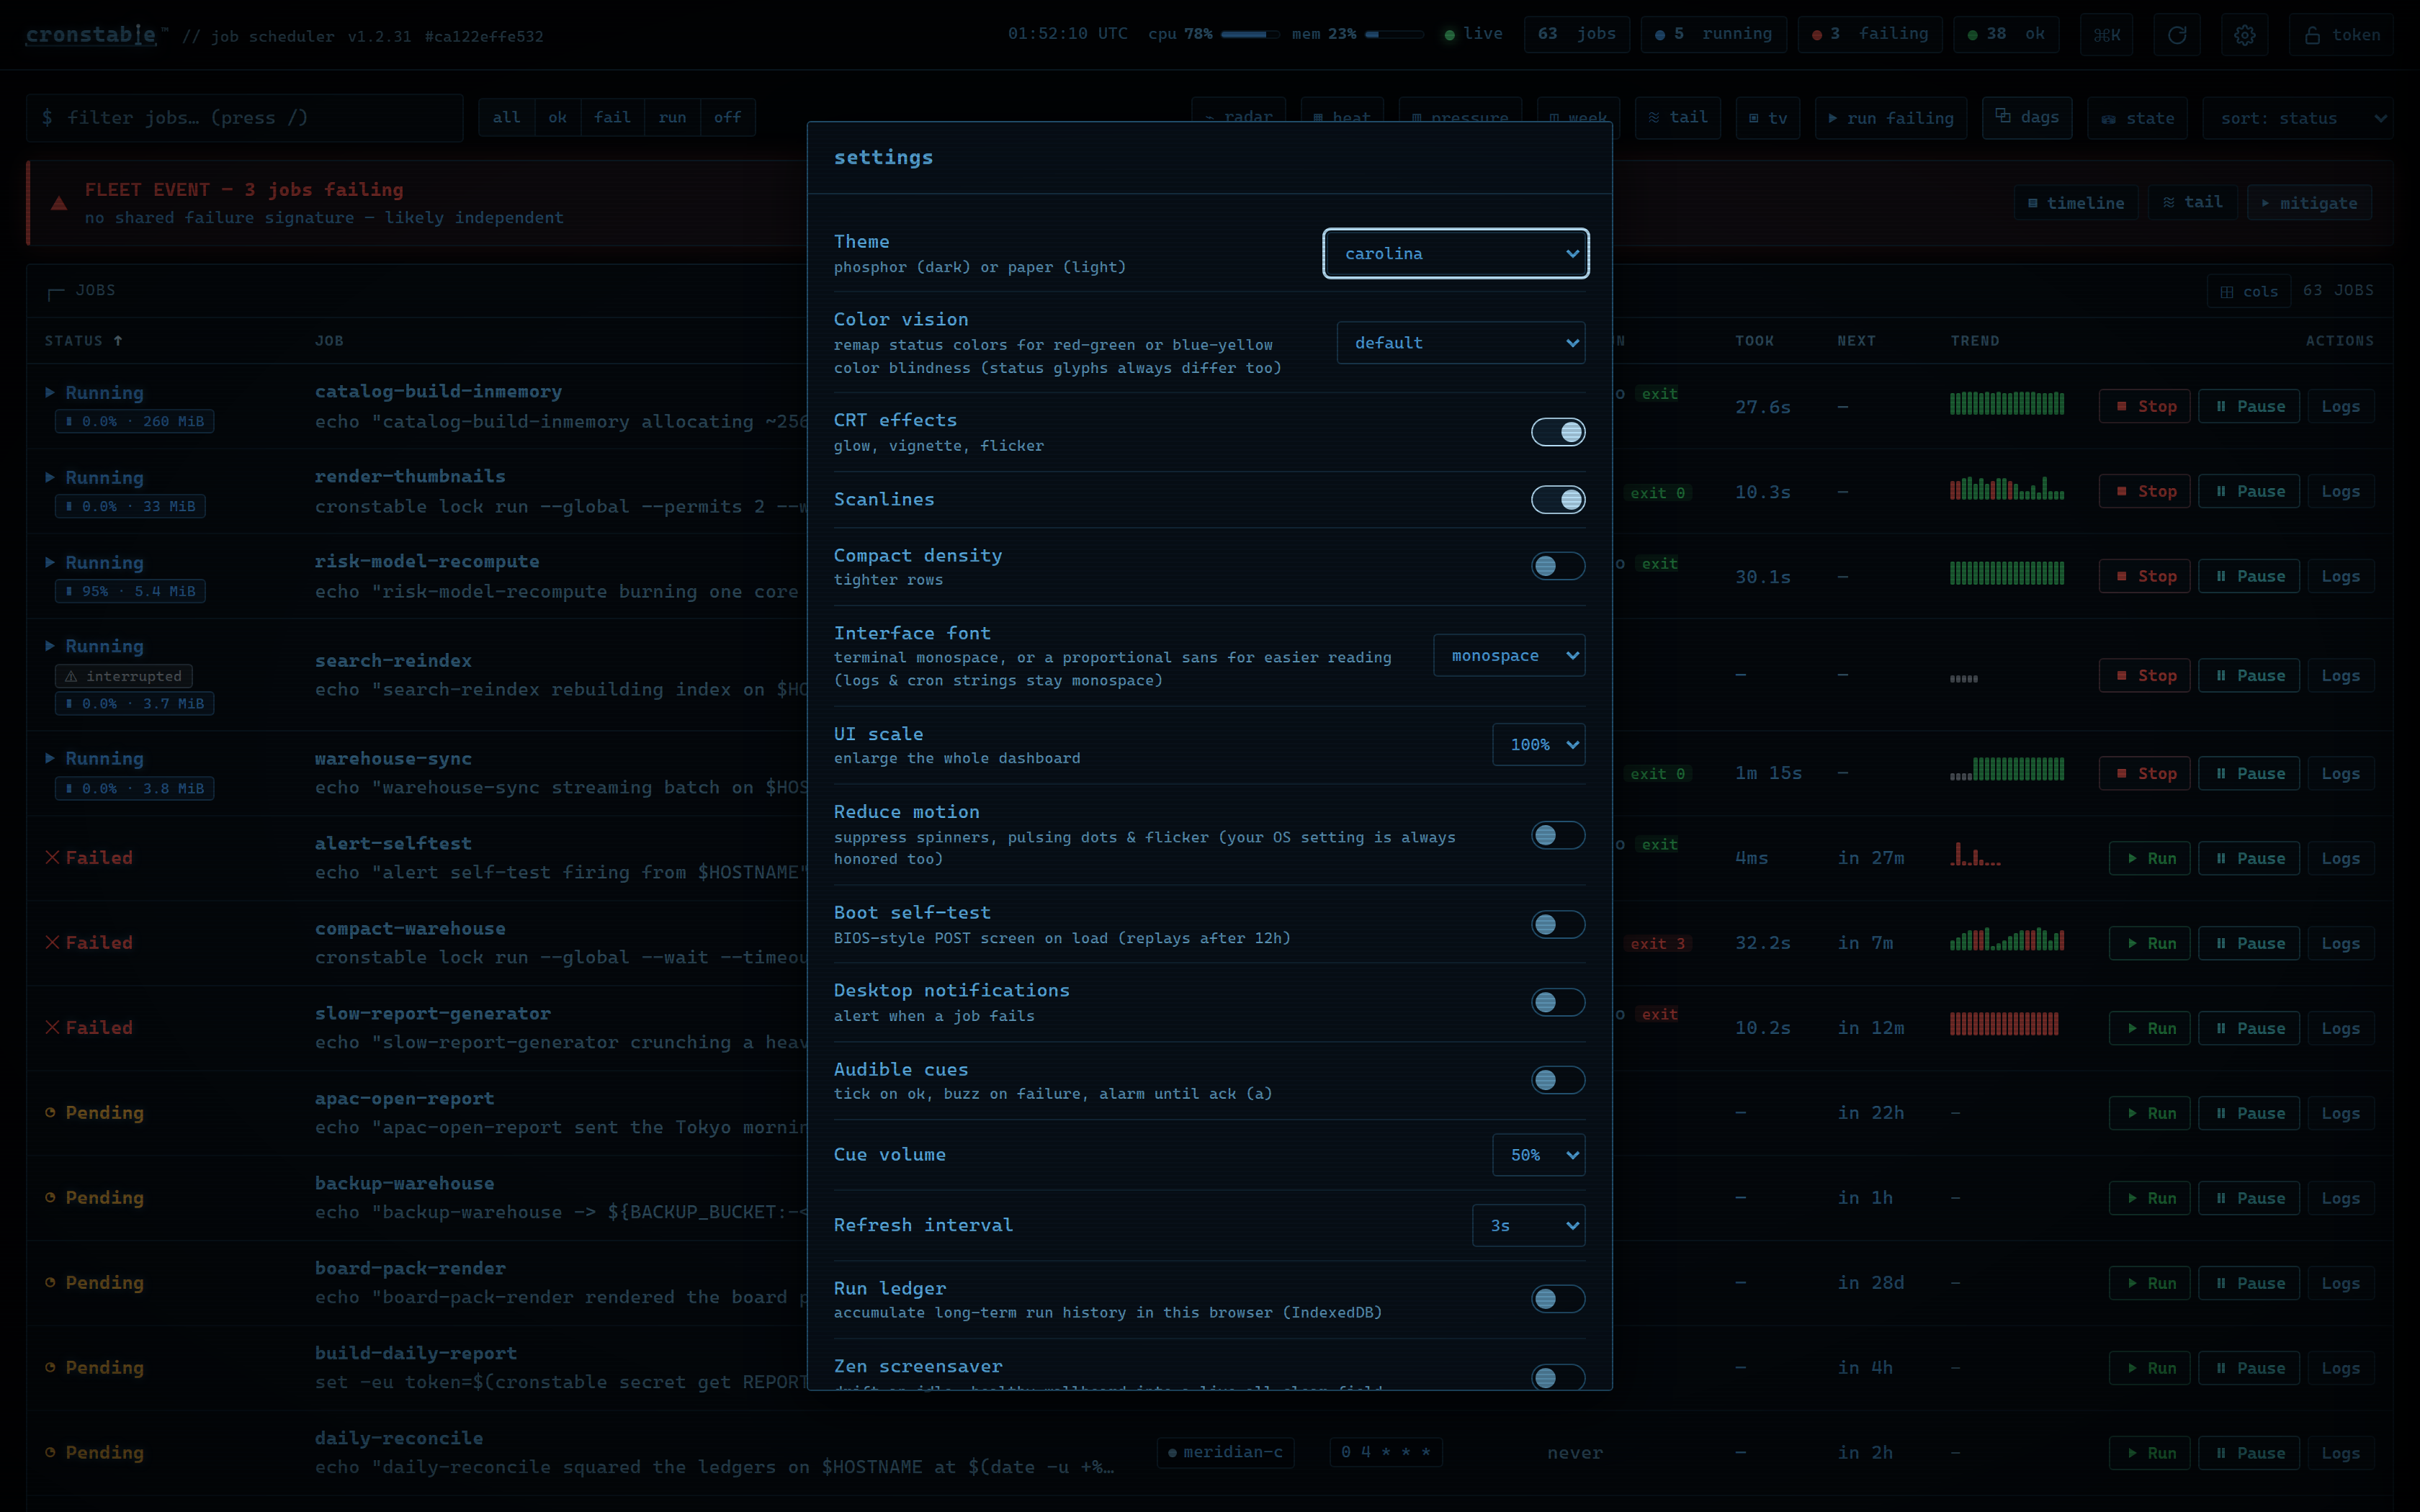
The settings panel (and the command palette) expose:
-
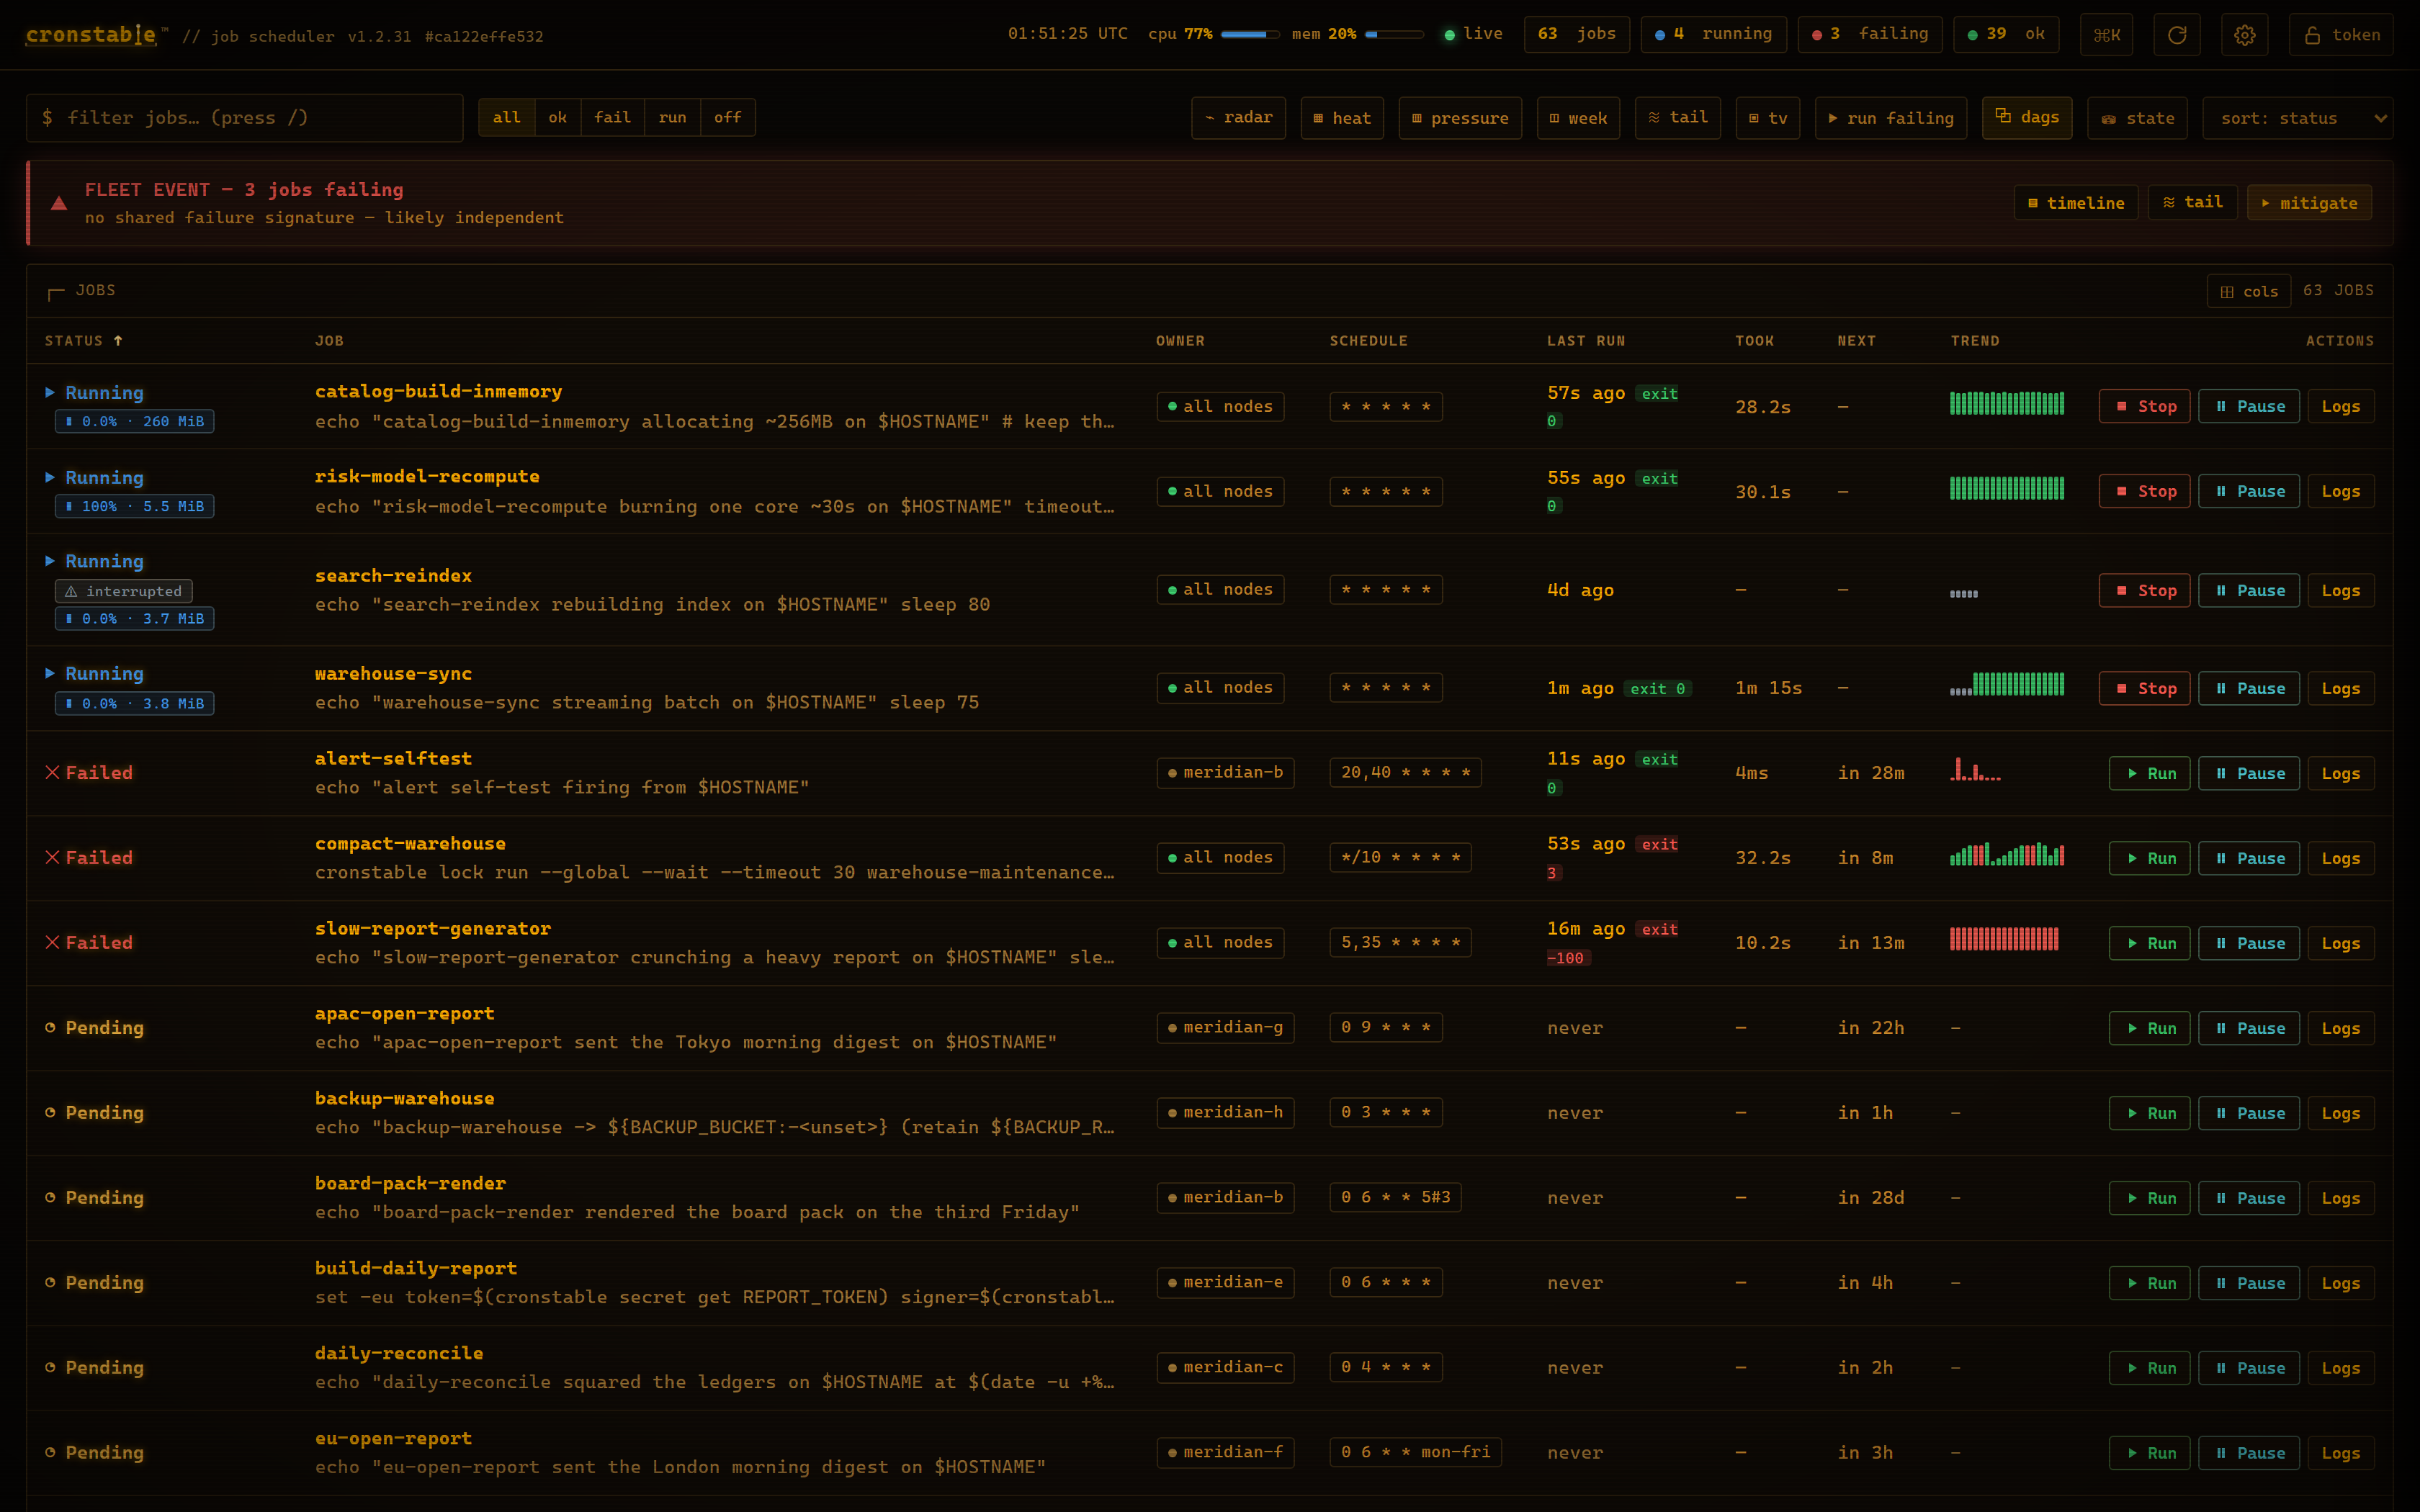
Ten themes: standard (the default, a flat neutral charcoal), carolina (Carolina blue), amber, green, and flat modern, each in a dark and a light (paper) variant. Light variants are dark ink on tinted paper; standard's light variant is plain white with saturated color. Cycle hues with
t; flip light/dark withT. - A color vision mode that remaps the status, cluster-peer, and log-ANSI colors for red-green (deuteranopia/protanopia) or blue-yellow (tritanopia) color blindness, on both the dark and paper palettes. The remapped pairs were chosen with a dichromacy simulation, so every meaningful pair (ok/fail, fail/pending, agreed/drifted, …) stays clearly apart, and every status glyph differs by shape in every mode.
- Compact density for tighter rows.
- An interface font choice: the terminal monospace (default) or a proportional sans-serif that is easier to read at length. Log output, cron expressions, and keycaps stay monospace either way, and numerals stay tabular so clocks don't jitter.
- A UI scale of 100% / 110% / 125% / 140% that enlarges the whole dashboard, useful for wallboard TVs viewed from across the room.
- A reduce motion switch that stops the spinners, pulsing status dots, and the boot self-test without touching your OS preference (
prefers-reduced-motionis always honored). - Startup check (the boot self-test): a BIOS-style POST screen on load that runs real probes against the daemon, job set, cluster, and schedules as it types. It replays only after a 12-hour cooldown, any key dismisses it, and re-enabling the toggle clears the cooldown so the next load shows it.
- Desktop notifications that fire when a job fails, after you grant the browser permission.
-
Audible cues: a short tick when a run succeeds and a buzz when one fails, at a selectable cue volume of 25% / 50% / 75% / 100%. A failure also arms a repeating failure alarm that sounds until acknowledged with
a, which works on the wallboard too; the all-clear, or a fresh failure, re-arms it. -
Alarm escalation: the wallboard reddens and the alarm quickens the longer a failure goes unacknowledged. The cue interval ramps from every 6 seconds down to roughly every 1.6 by the ten-minute mark, and
asilences it until the next failure. - A refresh interval of 1s / 2s / 3s / 5s / 10s, or paused.
- The zen screensaver toggle and its idle delay, for the wallboard.
- The opt-in browser run history, with its storage stats and export and clear history buttons.
All preferences are remembered in the browser's localStorage, so the dashboard
comes back the way you left it.
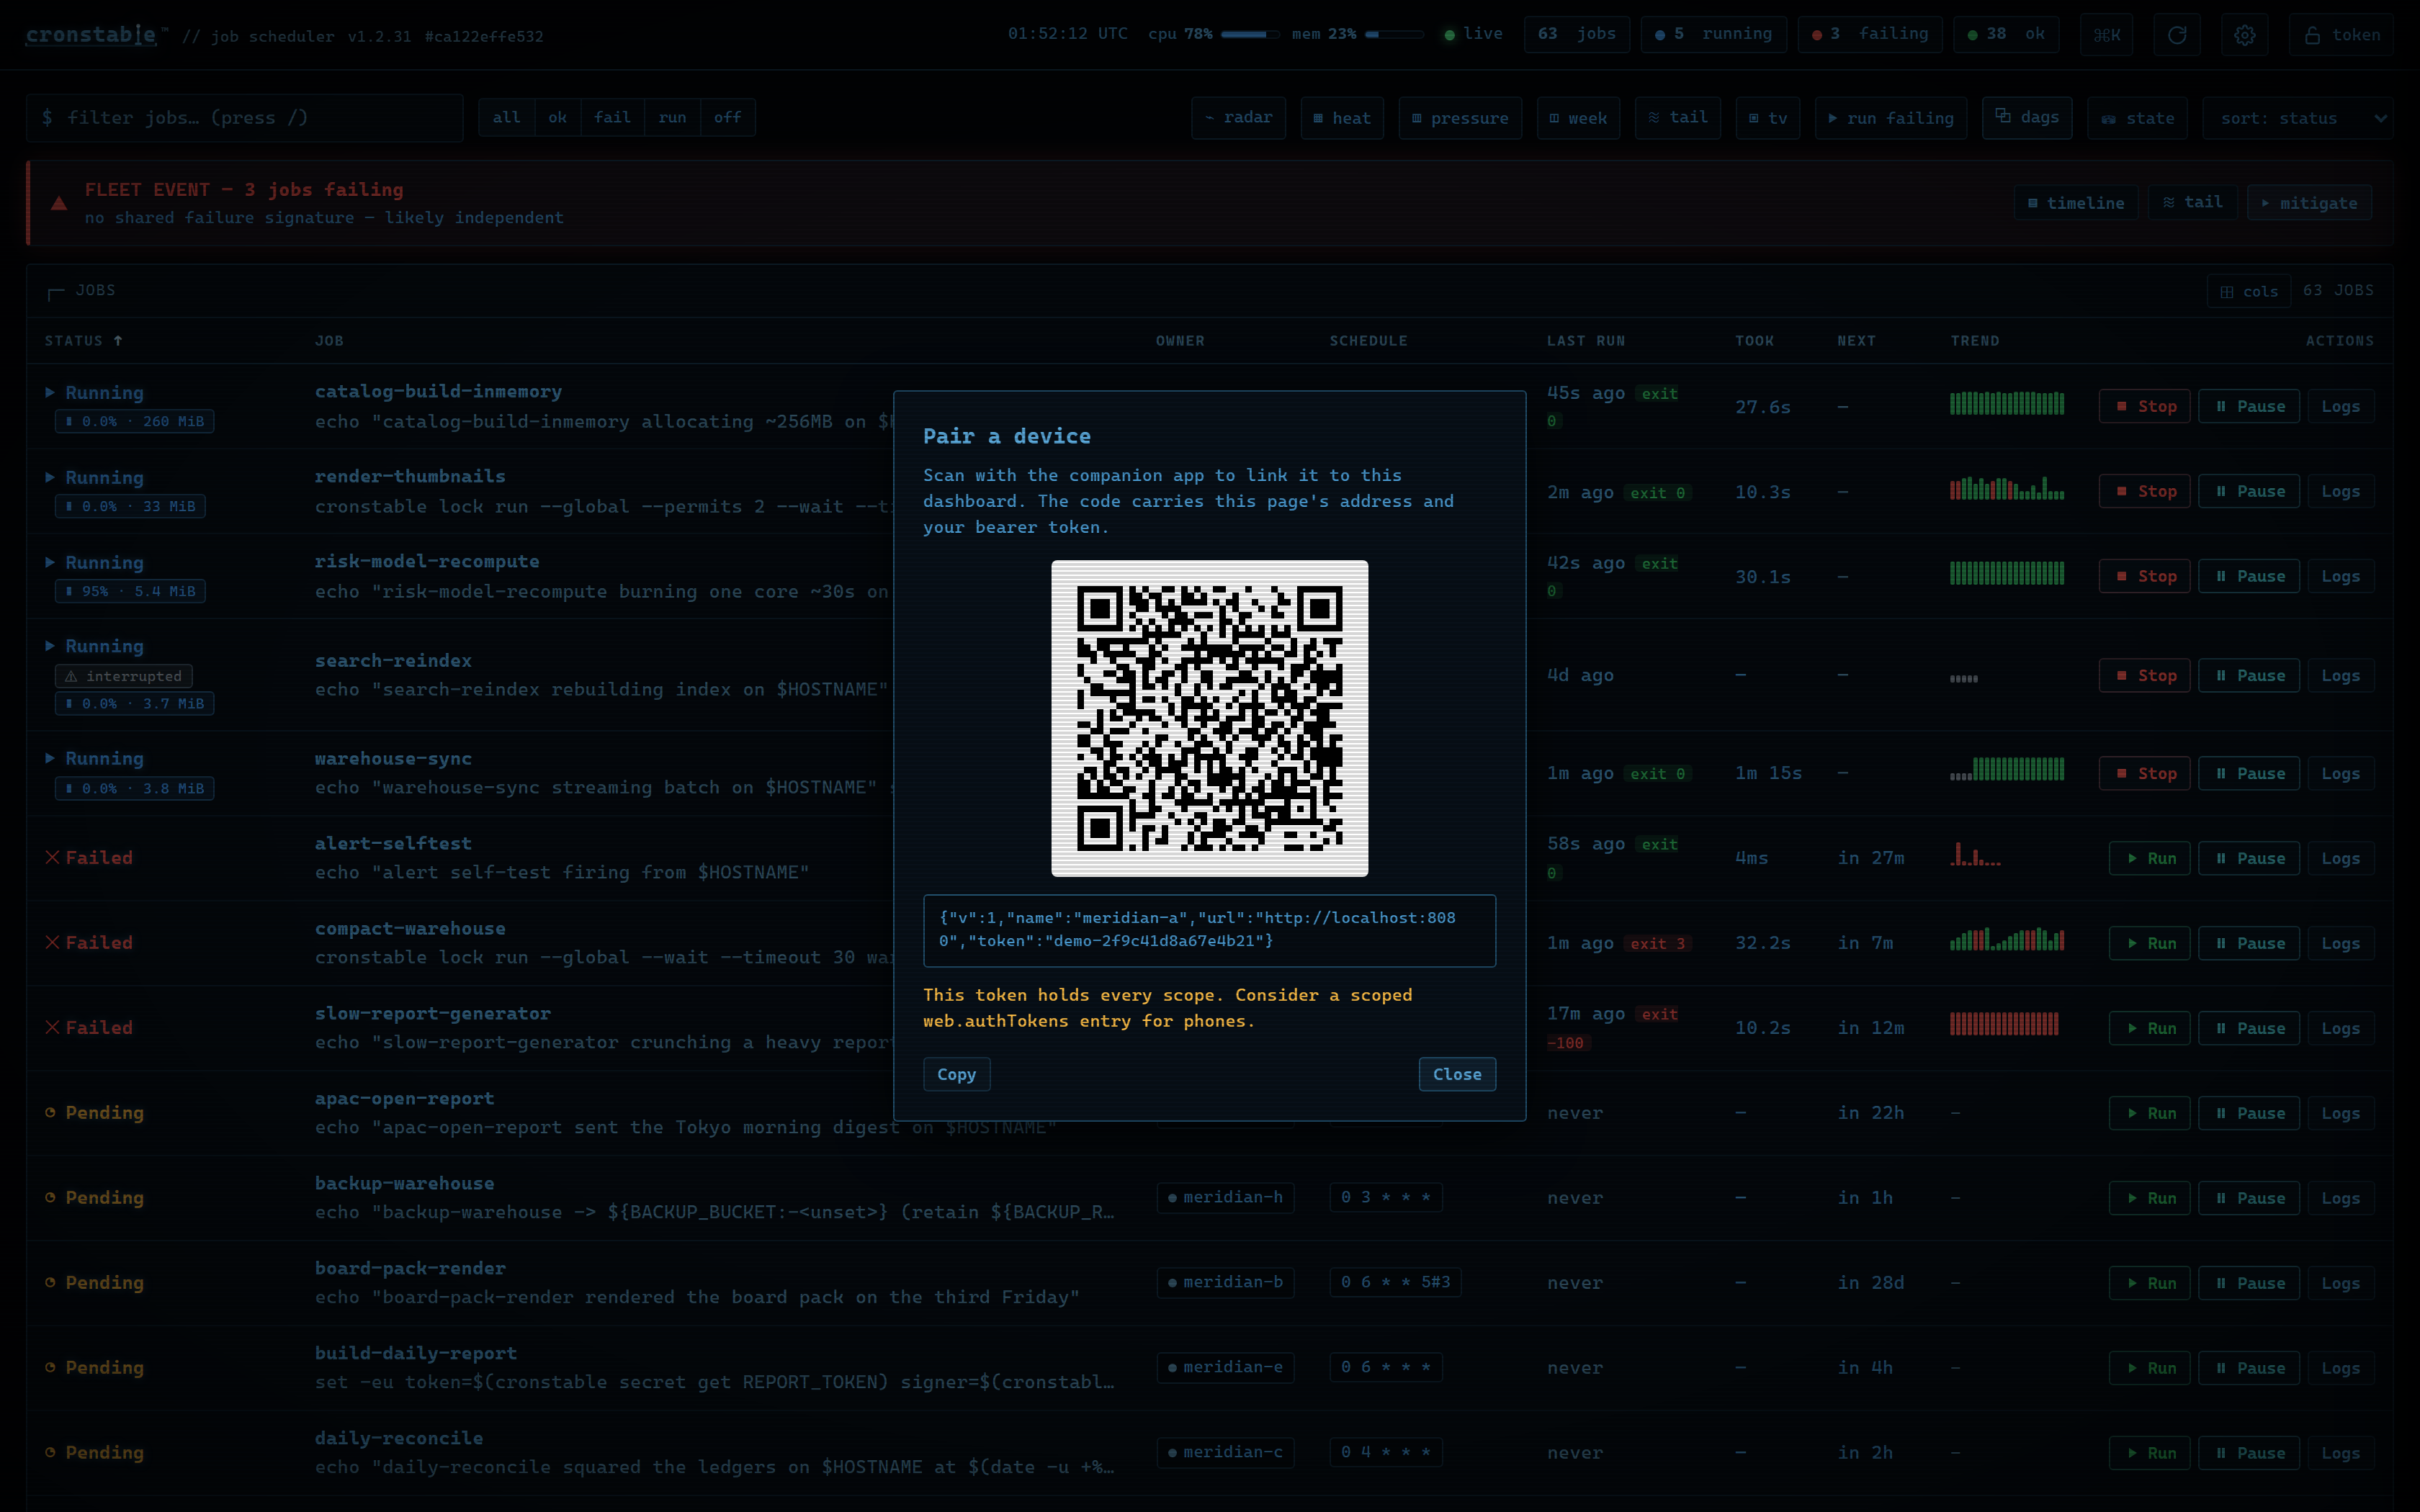
The settings sheet (and the command palette) also open the Pair a device
panel: a QR encoding a pairing deep link. The {v: 1, name, url, token} payload
rides in the link's fragment, so a phone-camera scan opens the companion app.
The same JSON is also available as a copyable string the in-app scanner accepts.
Either form hands the app the daemon's address and bearer token in one scan. The
panel checks the stored token against GET /whoami and
warns when it holds every scope; give a phone a scoped web.authTokens entry
instead. For the pairing flow this feeds, see
push notifications. For the same code without the
dashboard page, see pairing from the terminal.
| Carolina | Amber |
|---|---|
 |
 |
| Green | Flat modern |
|---|---|
 |
 |
| Standard, on paper (light) |
|---|
 |
The browser tab is the dashboard's smallest display, and the one that stays visible after you switch away. The title leads with the worst current condition, so even a truncated tab stays readable:
| Condition | Title |
|---|---|
| Connection lost | no signal · cronstable |
| Cluster degraded | cluster alert · cronstable |
| One job failing | backup-db failing · cronstable |
| Several jobs failing |
3 jobs failing · cronstable, then each failing job by name |
| One job running | backup-db running · 42s · cronstable |
| Several jobs running |
3 running · cronstable, then each run with its elapsed time |
| All quiet |
14 ok · cronstable, then next: backup-db in 12m · cronstable
|
When a state needs more than one tab-width line, the title rotates complete readouts every four seconds rather than scrolling characters. A fleet event cycles the failing count and then every failing job by name; several runs page through each job with its elapsed time; a cluster alert adds its reason; the quiet state alternates the healthy count with the next fire. Each frame is a whole line, so a backgrounded tab, which advances only as the slow poll refreshes it, always shows one true readout instead of a fragment of scrolled text.
The readouts are plain words with middle-dot separators, and elapsed times tick each second while the tab is visible. On a cluster node the trailing brand is the node's own name, so with a tab open per node you can tell which is which.
The favicon is the cronstable mark: the pendulum standing on its cart, inlined into the page as a data URI so the dashboard stays a single self-contained file. It holds steady whatever the fleet is doing, so a pinned tab reads as the app rather than as an alarm.
A hidden tab keeps polling at a slow 30-second cadence rather than stopping, so the title, desktop notifications, the audible alarm, and the run ledger stay current while you work elsewhere. The foreground refresh interval resumes the moment the tab returns.
When bearer-token authentication is enabled
(web.authToken), the dashboard page itself loads without a token: it
carries no data and no secrets. The first data request returns 401, and the
dashboard then prompts you for the token, stores it only in that browser tab
(sessionStorage), and attaches it as Authorization: Bearer … on every
subsequent request. You can update or clear the stored token from the header's
token button at any time. Saving or clearing a token rewrites the calendar
feed links from the new token and empties the pairing sheet, so no link or
payload in the tab keeps the previous token.
The token prompt opens on top of any other open panel. When a 401 opens it
while the command palette is open, the dashboard closes
the palette, and the prompt takes the keys: Enter saves the token, and Esc
closes the prompt.
A #job/<name> or #dag/<name> link, such as the one on a
status badge, opens the token prompt first,
and the link's drawer opens after you save the token.
On load the dashboard asks GET /whoami what it is
allowed to do, and draws only the controls that scope covers. With every scope,
or against a daemon with no authentication configured, it draws the full
interface. It asks again on the first good poll after a lost connection and
on the first good poll a minute or more after the last read, and redraws
only when the scopes changed. A daemon reload or restart that changes
the token's scopes or the badge settings
therefore reaches an open page within about a minute, without a page reload.
Without control, the dashboard omits the Run, Stop, Pause, and Resume
buttons, the DAG Trigger and Backfill buttons, "run failing", and the mitigate
console. The palette entries and the r/x/p shortcuts that reach those
same actions go with them, so a read-only visitor is never offered a button
whose request can only fail with 403. Without approve, the dashboard draws a
waiting gate as a state rather than as a pair of decision buttons.
The same rule covers a scoped web.authTokens entry and a
public read-only board.
On a public board the token prompt never appears: the header's token button
reads view only, and pressing it lets an operator paste a token, which
re-probes /whoami and redraws.
The dashboard is a thin client over the HTTP control API:
- it polls
GET /jobson the refresh interval for the overview (each job carries a compact tail of recent runs for the sparkline). Every poll bypasses the browser's HTTP cache, and each poll after the first sends the previous response'sETaginIf-None-Match. When only the countdowns have moved, the daemon answers304 Not Modified, and the dashboard keeps the jobs it holds and continues each countdown from the response that carried it. If the browser's wall clock and monotonic clock disagree about the age of that response by one second or more, as they can after the computer sleeps or its clock is set, the next poll omitsIf-None-Matchand takes a full response; - it polls
GET /clusteron the same interval for the cluster panel (the panel stays hidden unless a cluster section is configured); -
GET /node(the header's node meter),GET /dags(the workflows card), andGET /pools(the resource pools card) ride the same poll; - while the fleet view is open,
GET /fleetrides the same poll (the daemon answers it from gossip state it already holds); - the state inspector probes
GET /stateonce at load (to decide whether to offer its button), polls it only while the card is open, and drills into scopes withGET /state/documents/GET /state/records; - the node resources card refetches
GET /node/historywhile it is open; - opening a job's History tab fetches
GET /jobs/{name}/runs(full retained history plus aggregate stats); the activity heatmap fills from one batchedGET /activity?jobs=80fetch and keeps the capped per-job loop as a fallback against an older daemon; - opening a job's Resources tab fetches
GET /jobs/{name}/resourceslazily, never on the poll loop, and refetches it at the live view's selectable pace while the tab stays open; - opening the Logs tab opens the
GET /jobs/{name}/logsSSE stream; - the live logs panel opens up to four of those SSE streams at once (one per tailed job) and re-attaches them as runs come and go;
- the DAG drawer fetches
GET /dags/{name}/runs, the selected run's document and XCom list, and a running task's log SSE stream; its buttons callPOST /dags/{name}/trigger,POST /dags/{name}/backfill,POST /dags/{name}/recover,POST /dags/{name}/runs/{run_key}/recover, and the approval decision endpoint; - the Run / Stop buttons call
POST /jobs/{name}/startandPOST /jobs/{name}/cancel; - the version in the header comes from
GET /version, and the job-set ID chip beside it fromGET /job-set-id(each fetched once at load).
By default, the daemon keeps run history (the most recent 50 runs per job)
and captured output in memory, resetting both on restart. A
durable state store preserves run history, and
archiveOutput can
also save output. The Logs tab replays only output buffered by the current
process.
-
Terminal Dashboard: monitor and control jobs with
cronstable tui. - MCP: access for AI agents.
- HTTP Control API: the REST endpoints, configuration schema, authentication, and Unix-socket options the dashboard is built on.
-
Pausing Jobs: the runtime pause behind the
⏸chip and thepkey. -
Late-Run Detection: the
sla:monitor behind the OVERDUE badge. -
Clustering and Leader Election: the cluster panel, per-job
clusterPolicy, and theGET /clusterview it polls. -
Orchestration and DAGs: the
dags:semantics behind the DAG card and drawer. - Durable State: the store the state inspector inventories, and what rehydrates run history across restarts.
-
Resource Monitoring:
monitorResourcesand the node endpoints behind the Resources tab and the header's node meter. -
Resource Limits: the
resourceLimitscaps behind the caps chip, the cap lines, and the History tab's cap chips. -
Output Capturing:
captureStdout/captureStderr, which control what the Logs tab can show. - Schedules and Timezones: the schedule strings and time zones the Schedule tab explains and previews.
- Production and Container Deployment: running the interface under a hardened, read-only-root-filesystem deployment.