crickets research - alexherrero/crickets GitHub Wiki
Note
LAUNCHED (lifted 2026-06-24, AG Phase 3; originally approved 2026-06-23) · locked 2026-06-28 (final AG design sweep). child-design — the research capability (deep research + web fetch + synthesis), parent crickets HLD. status: launched (lifted into tracked wiki/designs/ 2026-06-24, AG Phase 3). Points up at the crickets HLD.
research is the capability that brings in what the agent hasn't seen — codebase fan-out and bounded web lookups, synthesized into something the work can use. It is the Researcher persona's composition, and the Architect and Designer personas compose it too. It is two read-only agents and a read-only vault scan; the deeper multi-source work is forward-referenced to an operator-personal agent, by name and contract.
Research runs on demand: it answers a question now. explorer (delivered), researcher (delivered) and idea-search (delivered) find what's already in the vault and the codebase before reaching outward. Keeping up with the field on a schedule is agentm's weekly field brief, not part of this capability.
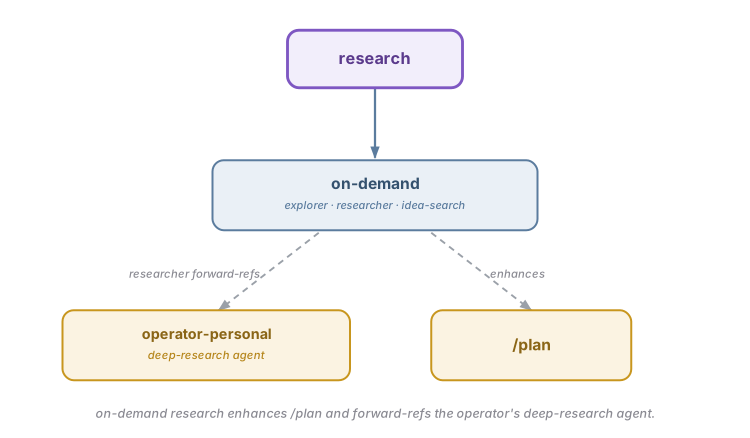
On demand only — deep multi-source work is forward-referenced to an operator-personal agent, and the capability enhances /plan.
- Entry: dispatched with one specific question about the codebase (tools: Read/Glob/Grep).
-
Exit: a structured short answer with
file:linereferences + caveats. - Automated: file-level search answering the one question; dispatched in parallel only for independent questions, never to split a single one.
- Artifacts: none — read-only.
- Entry: dispatched with a research question (tools: Read/Glob/Grep/WebFetch).
- Exit: structured findings with references + caveats.
-
Automated: dispatches
explorerfor in-repo fan-out and runs its ownWebFetchfor a few targeted lookups; forward-references an operator-personal deep-research agent by name when one is installed, degrading toexplorer+WebFetchotherwise. The bounded-web boundary is deliberate — unbounded crawling is the named anti-pattern. - Artifacts: none — read-only.
-
Entry:
idea-search <question>— invoked before reaching outward, to surface ideas already captured in the vault + codebase that bear on the question. - Exit: a ranked set of existing relevant entries, so research starts from what's known.
- Automated: a read-only scan over the recall engine.
- Artifacts: none — reads memory, writes nothing.
Delivered — src/research/scripts/idea_search.py, covered by scripts/test_research_idea_search.py.
learn-forward and codebase-improvement retired on 2026-10-03 with agentm's forward learning, which agentm's weekly field brief replaces (research 0.3.0; see the amendment log).
research borders the skill-discovery seam (agentm's adapt_skills.py + adapt-evaluator, which surface candidates to the operator's skill watchlist). Research writes nothing to that watchlist, and it creates no reverse coupling: it cannot consume the watchlist to auto-adopt. The direction stays discovery → watchlist → operator-gate, and the operator gate is the sole sink.
explorer + researcher + a new idea-search, which shipped a real research capability without touching unbuilt infrastructure. The scheduled half that followed it in 2026-07 has since retired.
research leans on how-we-engineer — it feeds the plan → design → architecture sizing ladder, bringing in what the work needs to know before it plans. No shipped prose site to bind yet — the design's own stated lean, not yet realized in a runtime prompt (src/research/ carries no skill/command markdown, only scripts/; PLAN-wave-d-personas task 1 grounding pass, 2026-07-07). Request-by-name is Phase-3/4 — the Opinions design.
-
enhances
development-lifecycle'splan(soft) — research informs the brief before planning;researchersits at the front of the loop. It works standalone, so it enhances rather than requires the loop (matching the composition map). -
leans on the recall engine for
idea-search(agentm Memory System). - composes with an operator-personal deep-research agent by forward-reference when present — by name and contract.
- borders the adapt-don't-import seam (one-way: discovery → watchlist → operator-gate).
- Points up at the crickets HLD; the requires/enhances mechanics are in crickets-composition; the Researcher persona is in agentm Personas.
-
Deep multi-source research is forward-referenced.
researcherreferences an operator-personal deep-research agent by name + contract when one is installed, degrading toexplorer+ boundedWebFetchotherwise. Revisit if the forward-reference proves insufficient in real use. -
idea-search's relevance bar — a vault scan that surfaces stale or tangential ideas wastes the "find what's known first" step; calibrate the recall threshold so it returns genuinely-bearing entries, not everything adjacent. -
Re-audit triggers: revisit the forward-reference approach only if it proves insufficient in real use; re-verify
idea-searchagainst agentm'srecall.queryif agentm changes its signature.
-
The agents:
researcher+explorer(read-only;researcherforward-references an operator-personal deep-research agent when present) -
The recall engine
idea-searchleans on: agentmharness/skills/memory/scripts/recall.py(agentm Memory System) -
The adapt-don't-import seam it borders: agentm
harness/skills/memory/scripts/adapt_skills.py·harness/agents/adapt-evaluator.md(discovery → watchlist → operator-gate) - Siblings: crickets HLD · composition · agentm Personas (Researcher) · agentm Experience (its weekly field brief replaced forward learning)
2026-10-03 — scheduled forward-learning retires with agentm's forward learning (research 0.3.0). The operator scrapped forward learning on 2026-10-02 (agentm task 185), and agentm #841 deleted forward_learning.py, its review CLI watchlist_review.py and the job template, and archived resources/watchlist/ under projects/agentm/completed/forward-learning-2026-10/. A weekly field brief replaces it. learn-forward had no engine left: agentm_bridge.load_forward_learning_module() found agentm's scripts dir by recall.py and then raised FileNotFoundError on the missing file, which turned check-all's unit-test gate red on any machine with a current agentm checkout. codebase-improvement would have recreated the archived folder, and its findings had no reader once watchlist_review.py went. Both primitives, their tests and the bridge's forward-learning loaders are gone, and so is the wiki plugin's vault_layout.watchlist_dir() (wiki 0.13.1). The bridge's sibling-swap tests now run against a stand-in recall.py, so the swap stays covered in CI. Research is on-demand only. The body sheds the scheduled half, the diagram drops it, and the forward-experience dependency is gone. Why not keep learn-forward and return None when the file is missing: the feature's engine is scrapped, not absent, and agentm says the field brief replaces it, so a primitive that silently does nothing would still be documented as delivered. Re-audit trigger: agentm reviving a scheduled-learning engine that crickets is meant to drive, or a research primitive needing to write to the vault again.
2026-09-13 — nothing in research writes to a retired memory-space home, and the bridge gives agentm its own siblings for calls too (research 0.2.5). codebase_improvement.py fell back to an existing memory/, personal/ or personal-private/ _watchlist whenever Projects/agentm/_watchlist did not exist yet, and chose memory/_watchlist on a vault with neither. It now always writes to Projects/agentm/_watchlist, and counts a standards/ dir beside the root as the vault-root witness, as agentm's vault_layout does. The learn-forward no-writes test allows only that home, and its fixture writes the sources whitelist to Projects/agentm/. The research 0.2.4 entry allowed the retired homes so an older agentm could still run the test; that trade is reversed, because a scan writing to a retired home is the failure to catch. The entry below isolates the real-bridge suites' imports for a whole test class; the bridge now also runs every call, not only the load, inside _agentm_names, so a bare import agentm makes inside a function gets agentm's module in any process; learn_forward.py runs its scan through the bridge's new run_forward_learning(). Why not stop at the load: recall.query imports lifecycle inside the call, and lifecycle imports vault_layout. Re-audit trigger: a caller reaching an agentm function without going through the bridge, which gets no swap.
2026-09-13 — call-time imports in the real-bridge suites get agentm's siblings too. The entry below left one re-audit trigger open, a bare sibling import that agentm makes inside a function, and it had already fired through a path that entry does not name. recall.py imports lifecycle inside a function, and lifecycle's own import vault_layout ran after the swap had put the suite's modules back, so four real-bridge suites, idea-search's among them, handed agentm the wiki's module and passed only because none asserts on lifecycle's sidecar. scripts/agentm_isolation.py now sets same-named modules aside for the life of a real-bridge test class, with agentm's scripts dir first on sys.path, and every real-bridge suite except learn-forward's calls it. Learn-forward's stays on the bridge's swap, so its tests keep exercising that swap end to end. The bridge is unchanged. Why not in the bridge: a swap that outlived the load would hand the process's own code agentm's modules, and the research CLIs, each in a process of its own, never meet the clash. Re-audit trigger: a research CLI running in a process that also loads the wiki plugin's scripts, or the import hook finding a borrow again.
2026-09-13 — the bridge gives agentm its own siblings, and the learn-forward test names the watchlist's homes again (research 0.2.4). The entry below set same-named modules aside in the test, which protected one test class. The clash sits in the bridge: any process that already holds another vault_layout hands it to agentm. For the length of a load, agentm_bridge.py's _load_module now puts agentm's scripts dir first on sys.path and sets aside any module held under one of that dir's script names but loaded from another file, then puts those modules back. The test's own set-aside is gone, so the real-bridge tests go through the bridge's; scripts/test_research_agentm_bridge.py pins it against a stand-in agentm, so CI runs it. The no-writes test names the watchlist's homes again, Projects/agentm/_watchlist plus the memory-space spellings, and setUp writes the whitelist at SOURCES_CONFIG_REL. watchlist_root() and sources_config_path() only exist since agentm #602, so asking them made the test error against any older agentm. The content snapshot and the wrote-nothing guard stay. Why not keep asking agentm: an older agentm checkout could not run the test at all; the cost is that on the current agentm the test also accepts the retired homes. Re-audit trigger: the watchlist moving again, or a bridge caller reaching a bare sibling import that agentm makes inside a function. The swap covers module execution only, so such an import gets the restored module; recall.py's session_start and _collect_always_load_paths already import vault_layout that way.
2026-09-13 — the learn-forward test asks agentm's resolvers where the watchlist is. agentm's memory-root trims moved the watchlist to Projects/agentm/_watchlist/ and put the sources whitelist beside it. scripts/test_research_learn_forward.py still allowed only memory-space watchlist paths, so it failed a correct scan. In the full suite it errored before reaching that check: the wiki plugin's vault_layout module, loaded earlier in the same process, shadowed the vault_layout that agentm's forward_learning.py now imports. The test now takes both homes from agentm's watchlist_root() and sources_config_path(), sets same-named modules aside while agentm is loaded and restores them afterwards, and stubs the fetcher in its CLI smoke test, which had been sending a real GET. The body names the resolvers where it named personal/_watchlist/ and _meta/. Why not list the new paths: the watchlist has moved three times, and a list of paths went stale on each move. Re-audit trigger: agentm renames either resolver, or CI starts checking out agentm for these tests.
2026-07-07 — scheduled forward-learning shipped; research is now fully delivered (PLAN-wave-c-research-forward-learning). learn-forward (src/research/scripts/learn_forward.py) and codebase-improvement (src/research/scripts/codebase_improvement.py) landed, unblocking the [PENDING-IMPL] this design named at approval. learn-forward is a thin wrapper leaning by name on agentm's real forward-learning pipeline (harness/skills/memory/scripts/forward_learning.py, shipped the same day as PLAN-wave-e-experience task 1 — the substrate this design was waiting on); agentm_bridge.py (idea-search's existing bridge module) gained load_forward_learning_module(), the same resolver pattern load_recall_module() already used. codebase-improvement is self-contained — stdlib-only substring scan for a stale pattern, writes exactly one watchlist finding per hit in forward_learning.py's own entry shape, never edits the scanned repo, calls no private agentm function. src/research/group.yaml bumped 0.1.1 → 0.2.0. Flipped every (designed) / [PENDING-IMPL] marker in this doc to (delivered) for the scheduled half, and separately corrected a stale idea-search [PENDING-IMPL] marker left over from before that primitive shipped (unrelated to this plan; idea_search.py + its test suite already existed). Why worth recording precisely: this plan's own unblock condition was re-verified against real agentm artifacts, not design prose, before the session started — and two of the three original guesses had drifted (config is JSON against _meta/forward-learning-sources.json, not YAML; job registration is a real schema in templates/jobs/forward-learning.yaml against scripts/runner/manifest.py, not a mockable Scheduler object). Re-audit trigger: if agentm changes either shape again, re-verify learn_forward.py / agentm_bridge.py against the new shape before trusting this doc's file references.
2026-07-07 — corrected the how-we-engineer binding claim; no real prose site exists (PLAN-wave-d-personas task 1 grounding pass). src/research/ carries exactly two files (scripts/agentm_bridge.py, scripts/idea_search.py) — zero skill/command markdown, so there is no static-prose site for the grammar to bind. Reworded "Opinions it consumes" above from "hardwired today" (implying a real, undeclared binding waiting on request-by-name plumbing) to state plainly that no grounded binding exists yet — the same shape PLAN.archive.20260707-opinion-consumer-grammar.md task 4 already found for maintenance/wiki. Why not author the missing prose here: out of this plan's scope (the consumer grammar, not net-new opinion-standard content) — deferred to whoever next substantively touches research. Re-audit trigger: if a future change adds real how-we-engineer-shaped prose to a shipped src/research/ file, reclassify this as a grounded binding and wire it via the markdown-prose consumer grammar (composition).
2026-06-28 — lock-down sweep (operator review). Converted the two-modes mermaid to a house-style hand-SVG (diagrams/crickets-research.svg); and, per operator review, removed the public / operator-personal posture discussion from the body, Risks, re-audit, and this log (the deep-research forward-reference mechanism stays). Confirmed the two modes — on-demand (built) and scheduled forward-learning (designed, leaning by name on agentm's forward-experience substrate). Locked as a v5–v8 guidepost.
2026-06-23 — added the two-modes diagram (diagram backfill). Per the every-design-carries-a-diagram rule.
2026-06-23 — added an Opinions-it-consumes clause (portfolio backfill). Made explicit that research leans on how-we-engineer (it feeds the sizing ladder) — a standard Design clause adopted across the capability designs.
2026-06-23 — authored, reviewed, and finalized.
The research capability brings in what the agent hasn't seen, in two modes. On-demand: explorer + researcher (delivered read-only agents) and a new idea-search (greenfield, over the recall engine). Scheduled forward-learning: learn-forward + codebase-improvement (designed) — both lean by name on agentm's unbuilt scheduler + approved-source pipeline, surfacing findings to the idea incubator/watchlist, never auto-adopting. The adapt-don't-import seam stays one-way (discovery → watchlist → operator-gate). The first slice is the two agents + idea-search, with no dependency on unbuilt infrastructure. Deep multi-source research is forward-referenced: researcher references an operator-personal deep-research agent by name and contract.
Operator decisions (2026-06-23): research owns researcher; deep multi-source work is forward-referenced to an operator-personal agent (by name + contract); the scheduled + on-demand halves stay one capability, one design (not a split). Conformed to the per-primitive operational contract with (delivered) / (greenfield) / (designed) markers, and fixed a composition-lint violation (the draft both requires and enhances development-lifecycle → corrected to enhances, since research works standalone). Built-vs-designed: the two agents delivered; idea-search + the scheduled half greenfield/blocked on the agentm scheduler. Re-audit triggers: flip [PENDING-IMPL] as idea-search then the scheduled workflows land; revisit the forward-reference approach only if it proves insufficient in real use.