Review ICRT - Heungwoo/research GitHub Wiki
In-Depth Review — ICRT: In-Context Imitation Learning via Next-Token Prediction
Paper: "In-Context Imitation Learning via Next-Token Prediction" — arXiv 2408.15980 · ICRA 2025 · UC Berkeley (Letian Fu et al.) · code. The foundational token-sequence datapoint of in-context imitation — a causal transformer over sensorimotor trajectories that learns a new task from a prompt of demonstrations at test time, no fine-tuning, no language, no reward. Companions: In-Context Imitation (this is its cluster-E anchor) · RoboSSM · Behavior Prompting · MimicDroid.
1. Problem
Robots should learn a new task by being shown a few demonstrations at test time — the way LLMs do in-context learning — without updating policy parameters and without language or reward supervision. The question ICRT answers: can next-token prediction over raw sensorimotor trajectories give a real robot this in-context ability?
2. Method
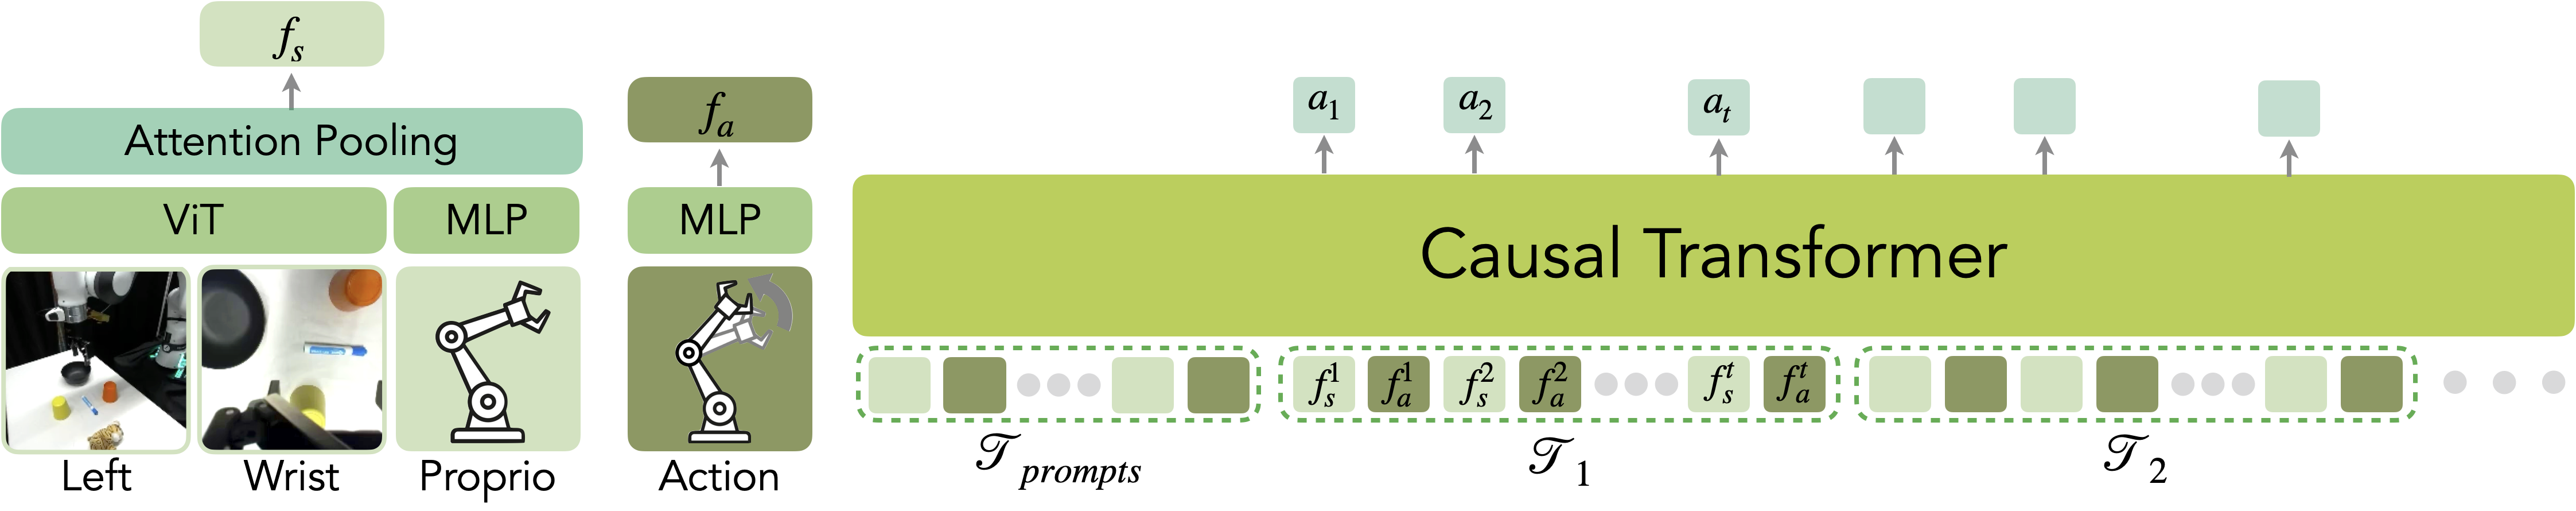
ICRT is a causal transformer trained by autoregressive prediction on sensorimotor trajectories (image observations, proprioceptive states, actions) — no linguistic data, no reward.
- Tokenization: multi-view images (third-person + wrist) → ViT → attention pooling → a state token
f_s; proprioception → MLP; each action → MLP →f_a. A trajectory becomes an interleaved[f_s¹, f_a¹, f_s², f_a², …]sequence. - Prompt-then-rollout as one sequence: at test time the model is prompted with the new task's trajectory tokens (
𝒯_prompts), then continues the sequence — autoregressively emitting actions for the current rollout (𝒯₁, 𝒯₂, …). This is training-free task specification — the task is the prompt, not a gradient step. - Training data: teleoperated multi-task trajectories; the model learns how to imitate from context, not any single task.
3. Results
- On a Franka Emika robot, ICRT adapts to new tasks specified purely by the prompt, even in environment configurations different from both the prompt and the training data.
- In a multitask setup, ICRT significantly outperforms prior next-token-prediction robot models on generalizing to unseen tasks.
4. Why it matters (in-context lens)
ICRT is the anchor of cluster E (token-sequence ICL) in In-Context Imitation — it established that LLM-style next-token prediction over [demo; rollout] tokens gives a real robot genuine in-context imitation, with no language, no reward, no test-time training. Everything after refines this recipe:
- RoboSSM swaps ICRT's Transformer for an SSM to fix its long-prompt collapse (in RoboSSM's own experiments ICRT degrades to ~0 as demos grow past training length — the direct motivation).
- ICLR: Visual Reasoning adds image-space intent traces to ICRT-style prompts (action-only → action+intent).
- Behavior Prompting and MimicDroid attack ICRT's data bottleneck (teleop → handheld interface / human play video).
So ICRT is best read as the reference point the newer in-context papers improve on — architecture (SSM), prompt content (visual reasoning), and data source (video/handheld).
Limitations. Transformer prompt length caps how many/long demos help — degrades past the training length (RoboSSM's finding); needs teleoperated training trajectories (the scalability wall Behavior Prompting/MimicDroid target); no language conditioning, so tasks must be shown, not told.
5. Links
- Paper: arXiv 2408.15980 · HF · code · IEEE Xplore
- Family: In-Context Imitation (cluster E) · RoboSSM · Behavior Prompting · MimicDroid · ICLR: Visual Reasoning
← Back to In-Context Imitation · Reviews · Home