ICML 2026 Move Then Operate - Heungwoo/research GitHub Wiki
Move-Then-Operate: Behavioral Phasing for Human-Like Robotic Manipulation — A dual-expert VLA that splits coarse relocation from contact-critical interaction
Venue: ICML 2026 (Poster) Category: VLA Architecture Traction (2026-06): 0 citations (arXiv)

Problem
Monolithic VLA policies use a single network to handle two very different behavioral regimes: coarse relocation ("move" — transporting the end-effector through free space) and contact-critical interaction ("operate" — fine, high-precision manipulation against an object). Conflating these heterogeneous dynamics creates optimization interference, where gradients for free-space transit and gradients for delicate contact conflict. Move-Then-Operate asks whether explicitly disentangling these phases is a more effective and data-efficient inductive bias, aligning the policy with human motor patterns.
Method
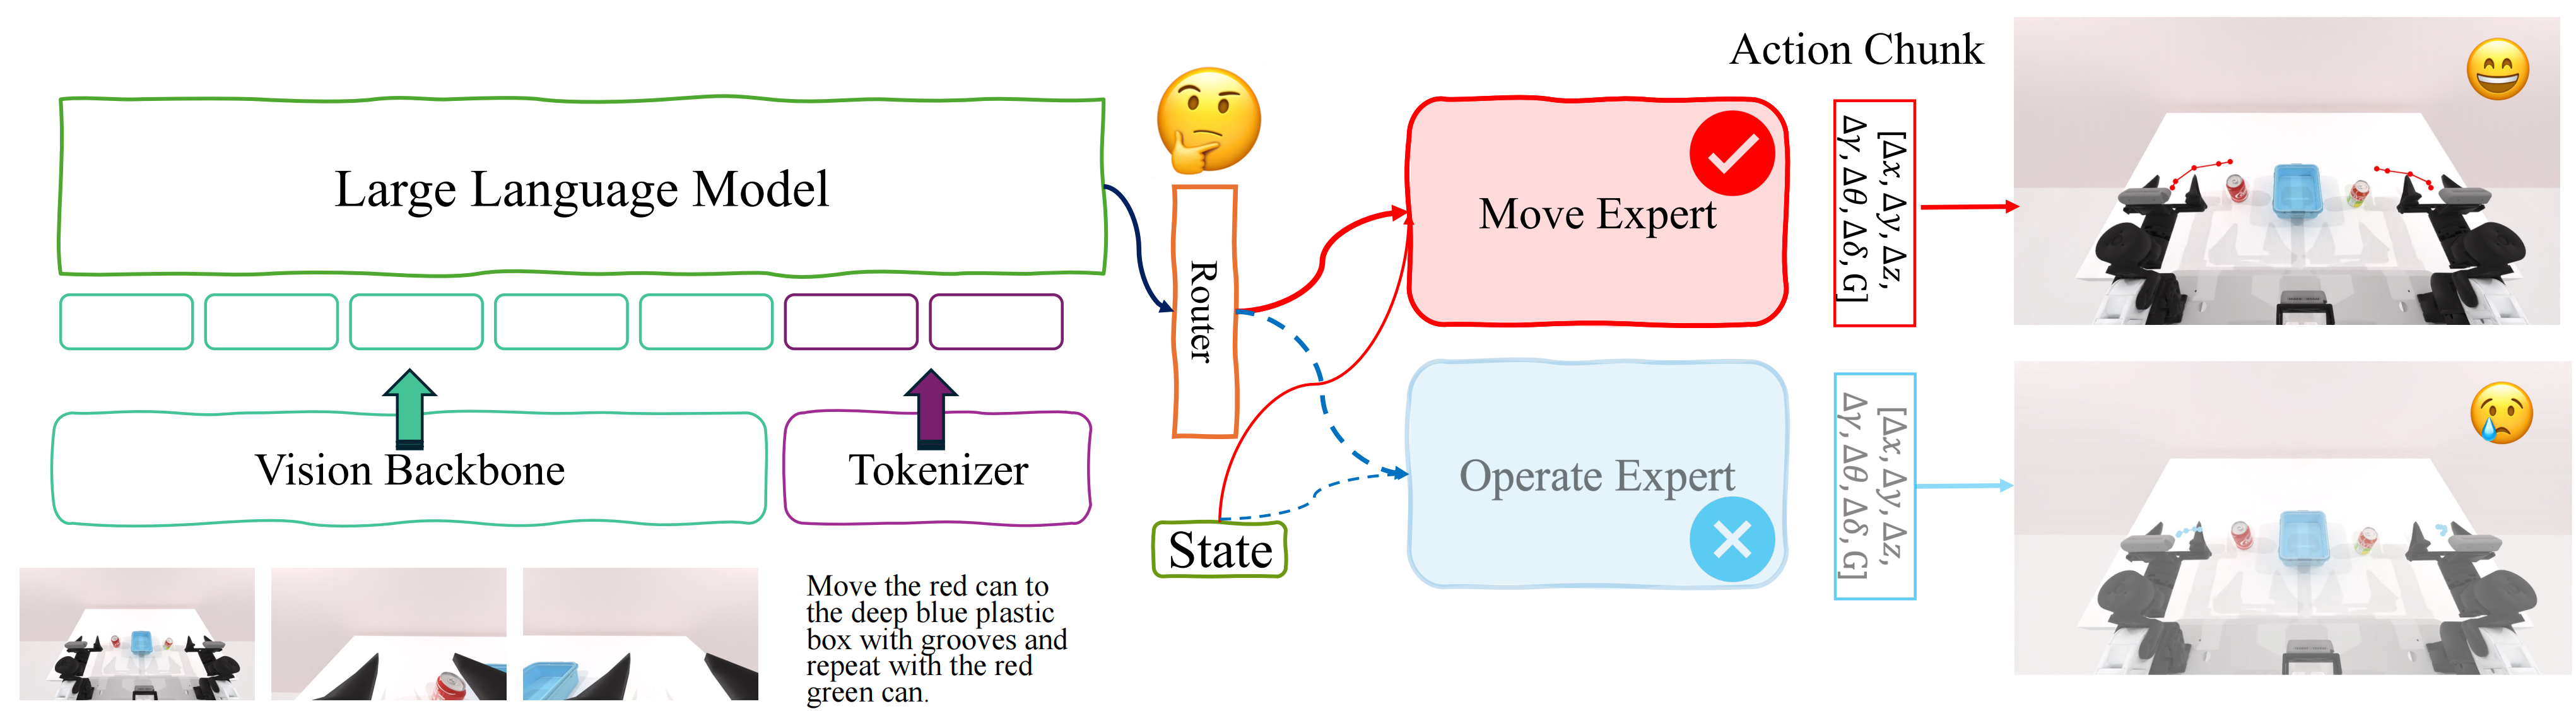
The architecture is a dual-expert policy built on a flow-matching (conditional flow matching) VLA. A shared vision-language encoder feeds two expert heads, E_move and E_operate, which share the base architecture but keep disjoint parameters so that conflicting gradient updates between coarse transit and fine manipulation are isolated.
- A latent variable z ∈ {Move, Operate} performs hard routing: a single expert defines the entire vector field, and the selection stays invariant across the whole flow-integration interval σ ∈ [0,1] for each generated action chunk.
- Routing is done per action chunk by a learnable phase selector trained with supervised routing learning.
- Phase-aware auto-labeling: an MLLM ℳ takes the demonstration video and instruction and predicts a hierarchical schedule of N consecutive subtasks, each decomposed into atomic phases of type {Move, Operate}. Topological constraints (e.g., decomposition depth ≤ 2 per subtask) enforce physically plausible labels conditioned on lightweight cues such as end-effector velocity.
Results
On the RoboTwin2 benchmark with a constrained budget of 50 demonstrations per task, Move-Then-Operate reaches a 68.9% average success rate, outperforming the monolithic π₀ baseline by +24.1%. Gains concentrate on high-precision tasks: +55% on Click Bell and +8% on Press Stapler over the next-best method, and long-horizon Place Cans improves from 64% → 79%.
The method is also data- and compute-efficient: trained on only 50 tasks × 50 demos (100,000 steps, no per-task fine-tuning), it matches or exceeds π₀.₅* and GO-1* trained on ~10× more data, and reaches peak performance in 40% fewer training steps. An ablation confirms the routing is load-bearing — replacing the learned router with Random Selection collapses success from 68.88% to 25.63%, and an adversarial Reversal Selection drops it to 8.88%, showing the two experts specialize in distinct, incompatible behaviors.
Significance
Move-Then-Operate demonstrates that a simple structural prior — separating "move" from "operate" with disjoint experts and a learned per-chunk router — substantially mitigates optimization interference in VLAs, yielding strong precision gains while being markedly more data- and training-efficient than scaling data. The MLLM auto-labeling pipeline makes the phase supervision cheap to obtain.
Links
- arXiv: 2604.23620
- ICML 2026: https://icml.cc/virtual/2026/poster/65496
← Back to ICML-2026