ICML 2026 LARA - Heungwoo/research GitHub Wiki
LARA — Latent Action Representation Alignment for VLA Models
Venue: ICML 2026 (Poster) Category: VLA Architecture Affiliations: Authors: Mengya Liu, Baoxiong Jia, Jiangyong Huang, Jingze Zhang, Siyuan Huang Traction (2026-06): 0 citations (arXiv)

Problem
VLA models predict actions directly from observations and language but depend on large-scale, high-quality robot data, which is scarce and costly. Latent Action Models (LAMs) learn latent action representations from the visual dynamics of abundant unlabeled human videos to provide extra supervision for VLA training. However, LAM and VLA are typically trained separately: the LAM stays ungrounded during VLA training (it never sees real action trajectories), while the VLA is constrained by frozen LAM representations. This one-way coupling leaves both models suboptimal.
Method
LARA (Latent Action Representation Alignment) is a plug-and-play framework that jointly optimizes the LAM and the VLA via representation alignment (Figure 2 vs. prior pseudo-label usage).
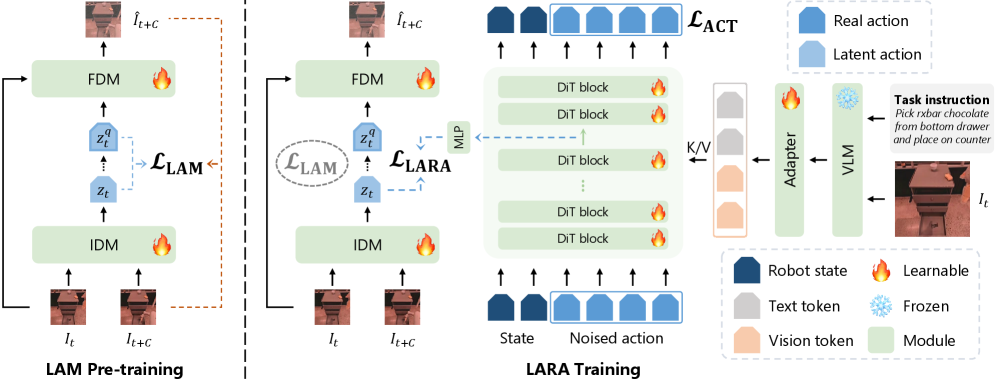
- Diffusion-as-encoder/decoder view. The flow-matching VLA
v_θ(A_t^τ, c_t)is treated as an encoder–decoderE_θ ∘ D_θ. The encoder extracts an intermediate latenth_t^θ(features between DiT layers) that the decoder uses to predict the target velocityv_t = A_t − ε. - Representation alignment. Inspired by REPA-style alignment in image diffusion, LARA aligns
h_t^θto a pretrained action representation via a cosine-similarity loss through a learnable projection headf_ψ. Crucially, instead of a frozen embedding, LARA uses the online LAM latent actionz_tas the alignment target, enabling joint training of the LAM and the action diffusion model. - Bi-directional regularization. The reciprocal coupling means LAMs learn with action trajectories to avoid spurious visual changes, while VLAs are regularized by the forward dynamics learned inside the LAM to reduce hallucinations of functionally ineffective trajectories.
LARA supports three usage modes: pre-training, post-training enhancement of existing VLAs (e.g. GR00T-N1.6), and latent-action refinement for LAM-based VLAs.
Results
Evaluated on LIBERO, SIMPLER-ENV, GR1-Sim-24(30), and a real-world Unitree G1 humanoid benchmark (G1-Real(50)), under both OXE-Constrained and Unconstrained settings (Tables 1–2):
- Full training (OXE-Constrained, Table 1): LARA (full) reaches LIBERO average 88.6 (vs. LARA DiT-only 84.4) and SIMPLER-ENV average 65.2, improving LIBERO-Long by +12.4% and SIMPLER-ENV average by +16.8% over DiT-only.
- Post-training enhancement: GR00T-N1.6-LARA edges out the strong GR00T-N1.6 baseline (LIBERO 95.6 vs. 95.0; SIMPLER-ENV 79.9 vs. 78.9), a ~+0.6–1.3% gain on already-saturated benchmarks.
- GR1-Sim & real-world G1 (Table 2): joint training lifts GR1-Sim-24 from 6.4 → 11.4 (+78.1%) and real-world G1 average from 56.0 → 74.0 (+32.1%); post-training GR00T-N1.6-LARA improves full real-world tasks (e.g. Pick-n-Place full 76→84).
The reported headline averages are ~10% (pre-training), ~5% (post-training), and ~15% (LAM refinement) improvements across the benchmarks. Ablations study alignment depth and joint optimization vs. a frozen LAM, confirming the joint design matters.
Significance
LARA shows that the LAM↔VLA relationship should be bidirectional and jointly optimized, not a one-shot pseudo-labeling step. By aligning diffusion intermediate features to online latent actions, it grounds the LAM in real trajectories and regularizes the VLA against hallucinated motions — a simple, plug-and-play recipe that boosts pre-training, post-training, and LAM refinement, including on a real humanoid.
Links
- arXiv: 2606.07100
- ICML 2026: https://icml.cc/virtual/2026/poster/61232
← Back to ICML-2026