Simple RNN & Gated Recurrent Unit - Avesta-Ahmadi/Univariate-Time-Series-Forecasting GitHub Wiki
Simple RNN unit has been used as another approach in memory based networks. In the simple RNN approach, each block in the hidden layer will pass its value to the next block in the same layer and also to the next hidden layer. The schematic of a RNN layer is demonstrated in the following graph.
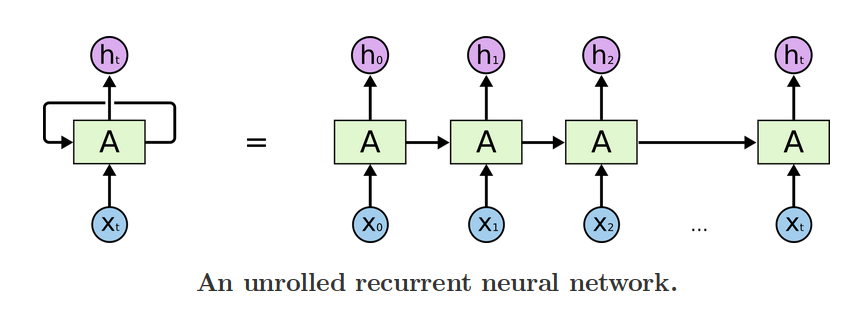
Source: http://colah.github.io/posts/2015-08-Understanding-LSTMs/
A network of RNN layers have been trained and hyper parameters have been adjusted for each particular time series.
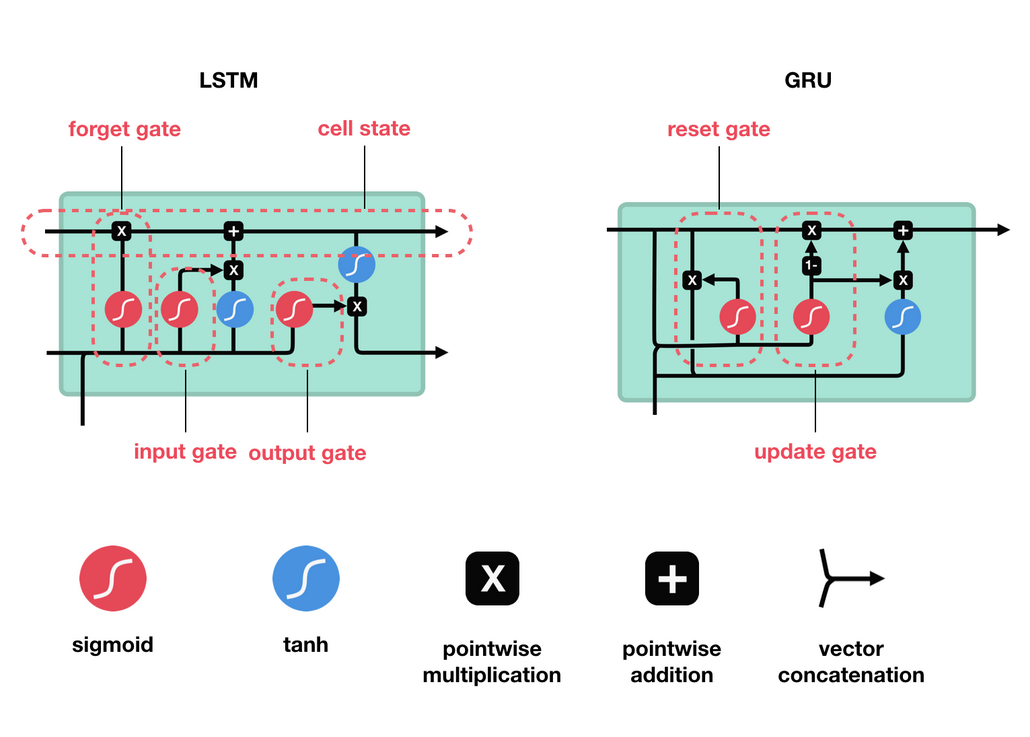
As an alternative approach, gated recurrent unit have been utilized. The following graph compared the structure of a GRU cell with a LSTM cell. The GRU cell is composed of reset and update gates. These gates will decide which part of the sequence is important to preserve or to throw away. A network of stacked layers of GRU will be used for training the model and one-step ahead forecasting. The hyper parameters will be adjusted for each particular time series data.